Archiwum kategorii: CSS

A Primer on the Different Types of Browser Storage

Post pobrano z: A Primer on the Different Types of Browser Storage

In back-end development, storage is a common part of the job. Application data is stored in databases, files in object storage, transient data in caches… there are seemingly endless possibilities for storing any sort of data. But data storage isn’t limited only to the back end. The front end (the browser) is equipped with many options to store data as well. We can boost our application performance, save user preferences, keep the application state across multiple sessions, or even different computers, by utilizing this storage.

In this article, we will go through the different possibilities to store data in the browser. We will cover three use cases for each method to grasp the pros and cons. In the end, you will be able to decide what storage is the best fit for your use case. So let’s start!

The localStorage API

localStorage is one of the most popular storage options in the browser and the go-to for many developers. The data is stored across sessions, never shared with the server, and is available for all pages under the same protocol and domain. Storage is limited to ~5MB.

Surprisingly, the Google Chrome team doesn’t recommend using this option as it blocks the main thread and is not accessible to web workers and service workers. They launched an experiment, KV Storage, as a better version, but it was just a trial that doesn’t seem to have gone anywhere just yet.

The localStorage API is available as window.localStorage and can save only UTF-16 strings. We must make sure to convert data to strings before saving it into localStorage. The main three functions are:

  • setItem('key', 'value')
  • getItem('key')
  • removeItem('key')

They’re all synchronous, which makes it simple to work with, but they block the main thread.

It’s worth mentioning that localStorage has a twin called sessionStorage. The only difference is that data stored in sessionStorage will last only for the current session, but the API is the same.

Let’s see it in action. The first example demonstrates how to use localStorage for storing the user’s preferences. In our case, it’s a boolean property that turns on or off the dark theme of our site.

CodePen Embed Fallback

You can check the checkbox and refresh the page to see that the state is saved across sessions. Take a look at the save and load functions to see how I convert the value to string and how I parse it. It’s important to remember that we can store only strings.

This second example loads Pokémon names from the PokéAPI.

CodePen Embed Fallback

We send a GET request using fetch and list all the names in a ul element. Upon getting the response, we cache it in the localStorage so our next visit can be much faster or even work offline. We have to use JSON.stringify to convert the data to string and JSON.parse to read it from the cache.

In this last example, I demonstrate a use case where the user can browse through different Pokémon pages, and the current page is saved for the next visits.

CodePen Embed Fallback

The issue with localStorage, in this case, is that the state is saved locally. This behavior doesn’t allow us to share the desired page with our friends. Later, we will see how to overcome this issue.

We will use these three examples in the next storage options as well. I forked the Pens and just changed the relevant functions. The overall skeleton is the same for all methods.

The IndexedDB API

IndexedDB is a modern storage solution in the browser. It can store a significant amount of structured data — even files, and blobs. Like every database, IndexedDB indexes the data for running queries efficiently. It’s more complex to use IndexedDB. We have to create a database, tables, and use transactions.

Compared to localStorage , IndexedDB requires a lot more code. In the examples, I use the native API with a Promise wrapper, but I highly recommend using third-party libraries to help you out. My recommendation is localForage because it uses the same localStorage API but implements it in a progressive enhancement manner, meaning if your browser supports IndexedDB, it will use it; and if not, it will fall back to localStorage.

Let’s code, and head over to our user preferences example!

CodePen Embed Fallback

idb is the Promise wrapper that we use instead of working with a low-level events-based API. They’re almost identical, so don’t worry. The first thing to notice is that every access to the database is async, meaning we don’t block the main thread. Compared to localStorage, this is a major advantage.

We need to open a connection to our database so it will be available throughout the app for reading and writing. We give our database a name, my-db, a schema version, 1, and an update function to apply changes between versions. This is very similar to database migrations. Our database schema is simple: only one object store, preferences. An object store is the equivalent of an SQL table. To write or read from the database, we must use transactions. This is the tedious part of using IndexedDB. Have a look at the new save and load functions in the demo.

No doubt that IndexedDB has much more overhead and the learning curve is steeper compared to localStorage. For the key value cases, it might make more sense to use localStorage or a third-party library that will help us be more productive.

CodePen Embed Fallback

Application data, such as in our Pokémon example, is the forte of IndexedDB. You can store hundreds of megabytes and even more in this database. You can store all the Pokémon in IndexedDB and have them available offline and even indexed! This is definitely the one to choose for storing app data.

I skipped the implementation of the third example, as IndexedDB doesn’t introduce any difference in this case compared to localStorage. Even with IndexedDB, the user will still not share the selected page with others or bookmark it for future use. They’re both not the right fit for this use case.

Cookies

Using cookies is a unique storage option. It’s the only storage that is also shared with the server. Cookies are sent as part of every request. It can be when the user browses through pages in our app or when the user sends Ajax requests. This allows us to create a shared state between the client and the server, and also share state between multiple applications in different subdomains. This is not possible by other storage options that are described in this article. One caveat: cookies are sent with every request, which means that we have to keep our cookies small to maintain a decent request size.

The most common use for cookies is authentication, which is out of the scope of this article. Just like the localStorage, cookies can store only strings. The cookies are concatenated into one semicolon-separated string, and they are sent in the cookie header of the request. You can set many attributes for every cookie, such as expiration, allowed domains, allowed pages, and many more.

In the examples, I show how to manipulate the cookies through the client-side, but it’s also possible to change them in your server-side application.

CodePen Embed Fallback

Saving the user’s preferences in a cookie can be a good fit if the server can utilize it somehow. For example, in the theme use case, the server can deliver the relevant CSS file and reduce potential bundle size (in case we’re doing server-side-rendering). Another use case might be to share these preferences across multiple subdomain apps without a database.

Reading and writing cookies with JavaScript is not as straightforward as you might think. To save a new cookie, you need to set document.cookie — check out the save function in the example above. I set the dark_theme cookie and add it a max-age attribute to make sure it will not expire when the tab is closed. Also, I add the SameSite and Secure attributes. These are necessary because CodePen uses iframe to run the examples, but you will not need them in most cases. Reading a cookie requires parsing the cookie string.

A cookie string looks like this:

key1=value1;key2=value2;key3=value3

So, first, we have to split the string by semicolon. Now, we have an array of cookies in the form of key1=value1, so we need to find the right element in the array. In the end, we split by the equal sign and get the last element in the new array. A bit tedious, but once you implement the getCookie function (or copy it from my example :P) you can forget it.

Saving application data in a cookie can be a bad idea! It will drastically increase the request size and will reduce application performance. Also, the server cannot benefit from this information as it’s a stale version of the information it already has in its database. If you use cookies, make sure to keep them small.

The pagination example is also not a good fit for cookies, just like localStorage and IndexedDB. The current page is a temporary state that we would like to share with others, and any of these methods do not achieve it.

URL storage

URL is not a storage, per se, but it’s a great way to create a shareable state. In practice, it means adding query parameters to the current URL that can be used to recreate the current state. The best example would be search queries and filters. If we search the term flexbox on CSS-Tricks, the URL will be updated to https://css-tricks.com/?s=flexbox. See how easy it is to share a search query once we use the URL? Another advantage is that you can simply hit the refresh button to get newer results of your query or even bookmark it.

We can save only strings in the URL, and its maximum length is limited, so we don’t have so much space. We will have to keep our state small. No one likes long and intimidating URLs.

Again, CodePen uses iframe to run the examples, so you cannot see the URL actually changing. Worry not, because all the bits and pieces are there so you can use it wherever you want.

CodePen Embed Fallback

We can access the query string through window.location.search and, lucky us, it can be parsed using the URLSearchParams class. No need to apply any complex string parsing anymore. When we want to read the current value, we can use the get function. When we want to write, we can use set. It’s not enough to only set the value; we also need to update the URL. This can be done using history.pushState or history.replaceState, depending on the behavior we want to accomplish.

I wouldn’t recommend saving a user’s preferences in the URL as we will have to add this state to every URL the user visits, and we cannot guarantee it; for example, if the user clicks on a link from Google Search.

Just like cookies, we cannot save application data in the URL as we have minimal space. And even if we did manage to store it, the URL will be long and not inviting to click. Might look like a phishing attack of sorts.

CodePen Embed Fallback

Just like our pagination example, the temporary application state is the best fit for the URL query string. Again, you cannot see the URL changes, but the URL updates with the ?page=x query parameter every time you click on a page. When the web page loads, it looks for this query parameter and fetches the right page accordingly. Now we can share this URL with our friends so they can enjoy our favorite Pokémon.

Cache API

Cache API is a storage for the network level. It is used to cache network requests and their responses. The Cache API fits perfectly with service workers. A service worker can intercept every network request, and using the Cache API, it can easily cache both the requests. The service worker can also return an existing cache item as a network response instead of fetching it from the server. By doing so, you can reduce network load times and make your application work even when offline. Originally, it was created for service workers but in modern browsers the Cache API is available also in window, iframe, and worker contexts as-well. It’s a very powerful API that can improve drastically the application user experience.

Just like IndexedDB the Cache API storage is not limited and you can store hundreds of megabytes and even more if you need to. The API is asynchronous so it will not block your main thread. And it’s accessible through the global property caches.

To read more about the Cache API, the Google Chrome team has made a great tutorial.

Chris created an awesome Pen with a practical example of combining service workers and the Cache API.

Bonus: Browser extension

If you build a browser extension, you have another option to store your data. I discovered it while working on my extension, daily.dev. It’s available via chrome.storage or browser.storage, if you use Mozilla’s polyfill. Make sure to request a storage permission in your manifest to get access.

There are two types of storage options, local and sync. The local storage is self-explanatory; it means it isn’t shared and kept locally. The sync storage is synced as part of the Google account and anywhere you install the extension with the same account this storage will be synced. Pretty cool feature if you ask me. Both have the same API so it’s super easy to switch back-and-forth, if needed. It’s async storage so it doesn’t block the main thread like localStorage. Unfortunately, I cannot create a demo for this storage option as it requires a browser extension but it’s pretty simple to use, and almost like localStorage. For more information about the exact implementation, refer to Chrome docs.

Conclusion

The browser has many options we can utilize to store our data. Following the Chrome team’s advice, our go-to storage should be IndexedDB. It’s async storage with enough space to store anything we want. localStorage is not encouraged, but is easier to use than IndexedDB. Cookies are a great way to share the client state with the server but are mostly used for authentication.

If you want to create pages with a shareable state such as a search page, use the URL’s query string to store this information. Lastly, if you build an extension, make sure to read about chrome.storage.


The post A Primer on the Different Types of Browser Storage appeared first on CSS-Tricks.

You can support CSS-Tricks by being an MVP Supporter.

xm

Post pobrano z: xm

This is a neat little HTML preprocessor from Giuseppe Gurgone. It has very few features, but one of them is HTML includes, which is something I continue to be baffled that HTML doesn’t support natively. There are loads of ways to handle it. I think it’s silly that it’s been consistently needed for decades and HTML could evolve to support it but hasn’t. So anyway, enter another option for handling it.

📢 Today I am open sourcing ✨ ₪ xm ✨ a tiny compiler for HTML that adds support for

imports
slots & fills
a portal to markdown

🔗 https://t.co/mhrlVGg3Wp
⌨️ npm i -g xm && xm dev pic.twitter.com/pYN9RpodsW

— Giuseppe (@giuseppegurgone) September 15, 2020

What is extra neat is that it’s not just includes, but templating with includes in a really clean way. If this was Nunjucks, they solve that by creating a template.njk like…

{% block header %}
  This is the default (overridable) header.
{% endblock %}
<footer>
  {% block footer %}
    This is the default (overridable) footer.
  {% endblock %}
</footer>

And then your actual pages use that template like…

{% extends "parent.html" %}
{% block footer %}
  Special footer for this page.
{% endblock %}

In xm, the syntax stays HTML-y, which is nice. So this template.html…

<slot name="header"></slot>
<footer>
  <slot name="footer"></slot>
</footer>

…gets used on a page like this:

<import src="template.html">
  <fill name="header">Custom Header</fill>
  <fill name="footer">
    <p>Custom footer</p>
  </fill>
</import>

Very clean. The additional fact that you can arbitrarily chuck a <markdown> tag anywhere you want and use Markdown within it is extra handy.


The post xm appeared first on CSS-Tricks.

You can support CSS-Tricks by being an MVP Supporter.

How to Think Like a Front-End Developer

Post pobrano z: How to Think Like a Front-End Developer

This is an extended version of my essay “When front-end means full-stack” which was published in the wonderful Increment magazine put out by Stripe. It’s also something of an evolution of a couple other of my essays, “The Great Divide” and “Ooops, I guess we’re full-stack developers now.”

The moment I fell in love with front-end development was when I discovered the style.css file in WordPress themes. That’s where all the magic was (is!) to me. I could (can!) change a handful of lines in there and totally change the look and feel of a website. It’s an incredible game to play.

Back when I was cowboy-coding over FTP. Although I definitely wasn’t using CSS grid!

By fiddling with HTML and CSS, I can change the way you feel about a bit of writing. I can make you feel more comfortable about buying tickets to an event. I can increase the chances you share something with your friends.

That was well before anybody paid me money to be a front-end developer, but even then I felt the intoxicating mix of stimuli that the job offers. Front-end development is this expressive art form, but often constrained by things like the need to directly communicate messaging and accomplish business goals.

Front-end development is at the intersection of art and logic. A cross of business and expression. Both left and right brain. A cocktail of design and nerdery.

I love it.

Looking back at the courses I chose from middle school through college, I bounced back and forth between computer-focused classes and art-focused classes, so I suppose it’s no surprise I found a way to do both as a career.

The term “Front-End Developer” is fairly well-defined and understood. For one, it’s a job title. I’ll bet some of you literally have business cards that say it on there, or some variation like: “Front-End Designer,” “UX Developer,” or “UI Engineer.” The debate around what those mean isn’t particularly interesting to me. I find that the roles are so varied from job-to-job and company-to-company that job titles will never be enough to describe things. Getting this job is more about demonstrating you know what you’re doing more than anything else¹.

Chris Coyier
Front-End Developer

The title variations are just nuance. The bigger picture is that as long as the job is building websites, front-enders are focused on the browser. Quite literally:

  • front-end = browsers
  • back-end = servers

Even as the job has changed over the decades, that distinction still largely holds.

As “browser people,” there are certain truths that come along for the ride. One is that there is a whole landscape of different browsers and, despite the best efforts of standards bodies, they still behave somewhat differently. Just today, as I write, I dealt with a bug where a date string I had from an API was in a format such that Firefox threw an error when I tried to use the .toISOString() JavaScript API on it, but was fine in Chrome. That’s just life as a front-end developer. That’s the job.

Even across that landscape of browsers, just on desktop computers, there is variance in how users use that browser. How big do they have the window open? Do they have dark mode activated on their operating system? How’s the color gamut on that monitor? What is the pixel density? How’s the bandwidth situation? Do they use a keyboard and mouse? One or the other? Neither? All those same questions apply to mobile devices too, where there is an equally if not more complicated browser landscape. And just wait until you take a hard look at HTML emails.

That’s a lot of unknowns, and the answers to developing for that unknown landscape is firmly in the hands of front-end developers.

Into the unknoooooowwwn. – Elsa

The most important aspect of the job? The people that use these browsers. That’s why we’re building things at all. These are the people I’m trying to impress with my mad CSS skills. These are the people I’m trying to get to buy my widget. Who all my business charts hinge upon. Who’s reaction can sway my emotions like yarn in the breeze. These users, who we put on a pedestal for good reason, have a much wider landscape than the browsers do. They speak different languages. They want different things. They are trying to solve different problems. They have different physical abilities. They have different levels of urgency. Again, helping them is firmly in the hands of front-end developers. There is very little in between the characters we type into our text editors and the users for whom we wish to serve.

Being a front-end developer puts us on the front lines between the thing we’re building and the people we’re building it for, and that’s a place some of us really enjoy being.

That’s some weighty stuff, isn’t it? I haven’t even mentioned React yet.

The “we care about the users” thing might feel a little precious. I’d think in a high functioning company, everyone would care about the users, from the CEO on down. It’s different, though. When we code a <button>, we’re quite literally putting a button into a browser window that users directly interact with. When we adjust a color, we’re adjusting exactly what our sighted users see when they see our work.

That’s not far off from a ceramic artist pulling a handle out of clay for a coffee cup. It’s applying craftsmanship to a digital experience. While a back-end developer might care deeply about the users of a site, they are, as Monica Dinculescu once told me in a conversation about this, “outsourcing that responsibility.”


We established that front-end developers are browser people. The job is making things work well in browsers. So we need to understand the languages browsers speak, namely: HTML, CSS, and JavaScript². And that’s not just me being some old school fundamentalist; it’s through a few decades of everyday front-end development work that knowing those base languages is vital to us doing a good job. Even when we don’t work directly with them (HTML might come from a template in another language, CSS might be produced from a preprocessor, JavaScript might be mostly written in the parlance of a framework), what goes the browser is ultimately HTML, CSS, and JavaScript, so that’s where debugging largely takes place and the ability of the browser is put to work.

CSS will always be my favorite and HTML feels like it needs the most love — but JavaScript is the one we really need to examine The last decade has seen JavaScript blossom from a language used for a handful of interactive effects to the predominant language used across the entire stack of web design and development. It’s possible to work on websites and writing nothing but JavaScript. A real sea change.

JavaScript is all-powerful in the browser. In a sense, it supersedes HTML and CSS, as there is nothing either of those languages can do that JavaScript cannot. HTML is parsed by the browser and turned into the DOM, which JavaScript can also entirely create and manipulate. CSS has its own model, the CSSOM, that applies styles to elements in the DOM, which JavaScript can also create and manipulate.

This isn’t quite fair though. HTML is the very first file that browsers parse before they do the rest of the work needed to build the site. That firstness is unique to HTML and a vital part of making websites fast.

In fact, if the HTML was the only file to come across the network, that should be enough to deliver the basic information and functionality of a site.

That philosophy is called Progressive Enhancement. I’m a fan, myself, but I don’t always adhere to it perfectly. For example, a <form> can be entirely functional in HTML, when it’s action attribute points to a URL where the form can be processed. Progressive Enhancement would have us build it that way. Then, when JavaScript executes, it takes over the submission and has the form submit via Ajax instead, which might be a nicer experience as the page won’t have to refresh. I like that. Taken further, any <button> outside a form is entirely useless without JavaScript, so in the spirit of Progressive Enhancement, I should wait until JavaScript executes to even put that button on the page at all (or at least reveal it). That’s the kind of thing where even those of us with the best intentions might not always toe the line perfectly. Just put the button in, Sam. Nobody is gonna die.

JavaScript’s all-powerfulness makes it an appealing target for those of us doing work on the web — particularly as JavaScript as a language has evolved to become even more powerful and ergonomic, and the frameworks that are built in JavaScript become even more-so. Back in 2015, it was already so clear that JavaScript was experiencing incredible growth in usage, Matt Mullenweg, co-founder of WordPress, gave the developer world homework: “Learn JavaScript Deeply”³. He couldn’t have been more right. Half a decade later, JavaScript has done a good job of taking over front-end development. Particularly if you look at front-end development jobs.

While the web almanac might show us that only 5% of the top-zillion sites use React compared to 85% including jQuery, those numbers are nearly flipped when looking around at front-end development job requirements.

I’m sure there are fancy economic reasons for all that, but jobs are as important and personal as it gets for people, so it very much matters.


So we’re browser people in a sea of JavaScript building things for people. If we take a look at the job at a practical day-to-day tasks level, it’s a bit like this:

  • Translate designs into code
  • Think in terms of responsive design, allowing us to design and build across the landscape of devices
  • Build systemically. Construct components and patterns, not one-offs.
  • Apply semantics to content
  • Consider accessibility
  • Worry about the performance of the site. Optimize everything. Reduce, reuse, recycle.

Just that first bullet point feels like a college degree to me. Taken together, all of those points certainly do.

This whole list is a bit abstract though, so let’s apply it to something we can look at. What if this website was our current project?

Our brains and fingers go wild!

  • Let’s build the layout with CSS grid. 
  • What fonts are those? Do we need to load them in their entirety or can we subset them? What happens as they load in? This layout feels like it will really suffer from font-shifting jank. 
  • There are some repeated patterns here. We should probably make a card design pattern. Every website needs a good card pattern. 
  • That’s a gorgeous color scheme. Are the colors mathematically related? Should we make variables to represent them individually or can we just alter a single hue as needed? Are we going to use custom properties in our CSS? Colors are just colors though, we might not need the cascading power of them just for this. Should we just use Sass variables? Are we going to use a CSS preprocessor at all?
  • The source order is tricky here. We need to order things so that they make sense for a screen reader user. We should have a meeting about what the expected order of content should be, even if we’re visually moving things around a bit with CSS grid.
  • The photographs here are beautifully shot. But some of them match the background color of the site… can we get away with alpha-transparent PNGs here? Those are always so big. Can any next-gen formats help us? Or should we try to match the background of a JPG with the background of the site seamlessly. Who’s writing the alt text for these?
  • There are some icons in use here. Inline SVG, right? Certainly SVG of some kind, not icon fonts, right? Should we build a whole icon system? I guess it depends on how we’re gonna be building this thing more broadly. Do we have a build system at all?
  • What’s the whole front-end plan here? Can I code this thing in vanilla HTML, CSS, and JavaScript? Well, I know I can, but what are the team expectations? Client expectations? Does it need to be a React thing because it’s part of some ecosystem of stuff that is already React? Or Vue or Svelte or whatever? Is there a CMS involved?
  • I’m glad the designer thought of not just the “desktop” and “mobile” sizes but also tackled an in-between size. Those are always awkward. There is no interactivity information here though. What should we do when that search field is focused? What gets revealed when that hamburger is tapped? Are we doing page-level transitions here?

I could go on and on. That’s how front-end developers think, at least in my experience and in talking with my peers.

A lot of those things have been our jobs forever though. We’ve been asking and answering these questions on every website we’ve built for as long as we’ve been doing it. There are different challenges on each site, which is great and keeps this job fun, but there is a lot of repetition too.

Allow me to get around to the title of this article. 

While we’ve been doing a lot of this stuff for ages, there is a whole pile of new stuff we’re starting to be expected to do, particularly if we’re talking about building the site with a modern JavaScript framework. All the modern frameworks, as much as they like to disagree about things, agree about one big thing: everything is a component. You nest and piece together components as needed. Even native JavaScript moves toward its own model of Web Components.

I like it, this idea of components. It allows you and your team to build the abstractions that make the most sense to you and what you are building.

Your Card component does all the stuff your card needs to do. Your Form component does forms how your website needs to do forms. But it’s a new concept to old developers like me. Components in JavaScript have taken hold in a way that components on the server-side never did. I’ve worked on many a WordPress website where the best I did was break templates into somewhat arbitrary include() statements. I’ve worked on Ruby on Rails sites with partials that take a handful of local variables. Those are useful for building re-usable parts, but they are a far cry from the robust component models that JavaScript frameworks offer us today.

All this custom component creation makes me a site-level architect in a way that I didn’t use to be. Here’s an example. Of course I have a Button component. Of course I have an Icon component. I’ll use them in my Card component. My Card component lives in a Grid component that lays them out and paginates them. The whole page is actually built from components. The Header component has a SearchBar component and a UserMenu component. The Sidebar component has a Navigation component and an Ad component. The whole page is just a special combination of components, which is probably based on the URL, assuming I’m all-in on building our front-end with JavaScript. So now I’m dealing with URLs myself, and I’m essentially the architect of the entire site. [Sweats profusely]

Like I told ya, a whole pile of new responsibility.

Components that are in charge of displaying content are almost certainly not hard-coded with data in them. They are built to be templates. They are built to accept data and construct themselves based on that data. In the olden days, when we were doing this kind of templating, the data has probably already arrived on the page we’re working on. In a JavaScript-powered app, it’s more likely that that data is fetched by JavaScript. Perhaps I’ll fetch it when the component renders. In a stack I’m working with right now, the front end is in React, the API is in GraphQL and we use Apollo Client to work with data. We use a special “hook” in the React components to run the queries to fetch the data we need, and another special hook when we need to change that data. Guess who does that work? Is it some other kind of developer that specializes in this data layer work? No, it’s become the domain of the front-end developer.

Speaking of data, there is all this other data that a website often has to deal with that doesn’t come from a database or API. It’s data that is really only relevant to the website at this moment in time.

  • Which tab is active right now?
  • Is this modal dialog open or closed?
  • Which bar of this accordion is expanded?
  • Is this message bar in an error state or warning state?
  • How many pages are you paginated in?
  • How far is the user scrolled down the page?

Front-end developers have been dealing with that kind of state for a long time, but it’s exactly this kind of state that has gotten us into trouble before. A modal dialog can be open with a simple modifier class like <div class="modal is-open"> and toggling that class is easy enough with .classList.toggle(".is-open"); But that’s a purely visual treatment. How does anything else on the page know if that modal is open or not? Does it ask the DOM? In a lot of jQuery-style apps of yore, yes, it would. In a sense, the DOM became the “source of truth” for our websites. There were all sorts of problems that stemmed from this architecture, ranging from a simple naming change destroying functionality in weirdly insidious ways, to hard-to-reason-about application logic making bug fixing a difficult proposition.

Front-end developers collectively thought: what if we dealt with state in a more considered way? State management, as a concept, became a thing. JavaScript frameworks themselves built the concept right in, and third-party libraries have paved and continue to pave the way. This is another example of expanding responsibility. Who architects state management? Who enforces it and implements it? It’s not some other role, it’s front-end developers.

There is expanding responsibility in the checklist of things to do, but there is also work to be done in piecing it all together. How much of this state can be handled at the individual component level and how much needs to be higher level? How much of this data can be gotten at the individual component level and how much should be percolated from above? Design itself comes into play. How much of the styling of this component should be scoped to itself, and how much should come from more global styles?

It’s no wonder that design systems have taken off in recent years. We’re building components anyway, so thinking of them systemically is a natural fit.

Let’s look at our design again:

A bunch of new thoughts can begin!

  • Assuming we’re using a JavaScript framework, which one? Why? 
  • Can we statically render this site, even if we’re building with a JavaScript framework? Or server-side render it? 
  • Where are those recipes coming from? Can we get a GraphQL API going so we can ask for whatever we need, whenever we need it?
  • Maybe we should pick a CMS that has an API that will facilitate the kind of front-end building we want to do. Perhaps a headless CMS?
  • What are we doing for routing? Is the framework we chose opinionated or unopinionated about stuff like this?
  • What are the components we need? A Card, Icon, SearchForm, SiteMenu, Img… can we scaffold these out? Should we start with some kind of design framework on top of the base framework?
  • What’s the client state we might need? Current search term, current tab, hamburger open or not, at least.
  • Is there a login system for this site or not? Are logged in users shown anything different? 
  • Is there are third-party componentry we can leverage here?
  • Maybe we can find one of those fancy image components that does blur-up loading and lazy loading and all that.

Those are all things that are in the domain of front-end developers these days, on top of everything that we already need to do. Executing the design, semantics, accessibility, performance… that’s all still there. You still need to be proficient in HTML, CSS, JavaScript, and how the browser works. Being a front-end developer requires a haystack of skills that grows and grows. It’s the natural outcome of the web getting bigger. More people use the web and internet access grows. The economy around the web grows. The capability of browsers grows. The expectations of what is possible on the web grows. There isn’t a lot shrinking going on around here.

We’ve already reached the point where most front-end developers don’t know the whole haystack of responsibilities. There are lots of developers still doing well for themselves being rather design-focused and excelling at creative and well-implemented HTML and CSS, even as job posts looking for that dwindle.

There are systems-focused developers and even entire agencies that specialize in helping other companies build and implement design systems. There are data-focused developers that feel most at home making the data flow throughout a website and getting hot and heavy with business logic. While all of those people might have “front-end developer” on their business card, their responsibilities and even expectations of their work might be quite different. It’s all good, we’ll find ways to talk about all this in time.

In fact, how we talk about building websites has changed a lot in the last decade. Some of my early introduction to web development was through WordPress. WordPress needs a web server to run, is written in PHP, and stores it’s data in a MySQL database. As much as WordPress has evolved, all that is still exactly the same. We talk about that “stack” with an acronym: LAMP, or Linux, Apache, MySQL and PHP. Note that literally everything in the entire stack consists of back-end technologies. As a front-end developer, nothing about LAMP is relevant to me.

But other stacks have come along since then. A popular stack was MEAN (Mongo, Express, Angular and Node). Notice how we’re starting to inch our way toward more front-end technologies? Angular is a JavaScript framework, so as this stack gained popularity, so too did talking about the front-end as an important part of the stack. Node and Express are both JavaScript as well, albeit the server-side variant.

The existence of Node is a huge part of this story. Node isn’t JavaScript-like, it’s quite literally JavaScript. It makes a front-end developer already skilled in JavaScript able to do server-side work without too much of a stretch.

“Serverless” is a much more modern tech buzzword, and what it’s largely talking about is running small bits of code on cloud servers. Most often, those small bits of code are in Node, and written by JavaScript developers. These days, a JavaScript-focused front-end developer might be writing their own serverless functions and essentially being their own back-end developer. They’ll think of themselves as full-stack developers, and they’ll be right.

Shawn Wang coined a term for a new stack this year: STAR or Design System, TypeScript, Apollo, and React. This is incredible to me, not just because I kind of like that stack, but because it’s a way of talking about the stack powering a website that is entirely front-end technologies. Quite a shift.

I apologize if I’ve made you feel a little anxious reading this. If you feel like you’re behind in understanding all this stuff, you aren’t alone.

In fact, I don’t think I’ve talked to a single developer who told me they felt entirely comfortable with the entire world of building websites. Everybody has weak spots or entire areas where they just don’t know the first dang thing. You not only can specialize, but specializing is a pretty good idea, and I think you will end up specializing to some degree whether you plan to or not. If you have the good fortune to plan, pick things that you like. You’ll do just fine.

The only constant in life is change.

– Heraclitus
    – Motivational Poster
        – Chris Coyier


¹ I’m a white dude, so that helps a bunch, too. ↩️
² Browsers speak a bunch more languages. HTTP, SVG, PNG… The more you know the more you can put to work! ↩️
³ It’s an interesting bit of irony that WordPress websites generally aren’t built with client-side JavaScript components. ↩️


The post How to Think Like a Front-End Developer appeared first on CSS-Tricks.

You can support CSS-Tricks by being an MVP Supporter.

Create an FAQ Slack app with Netlify functions and FaunaDB

Post pobrano z: Create an FAQ Slack app with Netlify functions and FaunaDB

Sometimes, when you’re looking for a quick answer, it’s really useful to have an FAQ system in place, rather than waiting for someone to respond to a question. Wouldn’t it be great if Slack could just answer these FAQs for us? In this tutorial, we’re going to be making just that: a slash command for Slack that will answer user FAQs. We’ll be storing our answers in FaunaDB, using FQL to search the database, and utilising a Netlify function to provide a serverless endpoint to connect Slack and FaunaDB.

Prerequisites

This tutorial assumes you have the following requirements:

  • Github account, used to log in to Netlify and Fauna, as well as storing our code
  • Slack workspace with permission to create and install new apps
  • Node.js v12

Create npm package

To get started, create a new folder and initialise a npm package by using your package manager of choice and run npm init -y from inside the folder. After the package has been created, we have a few npm packages to install.

Run this to install all the packages we will need for this tutorial:

npm install express body-parser faunadb encoding serverless-http netlify-lambda

These packages are explained below, but if you are already familiar with them, feel free to skip ahead.

Encoding has been installed due to a plugin error occurring in @netlify/plugin-functions-core at the time of writing and may not be needed when you follow this tutorial.

Packages

Express is a web application framework that will allow us to simplify writing multiple endpoints for our function. Netlify functions require handlers for each endpoint, but express combined with serverless-http will allow us to write the endpoints all in one place.

Body-parser is an express middleware which will take care of the application/x-www-form-urlencoded data Slack will be sending to our function.

Faunadb is an npm module that allows us to interact with the database through the FaunaDB Javascript driver. It allows us to pass queries from our function to the database, in order to get the answers

Serverless-http is a module that wraps Express applications to the format expected by Netlify functions, meaning we won’t have to rewrite our code when we shift from local development to Netlify.

Netlify-lambda is a tool which will allow us to build and serve our functions locally, in the same way they will be built and deployed on Netlify. This means we can develop locally before pushing our code to Netlify, increasing the speed of our workflow.

Create a function

With our npm packages installed, it’s time to begin work on the function. We’ll be using serverless to wrap an express app, which will allow us to deploy it to Netlify later. To get started, create a file called netlify.toml, and add the following into it:

[build]
  functions = "functions"

We will use a .gitignore file, to prevent our node_modules and functions folders from being added to git later. Create a file called .gitignore, and add the following:

functions/

node_modules/

We will also need a folder called src, and a file inside it called server.js. Your final file structure should look like:

With this in place, create a basic express app by inserting the code below into server.js:

const express = require("express");
const bodyParser = require("body-parser");
const fauna = require("faunadb");
const serverless = require("serverless-http");
 
const app = express();
 
module.exports.handler = serverless(app);

Check out the final line; it looks a little different to a regular express app. Rather than listening on a port, we’re passing our app into serverless and using this as our handler, so that Netlify can invoke our function.

Let’s set up our body parser to use application/x-www-form-urlencoded data, as well as putting a router in place. Add the following to server.js after defining app: 

const router = express.Router();
app.use(bodyParser.json());
app.use(bodyParser.urlencoded({ extended: true }));
app.use("/.netlify/functions/server", router);

Notice that the router is using /.netlify/functions/server as an endpoint. This is so that Netlify will be able to correctly deploy the function later in the tutorial. This means we will need to add this to any base URLs, in order to invoke the function.

Create a test route

With a basic app in place, let’s create a test route to check everything is working. Insert the following code to create a simple GET route, that returns a simple json object:

router.get("/test", (req, res) => {
 res.json({ hello: "world" });
});

With this route in place, let’s spin up our function on localhost, and check that we get a response. We’ll be using netlify-lambda to serve our app, so that we can imitate a Netlify function locally on port 9000. In our package.json, add the following lines into the scripts section:

"start": "./node_modules/.bin/netlify-lambda serve src",
   "build": "./node_modules/.bin/netlify-lambda build src"

With this in place, after saving the file, we can run npm start to begin netlify-lambda on port 9000.

The build command will be used when we deploy to Netlify later.

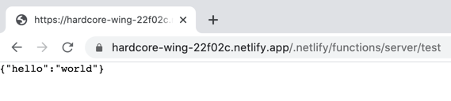
Once it is up and running, we can visit http://localhost:9000/.netlify/functions/server/test to check our function is working as expected.

The great thing about netlify-lambda is it will listen for changes to our code, and automatically recompile whenever we update something, so we can leave it running for the duration of this tutorial.

Start ngrok URL

Now we have a test route working on our local machine, let’s make it available online. To do this, we’ll be using ngrok, a npm package that provides a public URL for our function. If you don’t have ngrok installed already, first run npm install -g ngrok to globally install it on your machine. Then run ngrok http 9000 which will automatically direct traffic to our function running on port 9000.

After starting ngrok, you should see a forwarding URL in the terminal, which we can visit to confirm our server is available online. Copy this base URL to your browser, and follow it with /.netlify/functions/server/test. You should see the same result as when we made our calls on localhost, which means we can now use this URL as an endpoint for Slack!

Each time you restart ngrok, it creates a new URL, so if you need to stop it at any point, you will need to update your URL endpoint in Slack.

Setting up Slack

Now that we have a function in place, it’s time to move to Slack to create the app and slash command. We will have to deploy this app to our workspace, as well as making a few updates to our code to connect our function. For a more in depth set of instructions on how to create a new slash command, you can follow the official Slack documentation. For a streamlined set of instructions, follow along below:

Create a new Slack app

First off, let’s create our new Slack app for these FAQs. Visit https://api.slack.com/apps and select Create New App to begin. Give your app a name (I used Fauna FAQ), and select a development workspace for the app.

Create a slash command

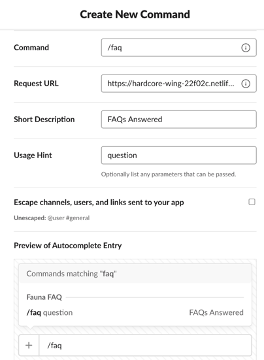
After creating the app, we need to add a slash command to it, so that we can interact with the app. Select slash commands from the menu after the app has been created, then create a new command. Fill in the following form with the name of your command (I used /faq) as well as providing the URL from ngrok. Don’t forget to add /.netlify/functions/server/ to the end!

Install app to workspace

Once you have created your slash command, click on basic information in the sidebar on the left to return to the app’s main page. From here, select the dropdown “Install app to your workspace” and click the button to install it.

Once you have allowed access, the app will be installed, and you’ll be able to start using the slash command in your workspace.

Update the function

With our new app in place, we’ll need to create a new endpoint for Slack to send the requests to. For this, we’ll use the root endpoint for simplicity. The endpoint will need to be able to take a post request with application/x-www-form-urlencoded data, then return a 200 status response with a message. To do this, let’s create a new post route at the root by adding the following code to server.js:

router.post("/", async (req, res) => {
 
});

Now that we have our endpoint, we can also extract and view the text that has been sent by slack by adding the following line before we set the status:

const text = req.body.text;
console.log(`Input text: ${text}`);

For now, we’ll just pass this text into the response and send it back instantly, to ensure the slack app and function are communicating.

res.status(200);
res.send(text);

Now, when you type /faq <somequestion> on a slack channel, you should get back the same message from the slack slash command.

Formatting the response

Rather than just sending back plaintext, we can make use of Slack’s Block Kit to use specialised UI elements to improve the look of our answers. If you want to create a more complex layout, Slack provides a Block Kit builder to visually design your layout.

For now, we’re going to keep things simple, and just provide a response where each answer is separated by a divider. Add the following function to your server.js file after the post route:

const format = (answers) => {
 if (answers.length == 0) {
   answers = ["No answers found"];
 }
 
 let formatted = {
   blocks: [],
 };
 
 for (answer of answers) {
   formatted["blocks"].push({
     type: "divider",
   });
   formatted["blocks"].push({
     type: "section",
     text: {
       type: "mrkdwn",
       text: answer,
     },
   });
 }
 
 return formatted;
};

With this in place, we now need to pass our answers into this function, to format the answers before returning them to Slack. Update the following in the root post route:

let answers = text;
const formattedAnswers = format(answers);

Now when we enter the same command to the slash app, we should get back the same message, but this time in a formatted version!

Setting up Fauna

With our slack app in place, and a function to connect to it, we now need to start working on the database to store our answers. If you’ve never set up a database with FaunaDB before, there is some great documentation on how to quickly get started. A brief step-by-step overview for the database and collection is included below:

Create database

First, we’ll need to create a new database. After logging into the Fauna dashboard online, click New Database. Give your new database a name you’ll remember (I used “slack-faq”) and save the database.

Create collection

With this database in place, we now need a collection. Click the “New Collection” button that should appear on your dashboard, and give your collection a name (I used “faq”). The history days and TTL values can be left as their defaults, but you should ensure you don’t add a value to the TTL field, as we don’t want our documents to be removed automatically after a certain time.

Add question / answer documents

Now we have a database and collection in place, we can start adding some documents to it. Each document should follow the structure:

{
   question: "a question string",
   answer: "an answer string",
   qTokens: [
       "first token",
       "second token",
       "third token"
   ]
}

The qToken values should be key terms in the question, as we will use them for a tokenized search when we can’t match a question exactly. You can add as many qTokens as you like for each question. The more relevant the tokens are, the more accurate results will be. For example, if our question is “where are the bathrooms”, we should include the qTokens “bathroom”, “bathrooms”, “toilet”, “toilets” and any other terms you may think people will search for when trying to find information about a bathroom.

The questions I used to develop a proof of concept are as follows:

{
  question: "where is the lobby",
  answer: "On the third floor",
  qTokens: ["lobby", "reception"],
},
{
  question: "when is payday",
  answer: "On the first Monday of each month",
  qTokens: ["payday", "pay", "paid"],
},
{
  question: "when is lunch",
  answer: "Lunch break is *12 - 1pm*",
  qTokens: ["lunch", "break", "eat"],
},
{
  question: "where are the bathrooms",
  answer: "Next to the elevators on each floor",
  qTokens: ["toilet", "bathroom", "toilets", "bathrooms"],
},
{
  question: "when are my breaks",
  answer: "You can take a break whenever you want",
  qTokens: ["break", "breaks"],
}

Feel free to take this time to add as many documents as you like, and as many qTokens as you think each question needs, then we’ll move on to the next step.

Creating Indexes

With these questions in place, we will create two indexes to allow us to search the database. First, create an index called “answers_by_question”, selecting question as the term and answer as the value. This will allow us to search all answers by their associated question.

Then, create an index called “answers_by_qTokens”, selecting qTokens as the term and answer as the value. We will use this index to allow us to search through the qTokens of all items in the database.

Searching the database

To run a search in our database, we will do two things. First, we’ll run a search for an exact match to the question, so we can provide a single answer to the user. Second, if this search doesn’t find a result, we’ll do a search on the qTokens each answer has, returning any results that provide a match. We’ll use Fauna’s online shell to demonstrate and explain these queries, before using them in our function.

Exact Match

Before searching the tokens, we’ll test whether we can match the input question exactly, as this will allow for the best answer to what the user has asked. To search our questions, we will match against the “answers_by_question” index, then paginate our answers. Copy the following code into the online Fauna shell to see this in action:

q.Paginate(q.Match(q.Index("answers_by_question"), "where is the lobby"))

If you have a question matching the “where is the lobby” example above, you should see the expected answer of “On the third floor” as a result.

Searching the tokens

For cases where there is no exact match on the database, we will have to use our qTokens to find any relevant answers. For this, we will match against the “answers_by_qTokens” index we created and again paginate our answers. Copy the following into the online shell to see how this works:

q.Paginate(q.Match(q.Index("answers_by_qTokens"), "break"))

If you have any questions with the qToken “break” from the example questions, you should see all answers returned as a result.

Connect function to Fauna

We have our searches figured out, but currently we can only run them from the online shell. To use these in our function, there is some configuration required, as well as an update to our function’s code.

Function configuration

To connect to Fauna from our function, we will need to create a server key. From your database’s dashboard, select security in the left hand sidebar, and create a new key. Give your new key a name you will recognise, and ensure that the dropdown has Server selected, not Admin. Finally, once the key has been created, add the following code to server.js before the test route, replacing the <secretKey> value with the secret provided by Fauna.

const q = fauna.query;
const client = new fauna.Client({
 secret: "<secretKey>",
});

It would be preferred to store this key in an environment variable in Netlify, rather than directly in the code, but that is beyond the scope of this tutorial. If you would like to use environment variables, this Netlify post explains how to do so.

Update function code

To include our new search queries in the function, copy the following code into server.js after the post route:

const searchText = async (text) => {
 console.log("Beginning searchText");
 const answer = await client.query(
   q.Paginate(q.Match(q.Index("answers_by_question"), text))
 );
 console.log(`searchText response: ${answer.data}`);
 return answer.data;
};
 
const getTokenResponse = async (text) => {
 console.log("Beginning getTokenResponse");
 let answers = [];
 const questionTokens = text.split(/[ ]+/);
 console.log(`Tokens: ${questionTokens}`);
 for (token of questionTokens) {
   const tokenResponse = await client.query(
     q.Paginate(q.Match(q.Index("answers_by_qTokens"), text))
   );
   answers = [...answers, ...tokenResponse.data];
 }
 console.log(`Token answers: ${answers}`);
 return answers;
};

These functions replicate the same functionality as the queries we previously ran in the online Fauna shell, but now we can utilise them from our function.

Deploy to Netlify

Now the function is searching the database, the only thing left to do is put it on the cloud, rather than a local machine. To do this, we’ll be making use of a Netlify function deployed from a GitHub repository.

First things first, add a new repo on Github, and push your code to it. Once the code is there, go to Netlify and either sign up or log in using your Github profile. From the home page of Netlify, select “New site from git” to deploy a new site, using the repo you’ve just created in Github.

If you have never deployed a site in Netlify before, this post explains the process to deploy from git.

Ensure while you are creating the new site, that your build command is set to npm run build, to have Netlify build the function before deployment. The publish directory can be left blank, as we are only deploying a function, rather than any pages.

Netlify will now build and deploy your repo, generating a unique URL for the site deployment. We can use this base URL to access the test endpoint of our function from earlier, to ensure things are working.

The last thing to do is update the Slack endpoint to our new URL! Navigate to your app, then select ‘slash commands’ in the left sidebar. Click on the pencil icon to edit the slash command and paste in the new URL for the function. Finally, you can use your new slash command in any authorised Slack channels!

Conclusion

There you have it, an entirely serverless, functional slack slash command. We have used FaunaDB to store our answers and connected to it through a Netlify function. Also, by using Express, we have the flexibility to add further endpoints to the function for adding new questions, or anything else you can think up to further extend this project! Hopefully now, instead of waiting around for someone to answer your questions, you can just use /faq and get the answer instantly!


Matthew Williams is a software engineer from Melbourne, Australia who believes the future of technology is serverless. If you’re interested in more from him, check out his Medium articles, or his GitHub repos.


The post Create an FAQ Slack app with Netlify functions and FaunaDB appeared first on CSS-Tricks.

You can support CSS-Tricks by being an MVP Supporter.

Animating Number Counters

Post pobrano z: Animating Number Counters

Number animation, as in, imagine a number changing from 1 to 2, then 2 to 3, then 3 to 4, etc. over a specified time. Like a counter, except controlled by the same kind of animation that we use for other design animation on the web. This could be useful when designing something like a dashboard, to bring a little pizazz to the numbers. Amazingly, this can now be done in CSS without much trickery. You can jump right to the new solution if you like, but first let’s look at how we used to do it.

One fairly logical way to do number animation is by changing the number in JavaScript. We could do a rather simple setInterval, but here’s a fancier answer with a function that accepts a start, end, and duration, so you can treat it more like an animation:

CodePen Embed Fallback

Keeping it to CSS, we could use CSS counters to animate a number by adjusting the count at different keyframes:

CodePen Embed Fallback

Another way would be to line up all the numbers in a row and animate the position of them only showing one at a time:

CodePen Embed Fallback

Some of the repetitive code in these examples could use a preprocessor like Pug for HTML or SCSS for CSS that offer loops to make them perhaps easier to manage, but use vanilla on purpose so you can see the fundamental ideas.

The New School CSS Solution

With recent support for CSS.registerProperty and @property, we can animate CSS variables. The trick is to declare the CSS custom property as an integer; that way it can be interpolated (like within a transition) just like any other integer.

@property --num {
  syntax: '<integer>';
  initial-value: 0;
  inherits: false;
}

div {
  transition: --num 1s;
  counter-reset: num var(--num);
}
div:hover {
  --num: 10000;
}
div::after {
  content: counter(num);
}

Important Note: At the time of this writing, this @property syntax is only supported in Chrome ( and other Chromium core browsers like Edge and Opera), so this isn’t cross-browser friendly. If you’re building something Chrome-only (e.g. an Electron app) it’s useful right away, if not, wait. The demos from above are more widely supported.

The CSS content property can be used to display the number, but we still need to use counter to convert the number to a string because content can only output <string> values.

CodePen Embed Fallback

See how we can ease the animations just like any other animation? Super cool! 

Typed CSS variables can also be used in @keyframes: 

CodePen Embed Fallback

One downside? Counters only support integers. That means decimals and fractions are out of the question. We’d have to display the integer part and fractional part separately somehow.

Can we animate decimals?

It’s possible to convert a decimal (e.g. --number) to an integer. Here’s how it works:

  1. Register an <integer> CSS variable ( e.g. --integer ), with the initial-value specified
  2. Then use calc() to round the value: --integer: calc(var(--number))

In this case, --number will be rounded to the nearest integer and store the result into --integer.

@property --integer {
  syntax: "<integer>";
  initial-value: 0;
  inherits: false;
}
--number: 1234.5678;
--integer: calc(var(--number)); /* 1235 */

Sometimes we just need the integer part. There is a tricky way to do it: --integer: max(var(--number) - 0.5, 0). This works for positive numbers. calc() isn’t even required this way.

/* @property --integer */
--number: 1234.5678;
--integer: max(var(--number) - 0.5, 0); /* 1234 */

We can extract the fractional part in a similar way, then convert it into string with counter (but remember that content values must be strings). To display concatenated strings, use following syntax:

content: "string1" var(--string2) counter(--integer) ...

Here’s a full example that animates percentages with decimals:

CodePen Embed Fallback

Other tips

Because we’re using CSS counters, the format of those counters can be in other formats besides numbers. Here’s an example of animating the letters “CSS” to “YES”!

CodePen Embed Fallback

Oh and here’s another tip: we can debug the values grabbing the computed value of the custom property with JavaScript:

getComputedStyle(element).getPropertyValue('--variable')

That’s it! It’s amazing what CSS can do these days.


The post Animating Number Counters appeared first on CSS-Tricks.

You can support CSS-Tricks by being an MVP Supporter.

Balancing on a Pivot with Flexbox

Post pobrano z: Balancing on a Pivot with Flexbox

Let me show you a way I recently discovered to center a bunch of elements around what I call the pivot. I promise you that funky HTML is out of the question and you won’t need to know any bleeding-edge CSS to get the job done.

I’m big on word games, so I recently re-imagined the main menu of my website as a nod to crossword puzzles, with my name as the vertical word, and the main sections of my website across the horizontals.

Here’s how the design looks with the names of some colors instead:

And here’s a sample of the HTML that drives this puzzle:

<div class="puzzle">
  <div class="word">
    <span class="letter">i</span>
    <span class="letter">n</span>
    <span class="letter">d</span>
    <span class="letter">i</span>
    <span class="letter pivot">g</span>
    <span class="letter">o</span>
  </div>
  <!-- MORE WORDS -->
</div>

In this example, the letter g is the pivot. See how it’s not at the halfway mark? That’s the beauty of this challenge.

We could apply an offset to each word using hard-coded CSS or inline custom properties and walk away. It certainly gets an award for being the most obvious way to solve the problem, but there’s a downside — in addition to the .pivot class, we’d have to specify an offset for every word. The voice in my head tells me that’s adding unnecessary redundancy, is less flexible, and requires extra baggage we don’t need every time we add or change a word.

Let’s take a step back instead and see how the puzzle looks without any balancing:

Imagine for a moment that we use display: none to hide all of the letters before the pivot; now all we can see are the pivots and everything after them:

With no further changes, our pivots would already be aligned. But we’ve lost the start of our words, and when we reintroduce the hidden parts, each word gets pushed out to the right and everything is out of whack again.

If we were to hide the trailing letters instead, we’d still be left with misaligned pivots:

All of this back-and-forth seems a bit pointless, but it reveals a symmetry to my problem. If we were to use a right-to-left (RTL) reading scheme, we’d have the opposite problem — we’d be able to solve the right side but the left would be all wrong.

Wouldn’t it be great if there was a way to have both sides line up at the same time?

As a matter of fact, there is.

Given we already have half a solution, let’s borrow a concept from algorithmics called divide and conquer. The general idea is that we can break a problem down into parts, and that by finding a solution for the parts, we’ll find a solution for the whole.

In that case, let’s break our problem down into the positioning of two parts. First is the “head” or everything before the pivot.

Next is the “tail” which is the pivot plus everything after it.

The flex display type will help us here; if you’re not familiar with it, flex is a framework for positioning elements in one-dimension. The trick here is to take advantage of the left and right ends of our container to enforce alignment. To make it work, we’ll swap the head and tail parts by using a smaller order  property value on the tail than the head. The order property is used by flex to determine the sequence of elements in a flexible layout. Smaller numbers are placed earlier in the flow.

To distinguish the head and tail elements without any extra HTML, we can apply styles to the head part to all of the letters, after which we’ll make use of the cascading nature of CSS to override the pivot and everything after it using the subsequent-sibling selector .pivot ~ .letter.

Here’s how things look now:

Okay, so now the head is sitting flush up against the end of the tail. Hang on, don’t go kicking up a stink about it! We can fix this by applying margin: auto to the right of the last element in the tail. That just so happens to also be the last letter in the word which is now sitting somewhere in the middle. The addition of an auto margin serves to push the head away from the tail and all the way over to the right-hand side of our container.

Now we have something that looks like this:

The only thing left is stitch our pieces back together in the right order. This is easy enough to do if we apply position: relative to all of our letters and then chuck a left: 50% on the tail and a right: 50% on our head items.

Here’s a generalized version of the code we just used. As you can see, it’s just 15 lines of simple CSS:

.container {
  display: flex;
}
.item:last-child {
  margin-right: auto;
}
.item {
  order: 2;
  position: relative;
  right: 50%;
}
.pivot, .pivot ~ .item {
  order: 1;
  left: 50%;
}

It’s also feasible to use this approach for vertical layouts by setting the flex-direction to a column value. It should also be said that the same can be achieved by sticking the head and tail elements in their own wrappers — but that would require more markup and verbose CSS while being a lot less flexible. What if, for example, our back-end is already generating an unwrapped list of elements with dynamically generated classes?

Quite serendipitously, this solution also plays well with screen readers. Although we’re ordering the two sections backwards, we’re then shifting them back into place via relative positioning, so the final ordering of elements matches our markup, albeit nicely centered.

Screen readers preserve the element ordering as per the original markup.

Here’s the final example on CodePen:

CodePen Embed Fallback

Conclusion

Developers are better at balancing than acrobats. Don’t believe me? Think about it: many of the common challenges we face require finding a sweet spot between competing requirements ranging from performance and readability, to style and function, and even scalability and simplicity. A balancing act, no doubt.

But the point at which we find balance isn’t always midway between one thing and another. Balance is often found at some inexplicable point in between; or, as we’ve just seen, around an arbitrary HTML element.

So there you have it! Go and tell your friends that you’re the greatest acrobat around.


The post Balancing on a Pivot with Flexbox appeared first on CSS-Tricks.

You can support CSS-Tricks by being an MVP Supporter.

The Widening Responsibility for Front-End Developers

Post pobrano z: The Widening Responsibility for Front-End Developers

This is an extended version of my essay “When front-end means full-stack” which was published in the wonderful Increment magazine put out by Stripe. It’s also something of an evolution of a couple other of my essays, “The Great Divide” and “Ooops, I guess we’re full-stack developers now.”

The moment I fell in love with front-end development was when I discovered the style.css file in WordPress themes. That’s where all the magic was (is!) to me. I could (can!) change a handful of lines in there and totally change the look and feel of a website. It’s an incredible game to play.

Back when I was cowboy-coding over FTP. Although I definitely wasn’t using CSS grid!

By fiddling with HTML and CSS, I can change the way you feel about a bit of writing. I can make you feel more comfortable about buying tickets to an event. I can increase the chances you share something with your friends.

That was well before anybody paid me money to be a front-end developer, but even then I felt the intoxicating mix of stimuli that the job offers. Front-end development is this expressive art form, but often constrained by things like the need to directly communicate messaging and accomplish business goals.

Front-end development is at the intersection of art and logic. A cross of business and expression. Both left and right brain. A cocktail of design and nerdery.

I love it.

Looking back at the courses I chose from middle school through college, I bounced back and forth between computer-focused classes and art-focused classes, so I suppose it’s no surprise I found a way to do both as a career.

The term “Front-End Developer” is fairly well-defined and understood. For one, it’s a job title. I’ll bet some of you literally have business cards that say it on there, or some variation like: “Front-End Designer,” “UX Developer,” or “UI Engineer.” The debate around what those mean isn’t particularly interesting to me. I find that the roles are so varied from job-to-job and company-to-company that job titles will never be enough to describe things. Getting this job is more about demonstrating you know what you’re doing more than anything else¹.

Chris Coyier
Front-End Developer

The title variations are just nuance. The bigger picture is that as long as the job is building websites, front-enders are focused on the browser. Quite literally:

  • front-end = browsers
  • back-end = servers

Even as the job has changed over the decades, that distinction still largely holds.

As “browser people,” there are certain truths that come along for the ride. One is that there is a whole landscape of different browsers and, despite the best efforts of standards bodies, they still behave somewhat differently. Just today, as I write, I dealt with a bug where a date string I had from an API was in a format such that Firefox threw an error when I tried to use the .toISOString() JavaScript API on it, but was fine in Chrome. That’s just life as a front-end developer. That’s the job.

Even across that landscape of browsers, just on desktop computers, there is variance in how users use that browser. How big do they have the window open? Do they have dark mode activated on their operating system? How’s the color gamut on that monitor? What is the pixel density? How’s the bandwidth situation? Do they use a keyboard and mouse? One or the other? Neither? All those same questions apply to mobile devices too, where there is an equally if not more complicated browser landscape. And just wait until you take a hard look at HTML emails.

That’s a lot of unknowns, and the answers to developing for that unknown landscape is firmly in the hands of front-end developers.

Into the unknoooooowwwn. – Elsa

The most important aspect of the job? The people that use these browsers. That’s why we’re building things at all. These are the people I’m trying to impress with my mad CSS skills. These are the people I’m trying to get to buy my widget. Who all my business charts hinge upon. Who’s reaction can sway my emotions like yarn in the breeze. These users, who we put on a pedestal for good reason, have a much wider landscape than the browsers do. They speak different languages. They want different things. They are trying to solve different problems. They have different physical abilities. They have different levels of urgency. Again, helping them is firmly in the hands of front-end developers. There is very little in between the characters we type into our text editors and the users for whom we wish to serve.

Being a front-end developer puts us on the front lines between the thing we’re building and the people we’re building it for, and that’s a place some of us really enjoy being.

That’s some weighty stuff, isn’t it? I haven’t even mentioned React yet.

The “we care about the users” thing might feel a little precious. I’d think in a high functioning company, everyone would care about the users, from the CEO on down. It’s different, though. When we code a <button>, we’re quite literally putting a button into a browser window that users directly interact with. When we adjust a color, we’re adjusting exactly what our sighted users see when they see our work.

That’s not far off from a ceramic artist pulling a handle out of clay for a coffee cup. It’s applying craftsmanship to a digital experience. While a back-end developer might care deeply about the users of a site, they are, as Monica Dinculescu once told me in a conversation about this, “outsourcing that responsibility.”


We established that front-end developers are browser people. The job is making things work well in browsers. So we need to understand the languages browsers speak, namely: HTML, CSS, and JavaScript². And that’s not just me being some old school fundamentalist; it’s through a few decades of everyday front-end development work that knowing those base languages is vital to us doing a good job. Even when we don’t work directly with them (HTML might come from a template in another language, CSS might be produced from a preprocessor, JavaScript might be mostly written in the parlance of a framework), what goes the browser is ultimately HTML, CSS, and JavaScript, so that’s where debugging largely takes place and the ability of the browser is put to work.

CSS will always be my favorite and HTML feels like it needs the most love — but JavaScript is the one we really need to examine The last decade has seen JavaScript blossom from a language used for a handful of interactive effects to the predominant language used across the entire stack of web design and development. It’s possible to work on websites and writing nothing but JavaScript. A real sea change.

JavaScript is all-powerful in the browser. In a sense, it supersedes HTML and CSS, as there is nothing either of those languages can do that JavaScript cannot. HTML is parsed by the browser and turned into the DOM, which JavaScript can also entirely create and manipulate. CSS has its own model, the CSSOM, that applies styles to elements in the DOM, which JavaScript can also create and manipulate.

This isn’t quite fair though. HTML is the very first file that browsers parse before they do the rest of the work needed to build the site. That firstness is unique to HTML and a vital part of making websites fast.

In fact, if the HTML was the only file to come across the network, that should be enough to deliver the basic information and functionality of a site.

That philosophy is called Progressive Enhancement. I’m a fan, myself, but I don’t always adhere to it perfectly. For example, a <form> can be entirely functional in HTML, when it’s action attribute points to a URL where the form can be processed. Progressive Enhancement would have us build it that way. Then, when JavaScript executes, it takes over the submission and has the form submit via Ajax instead, which might be a nicer experience as the page won’t have to refresh. I like that. Taken further, any <button> outside a form is entirely useless without JavaScript, so in the spirit of Progressive Enhancement, I should wait until JavaScript executes to even put that button on the page at all (or at least reveal it). That’s the kind of thing where even those of us with the best intentions might not always toe the line perfectly. Just put the button in, Sam. Nobody is gonna die.

JavaScript’s all-powerfulness makes it an appealing target for those of us doing work on the web — particularly as JavaScript as a language has evolved to become even more powerful and ergonomic, and the frameworks that are built in JavaScript become even more-so. Back in 2015, it was already so clear that JavaScript was experiencing incredible growth in usage, Matt Mullenweg, co-founder of WordPress, gave the developer world homework: “Learn JavaScript Deeply”³. He couldn’t have been more right. Half a decade later, JavaScript has done a good job of taking over front-end development. Particularly if you look at front-end development jobs.

While the web almanac might show us that only 5% of the top-zillion sites use React compared to 85% including jQuery, those numbers are nearly flipped when looking around at front-end development job requirements.

I’m sure there are fancy economic reasons for all that, but jobs are as important and personal as it gets for people, so it very much matters.


So we’re browser people in a sea of JavaScript building things for people. If we take a look at the job at a practical day-to-day tasks level, it’s a bit like this:

  • Translate designs into code
  • Think in terms of responsive design, allowing us to design and build across the landscape of devices
  • Build systemically. Construct components and patterns, not one-offs.
  • Apply semantics to content
  • Consider accessibility
  • Worry about the performance of the site. Optimize everything. Reduce, reuse, recycle.

Just that first bullet point feels like a college degree to me. Taken together, all of those points certainly do.

This whole list is a bit abstract though, so let’s apply it to something we can look at. What if this website was our current project?

Our brains and fingers go wild!

  • Let’s build the layout with CSS grid. 
  • What fonts are those? Do we need to load them in their entirety or can we subset them? What happens as they load in? This layout feels like it will really suffer from font-shifting jank. 
  • There are some repeated patterns here. We should probably make a card design pattern. Every website needs a good card pattern. 
  • That’s a gorgeous color scheme. Are the colors mathematically related? Should we make variables to represent them individually or can we just alter a single hue as needed? Are we going to use custom properties in our CSS? Colors are just colors though, we might not need the cascading power of them just for this. Should we just use Sass variables? Are we going to use a CSS preprocessor at all?
  • The source order is tricky here. We need to order things so that they make sense for a screen reader user. We should have a meeting about what the expected order of content should be, even if we’re visually moving things around a bit with CSS grid.
  • The photographs here are beautifully shot. But some of them match the background color of the site… can we get away with alpha-transparent PNGs here? Those are always so big. Can any next-gen formats help us? Or should we try to match the background of a JPG with the background of the site seamlessly. Who’s writing the alt text for these?
  • There are some icons in use here. Inline SVG, right? Certainly SVG of some kind, not icon fonts, right? Should we build a whole icon system? I guess it depends on how we’re gonna be building this thing more broadly. Do we have a build system at all?
  • What’s the whole front-end plan here? Can I code this thing in vanilla HTML, CSS, and JavaScript? Well, I know I can, but what are the team expectations? Client expectations? Does it need to be a React thing because it’s part of some ecosystem of stuff that is already React? Or Vue or Svelte or whatever? Is there a CMS involved?
  • I’m glad the designer thought of not just the “desktop” and “mobile” sizes but also tackled an in-between size. Those are always awkward. There is no interactivity information here though. What should we do when that search field is focused? What gets revealed when that hamburger is tapped? Are we doing page-level transitions here?

I could go on and on. That’s how front-end developers think, at least in my experience and in talking with my peers.

A lot of those things have been our jobs forever though. We’ve been asking and answering these questions on every website we’ve built for as long as we’ve been doing it. There are different challenges on each site, which is great and keeps this job fun, but there is a lot of repetition too.

Allow me to get around to the title of this article. 

While we’ve been doing a lot of this stuff for ages, there is a whole pile of new stuff we’re starting to be expected to do, particularly if we’re talking about building the site with a modern JavaScript framework. All the modern frameworks, as much as they like to disagree about things, agree about one big thing: everything is a component. You nest and piece together components as needed. Even native JavaScript moves toward its own model of Web Components.

I like it, this idea of components. It allows you and your team to build the abstractions that make the most sense to you and what you are building.

Your Card component does all the stuff your card needs to do. Your Form component does forms how your website needs to do forms. But it’s a new concept to old developers like me. Components in JavaScript have taken hold in a way that components on the server-side never did. I’ve worked on many a WordPress website where the best I did was break templates into somewhat arbitrary include() statements. I’ve worked on Ruby on Rails sites with partials that take a handful of local variables. Those are useful for building re-usable parts, but they are a far cry from the robust component models that JavaScript frameworks offer us today.

All this custom component creation makes me a site-level architect in a way that I didn’t use to be. Here’s an example. Of course I have a Button component. Of course I have an Icon component. I’ll use them in my Card component. My Card component lives in a Grid component that lays them out and paginates them. The whole page is actually built from components. The Header component has a SearchBar component and a UserMenu component. The Sidebar component has a Navigation component and an Ad component. The whole page is just a special combination of components, which is probably based on the URL, assuming I’m all-in on building our front-end with JavaScript. So now I’m dealing with URLs myself, and I’m essentially the architect of the entire site. [Sweats profusely]

Like I told ya, a whole pile of new responsibility.

Components that are in charge of displaying content are almost certainly not hard-coded with data in them. They are built to be templates. They are built to accept data and construct themselves based on that data. In the olden days, when we were doing this kind of templating, the data has probably already arrived on the page we’re working on. In a JavaScript-powered app, it’s more likely that that data is fetched by JavaScript. Perhaps I’ll fetch it when the component renders. In a stack I’m working with right now, the front end is in React, the API is in GraphQL and we use Apollo Client to work with data. We use a special “hook” in the React components to run the queries to fetch the data we need, and another special hook when we need to change that data. Guess who does that work? Is it some other kind of developer that specializes in this data layer work? No, it’s become the domain of the front-end developer.

Speaking of data, there is all this other data that a website often has to deal with that doesn’t come from a database or API. It’s data that is really only relevant to the website at this moment in time.

  • Which tab is active right now?
  • Is this modal dialog open or closed?
  • Which bar of this accordion is expanded?
  • Is this message bar in an error state or warning state?
  • How many pages are you paginated in?
  • How far is the user scrolled down the page?

Front-end developers have been dealing with that kind of state for a long time, but it’s exactly this kind of state that has gotten us into trouble before. A modal dialog can be open with a simple modifier class like <div class="modal is-open"> and toggling that class is easy enough with .classList.toggle(".is-open"); But that’s a purely visual treatment. How does anything else on the page know if that modal is open or not? Does it ask the DOM? In a lot of jQuery-style apps of yore, yes, it would. In a sense, the DOM became the “source of truth” for our websites. There were all sorts of problems that stemmed from this architecture, ranging from a simple naming change destroying functionality in weirdly insidious ways, to hard-to-reason-about application logic making bug fixing a difficult proposition.

Front-end developers collectively thought: what if we dealt with state in a more considered way? State management, as a concept, became a thing. JavaScript frameworks themselves built the concept right in, and third-party libraries have paved and continue to pave the way. This is another example of expanding responsibility. Who architects state management? Who enforces it and implements it? It’s not some other role, it’s front-end developers.

There is expanding responsibility in the checklist of things to do, but there is also work to be done in piecing it all together. How much of this state can be handled at the individual component level and how much needs to be higher level? How much of this data can be gotten at the individual component level and how much should be percolated from above? Design itself comes into play. How much of the styling of this component should be scoped to itself, and how much should come from more global styles?

It’s no wonder that design systems have taken off in recent years. We’re building components anyway, so thinking of them systemically is a natural fit.

Let’s look at our design again:

A bunch of new thoughts can begin!

  • Assuming we’re using a JavaScript framework, which one? Why? 
  • Can we statically render this site, even if we’re building with a JavaScript framework? Or server-side render it? 
  • Where are those recipes coming from? Can we get a GraphQL API going so we can ask for whatever we need, whenever we need it?
  • Maybe we should pick a CMS that has an API that will facilitate the kind of front-end building we want to do. Perhaps a headless CMS?
  • What are we doing for routing? Is the framework we chose opinionated or unopinionated about stuff like this?
  • What are the components we need? A Card, Icon, SearchForm, SiteMenu, Img… can we scaffold these out? Should we start with some kind of design framework on top of the base framework?
  • What’s the client state we might need? Current search term, current tab, hamburger open or not, at least.
  • Is there a login system for this site or not? Are logged in users shown anything different? 
  • Is there are third-party componentry we can leverage here?
  • Maybe we can find one of those fancy image components that does blur-up loading and lazy loading and all that.

Those are all things that are in the domain of front-end developers these days, on top of everything that we already need to do. Executing the design, semantics, accessibility, performance… that’s all still there. You still need to be proficient in HTML, CSS, JavaScript, and how the browser works. Being a front-end developer requires a haystack of skills that grows and grows. It’s the natural outcome of the web getting bigger. More people use the web and internet access grows. The economy around the web grows. The capability of browsers grows. The expectations of what is possible on the web grows. There isn’t a lot shrinking going on around here.

We’ve already reached the point where most front-end developers don’t know the whole haystack of responsibilities. There are lots of developers still doing well for themselves being rather design-focused and excelling at creative and well-implemented HTML and CSS, even as job posts looking for that dwindle.

There are systems-focused developers and even entire agencies that specialize in helping other companies build and implement design systems. There are data-focused developers that feel most at home making the data flow throughout a website and getting hot and heavy with business logic. While all of those people might have “front-end developer” on their business card, their responsibilities and even expectations of their work might be quite different. It’s all good, we’ll find ways to talk about all this in time.

In fact, how we talk about building websites has changed a lot in the last decade. Some of my early introduction to web development was through WordPress. WordPress needs a web server to run, is written in PHP, and stores it’s data in a MySQL database. As much as WordPress has evolved, all that is still exactly the same. We talk about that “stack” with an acronym: LAMP, or Linux, Apache, MySQL and PHP. Note that literally everything in the entire stack consists of back-end technologies. As a front-end developer, nothing about LAMP is relevant to me.

But other stacks have come along since then. A popular stack was MEAN (Mongo, Express, Angular and Node). Notice how we’re starting to inch our way toward more front-end technologies? Angular is a JavaScript framework, so as this stack gained popularity, so too did talking about the front-end as an important part of the stack. Node and Express are both JavaScript as well, albeit the server-side variant.

The existence of Node is a huge part of this story. Node isn’t JavaScript-like, it’s quite literally JavaScript. It makes a front-end developer already skilled in JavaScript able to do server-side work without too much of a stretch.

“Serverless” is a much more modern tech buzzword, and what it’s largely talking about is running small bits of code on cloud servers. Most often, those small bits of code are in Node, and written by JavaScript developers. These days, a JavaScript-focused front-end developer might be writing their own serverless functions and essentially being their own back-end developer. They’ll think of themselves as full-stack developers, and they’ll be right.

Shawn Wang coined a term for a new stack this year: STAR or Design System, TypeScript, Apollo, and React. This is incredible to me, not just because I kind of like that stack, but because it’s a way of talking about the stack powering a website that is entirely front-end technologies. Quite a shift.

I apologize if I’ve made you feel a little anxious reading this. If you feel like you’re behind in understanding all this stuff, you aren’t alone.

In fact, I don’t think I’ve talked to a single developer who told me they felt entirely comfortable with the entire world of building websites. Everybody has weak spots or entire areas where they just don’t know the first dang thing. You not only can specialize, but specializing is a pretty good idea, and I think you will end up specializing to some degree whether you plan to or not. If you have the good fortune to plan, pick things that you like. You’ll do just fine.

The only constant in life is change.

– Heraclitus
    – Motivational Poster
        – Chris Coyier


¹ I’m a white dude, so that helps a bunch, too. ↩️
² Browsers speak a bunch more languages. HTTP, SVG, PNG… The more you know the more you can put to work! ↩️
³ It’s an interesting bit of irony that WordPress websites generally aren’t built with client-side JavaScript components. ↩️


The post The Widening Responsibility for Front-End Developers appeared first on CSS-Tricks.

You can support CSS-Tricks by being an MVP Supporter.

Looking at AWS Amplify

Post pobrano z: Looking at AWS Amplify

AWS Amplify is a collection of tools from AWS to help you build applications.

Allow me to set the stage here to try to make that as clear as I know how. I have a friend (true story) who wants to build an app centered around physical training. His wife is a physical trainer, and they think perhaps there is some money to be made. It’s not entirely specced out, but perhaps the app sells access to personalized training programs, offers customized diets, exercise videos, and does the scheduling for one-on-one consultations. Sounds smart to me! Assuming they prove out the idea to some degree, it’s time to put their development skills to work and get to building.

A lot of the needs of an app like this map directly and easily to Amplify. A developer starting to plan might think like this:

  • We need to host this somewhere… Amplify has Static Web Hosting. And it’s fully featured with the fancy DX we’re starting to except these days: I connect a Git repo, and it will not only do deployment to CDN-backed global static hosting based on commits, but it will run my CI/CD (e.g. run tests) and give me URLs for previewing feature branches. You do all this with the AWS Amplify Console.
  • We need to do user authentication... The whole point here is that users can log in to get access to their stuff. Amplify helps with this (it’s Amazon Cognito built-in), which allows for typical sign-up/sign-in/forgot-password stuff, but also all the social login stuff you would expect. This is an example of what Amplify does: it helps abstract and build out underlying cloud services with minimal code.
  • We need data storage… Ideally, it’s managed with GraphQL because my modern front-end really benefits from that (perhaps it’s a React app). Amplify has that. It’s AWS AppSync built-in, which means you can use any type of data store, but get amazing features on top, like the GraphQL endpoints, realtime data syncing, and offline support.

That’s just the basics. All of that is extremely well-covered.

How do we set all this stuff up? This is one of the best parts: there is a CLI to help do everything. For example, about that data storage stuff, how do we get going with that? Once the CLI is installed and we’ve run amplify init in the project, we do amplify add api and we’ll be walked through it.

Now for this physical training app, we’ll need some static file storage as well. Maybe all the users have custom avatars, and the videos themselves need protected hosting. Well, we’re in AWS land here, so S3 buckets are a perfect fit. How? amplify add storage and we’ll be walked through it and of course, there are docs.

Impressive, really. We can build almost this entire thing with Amplify.

The one time we might have to reach out to another service is to handle payments. Stripe is usually the first choice of developers because of their great DX and robust APIs. They are built exactly for apps like this. We’d do our communicating with Stripe APIs over serverless functions. And guess what? We’re in AWS land here, so we have access to Lambdas, the best serverless function provider there is. The trick is that we can have our GraphQL setup, via AppSync, call a Lambda which can communicate with any outside API. Fortunately, there is a detailed walkthrough here from Ramon Postulart.

The guide to add Payments to your React Native App with Stripe, Expo and AWS Amplify by @ramonpostulart https://t.co/CvKl72kzw4 pic.twitter.com/T1MxsK51WC

— AWS Amplify (@AWSAmplify) May 22, 2020

And here’s another approach from Beez Fedia.


So here’s what I think is important to know:

  • Amplify is a helper. AWS offers tons of cloud services. Amplify helps you tie them together and get started using the important ones that you need.
  • The static hosting is the foundation for a web project. This is a Jamstack approach. But even that isn’t required, you can, for example, build an iOS app with the tools.
  • AWS is the biggest cloud provider in the world and powers many of the world’s biggest websites. You can build a personal project here and typically do it under the free tier, but you’ll never need to worry about scaling. You’re at the right place for scaling.
  • There is a lot to explore. If you wake up one day and want to add push notifications or explore something like machine learning, that stuff is there too.

If you’ve read this far, I think this quick high-level video will land better:

Other Resources


The post Looking at AWS Amplify appeared first on CSS-Tricks.

You can support CSS-Tricks by being an MVP Supporter.

Stay DRY Using axios for API Requests

Post pobrano z: Stay DRY Using axios for API Requests

HTTP requests are a crucial part of any web application that’s communicating with a back-end server. The front end needs some data, so it asks for it via a network HTTP request (or Ajax, as it tends to be called), and the server returns an answer. Almost every website these days does this in some fashion.

With a larger site, we can expect to see more of this. More data, more APIs, and more special circumstances. As sites grow like this, it is important to stay organized. One classic concept is DRY (short for Don’t Repeat Yourself), which is the process of abstracting code to prevent repeating it over and over. This is ideal because it often allows us to write something once, use it in multiple places, and update in a single place rather than each instance.

We might also reach for libraries to help us. For Ajax, axios is a popular choice. You might already be familiar with it, and even use it for things like independent POST and GET requests while developing. 

Installation and the basics

It can be installed using npm (or yarn):

npm install axios

An independent POST request using Axios looks like this:

axios.post('https://axios-app.firebaseio.com/users.json', formData)
  .then(res => console.log(res))
  .catch(error => console.log(error))

Native JavaScript has multiple ways of doing JavaScript too. Notably, fetch(). So why use a library at all? Well, for one, error handling in fetch is pretty wonky. You’ll have a better time with axios right out of the gate with that. If you’d like to see a comparison, we have an article that covers both and an article that talks about the value of abstraction with stuff like this.

Another reason to reach for axios? It gives us more opportunities for DRYness, so let’s look into that. 

Global config

We can set up a global configuration (e.g. in our main.js file) that handles all application requests using a standard configuration that is set through a default object that ships with axios. 

This object contains:

  • baseURL: A relative URL that acts as a prefix to all requests, and each request can append the URL
  • headers: Custom headers that can be set based on the requests
  • timeout: The point at which the request is aborted, usually measured in milliseconds. The default value is 0, meaning it’s not applicable.
  • withCredentials: Indicates whether or not cross-site Access-Control requests should be made using credentials. The default is false.
  • responseType: Indicates the type of data that the server will return, with options including json (default), arraybuffer, document, text, and stream.
  • responseEncoding: Indicates encoding to use for decoding responses. The default value is utf8.
  • xsrfCookieName: The name of the cookie to use as a value for XSRF token, the default value is XSRF-TOKEN.
  • xsrfHeaderName: The name of the HTTP header that carries the XSRF token value. The default value is X-XSRF-TOKEN.
  • maxContentLength: Defines the max size of the HTTP response content in bytes allowed
  • maxBodyLength: Defines the max size of the HTTP request content in bytes allowed

Most of time, you’ll only be using baseURL, header, and maybe timeout. The rest of them are less frequently needed as they have smart defaults, but it’s nice to know there are there in case you need to fix up requests.

This is the DRYness at work. For each request, we don’t have to repeat the baseURL of our API or repeat important headers that we might need on every request. 

Here’s an example where our API has a base, but it also has multiple different endpoints. First, we set up some defaults:

/ main.js
import axios from 'axios';


axios.defaults.baseURL = 'https://axios-app.firebaseio.com' // the prefix of the URL
axios.defaults.headers.get['Accept'] = 'application/json'   // default header for all get request
axios.defaults.headers.post['Accept'] = 'application/json'  // default header for all POST request


Then, in a component, we can use axios more succinctly, not needing to set those headers, but still having an opportunity to customize the final URL endpoint:


// form.js component
import axios from 'axios';


export default {
  methods : {
    onSubmit () {
      // The URL is now https://axios-app.firebaseio.com/users.json
      axios.post('/users.json', formData)
        .then(res => console.log(res))
        .catch(error => console.log(error))
    }
  }
}

Note: This example is in Vue, but the concept extends to any JavaScript situation.

Custom instance

Setting up a “custom instance” is similar to a global config, but scoped to specified components. So, it’s still a DRY technique, but with hierarchy. 

We’ll set up our custom instance in a new file (let’s call it authAxios.js) and import it into the “concern” components.

// authAxios.js
import axios from 'axios'


const customInstance = axios.create ({
  baseURL : 'https://axios-app.firebaseio.com'
})
customInstance.defaults.headers.post['Accept'] = 'application/json'


// Or like this...


const customInstance = axios.create ({
  baseURL : 'https://axios-app.firebaseio.com',
  headers: {'Accept': 'application.json'}
})

And then we import this file into the form components:

// form.js component


// import from our custom instance
import axios from './authAxios'


export default {
  methods : {
    onSubmit () {
      axios.post('/users.json', formData)
      .then(res => console.log(res))
      .catch(error => console.log(error))
    }
  }
}

Interceptors

Interceptors helps with cases where the global config or custom instance might be too generic, in the sense that if you set up an header within their objects, it applies to the header of every request within the affected components. Interceptors have the ability to change any object properties on the fly. For instance, we can send a different header (even if we have set one up in the object) based on any condition we choose within the interceptor.

Interceptors can be in the main.js file or a custom instance file. Requests are intercepted after they’ve been sent out and allow us to change how the response is handled.

// Add a request interceptor
axios.interceptors.request.use(function (config) {
  // Do something before request is sent, like we're inserting a timeout for only requests with a particular baseURL
  if (config.baseURL === 'https://axios-app.firebaseio.com/users.json') { 
    config.timeout = 4000 
  } else { 
    return config
  }
  console.log (config)
    return config;
  }, function (error) {
  // Do something with request error
  return Promise.reject(error);
});
 
// Add a response interceptor
axios.interceptors.response.use(function (response) {
  // Do something with response data like console.log, change header, or as we did here just added a conditional behaviour, to change the route or pop up an alert box, based on the reponse status  
  if (response.status === 200 || response.status 201) {
    router.replace('homepage') }
  else {
    alert('Unusual behaviour')
  }
  console.log(response)
  return response;
}, function (error) {
  // Do something with response error
  return Promise.reject(error);
});

Interceptors, as the name implies, intercept both requests and responses to act differently based on whatever conditions are provided. For instance, in the request interceptor above, we inserted a conditional timeout only if the requests have a particular baseURL. For the response, we can intercept it and modify what we get back, like change the route or have an alert box, depending on the status code. We can even provide multiple conditions based on different error codes.

Interceptors will prove useful as your project becomes larger and you start to have lots of routes and nested routes all communicating to servers based on different triggers. Beyond the conditions I set above, there are many other situations that can warrant the use of interceptors, based on your project.

Interestingly, we can eject an interceptor to prevent it from having any effect at all. We’ll have to assign the interceptor to a variable and eject it using the appropriately named eject method.

const reqInterceptor = axios.interceptors.request.use(function (config) {
  // Do something before request is sent, like we're inserting a timeout for only requests with a particular baseURL
  if (config.baseURL === 'https://axios-app.firebaseio.com/users.json') {
    config.timeout = 4000
  } else {
    return config
  }
  console.log (config)
  return config;
}, function (error) {    
  // Do something with request error
  return Promise.reject(error);
});
 
// Add a response interceptor
const resInterceptor = axios.interceptors.response.use(function (response) {
  // Do something with response data like console.log, change header, or as we did here just added a conditional behaviour, to change the route or pop up an alert box, based on the reponse status  
  if (response.status === 200 || response.status 201) {
    router.replace('homepage')
  } else {
    alert('Unusual behaviour')
  }
  console.log(response)
  return response;
}, function (error) {
  // Do something with response error
  return Promise.reject(error);
});


axios.interceptors.request.eject(reqInterceptor);
axios.interceptors.request.eject(resInterceptor);

Although it’s less commonly used, it’s possible to put and interceptor into a conditional statement or remove one based on some event.


Hopefully this gives you a good idea about the way axios works as well as how it can be used to keep API requests DRY in an application. While we scratched the surface by calling out common use cases and configurations, axis has so many other advantages you can explore in the documentation, including the ability to cancel requests and protect against cross-site request forgery , among other awesome possibilities.

The post Stay DRY Using axios for API Requests appeared first on CSS-Tricks.