Archiwum kategorii: CSS

Helping a Beginner Understand Getting a Website Live

Post pobrano z: Helping a Beginner Understand Getting a Website Live

I got a great email from a fellow named Josh Long the other day. He is, in his words, „relatively new to web design” and was a bit stuck on the concept of getting a site live. I should say that I’m happy to get emails like this an I always read them, but I typically can’t offer tech support over email. If I can respond at all, I normally point people to other community resources.

In this case, it struck me what a perfect moment this is for Josh. He’s a little confused, but he knows enough to be asking a lot of questions and sorting through all this stuff. I figured this was a wonderful opportunity to dig into his questions, hopefully helping him and just maybe helping others in a similar situation.

Here’s one of the original paragraphs Josh sent me, completely unedited:

I’m relatively new to web design, but I’ve taken a few courses on HTML and CSS and I’ve done a Codecademy course on JavaScript. But, (jumping forward probably quite a while here!) after having fully designed and coded a HTML/CSS/JS website or webpage, I don’t fully understand the full process of going from a local site hosted with mamp/wamp to publishing a public site using wordpress(?) or some other host (is WordPress even a host?!) and also finding a server that’s suitable and some way of hosting images/videos or other content. (If that sounded like I didn’t know what half of those meant, it’s because unfortunately I don’t!.. but I’d really like to!)

Can you sense that enthusiasm? I love it.

We worked together a bit to refine many of his questions for this post, but they are still Josh’s words. Here we go!


What is a Domain Registrar? I get they are for registering domain names, but what’s the difference between them? How do you know which one is right for you? A quick search for „best domain hosts” on Google gave me 5 ads for companies who are domain registrars/hosts and 9 „Top 10” style pages that look as though they have some sort of affiliation with at least one company they’re suggesting. Am I just looking for the cheapest one?

You’re exactly right, domain registrants are for registering domain names. If you want joshlongisverycool.com, you’re going to have to buy it, and domain registrants are companies that help you do that.
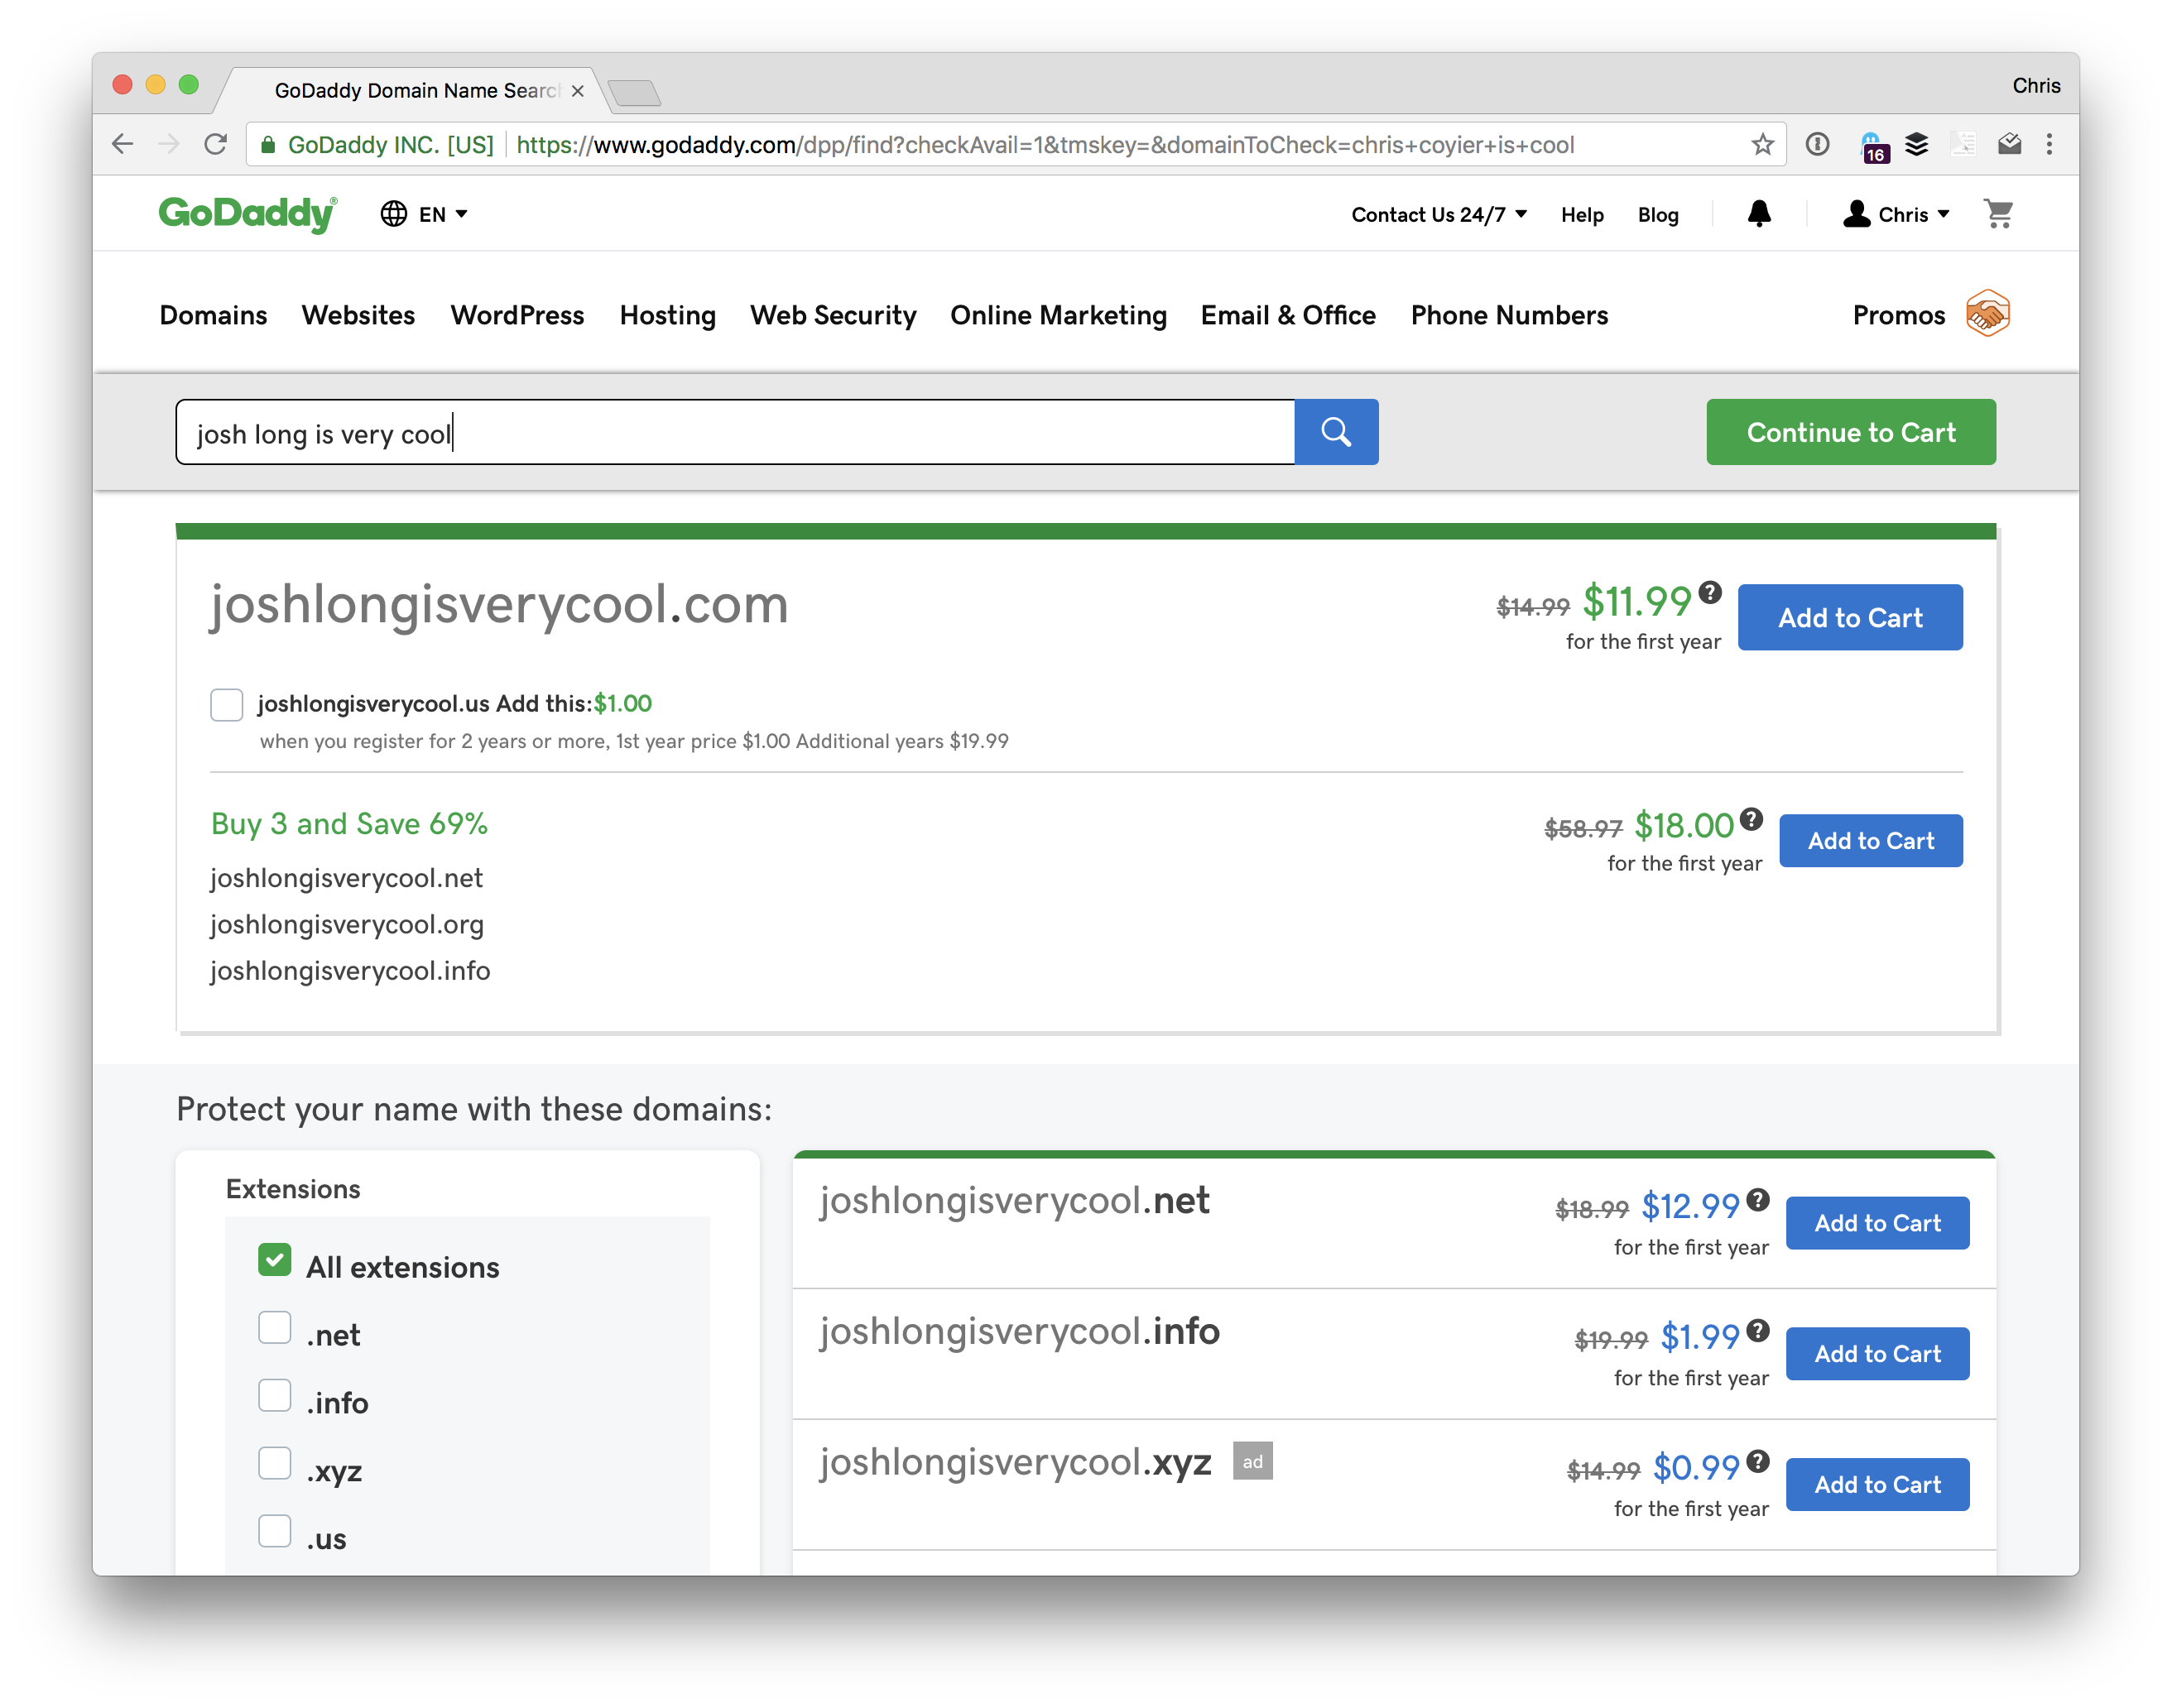
Searching for a domain name

It’s a bummer that web search results are so saturated by ads and affiliate-link-saturated SEO-jacked pages. You’ll never get total honesty from that because those pages are full of links promoting whoever will pay them the most to send new customers. Heck, even Google themselves will sell you a domain name.

The truth is that you can’t go too wrong here. Domain names are a bit of a commodity and the hundreds of companies that will sell you one largely compete on marketing.

Some things to watch out for:

  • Some companies treat the domain as a loss leader. Like a grocery store selling cheap milk to hope you buy some more stuff while you are there. The check out process at any domain registrant will almost certainly try to sell you a bunch of extra stuff. For example, they might try to sell you additional domain names or email hosting you probably don’t need. Just be careful.
  • Web hosts (which we’re getting to next) will often sell them to you along with hosting. That’s fine I suppose, but I consider it a bit of a conflict of interest. Say you choose to move hosts one day. That hosting company is incentivized in the wrong direction to make that easy for you. If the domain is handled elsewhere, that domain registrant is incentivized the right direction to help you make changes.

I hate to add to the noise for you, but here are some domain registrants that I’ve used personally and aren’t paying for sponsorship here nor are affiliate links:

Our own Sarah Drasner recommends looking at ZEIT domains, which are super interesting in that you buy and manage them entirely over the command line.

I might suggest, if you can see yourself owning several domain names in your life, keeping them consolidated to a single registrant. Managing domains isn’t something you’ll do very often, so it’s easy to lose track of what domains you registered on what registrant, not to mention how/where to change all the settings across different registrants.

I’d also suggest it’s OK to experiment here. That’s how all of us have learned. Pick one with a UI that you don’t hate and a trustable vibe. Maybe your friend also uses that one. Hopefully, it works out fine. If you hate it, it’ll be a little work, but you can always switch.


What is a web host and why do I need one? A Google search throws you a mountain of „best web host” articles and ads. These websites all seem to be full of jargon like „shared hosting” and „managed hosting.” I see things like „suggested hosts” on some sites. How do you find the right web host? I’m not even sure what my needs are. Should I just find the cheapest one?

Just because you own a domain doesn’t mean it will do anything. In fact, right after you buy it, it’s likely that the domain registrant slaps up a „coming soon” page for you:
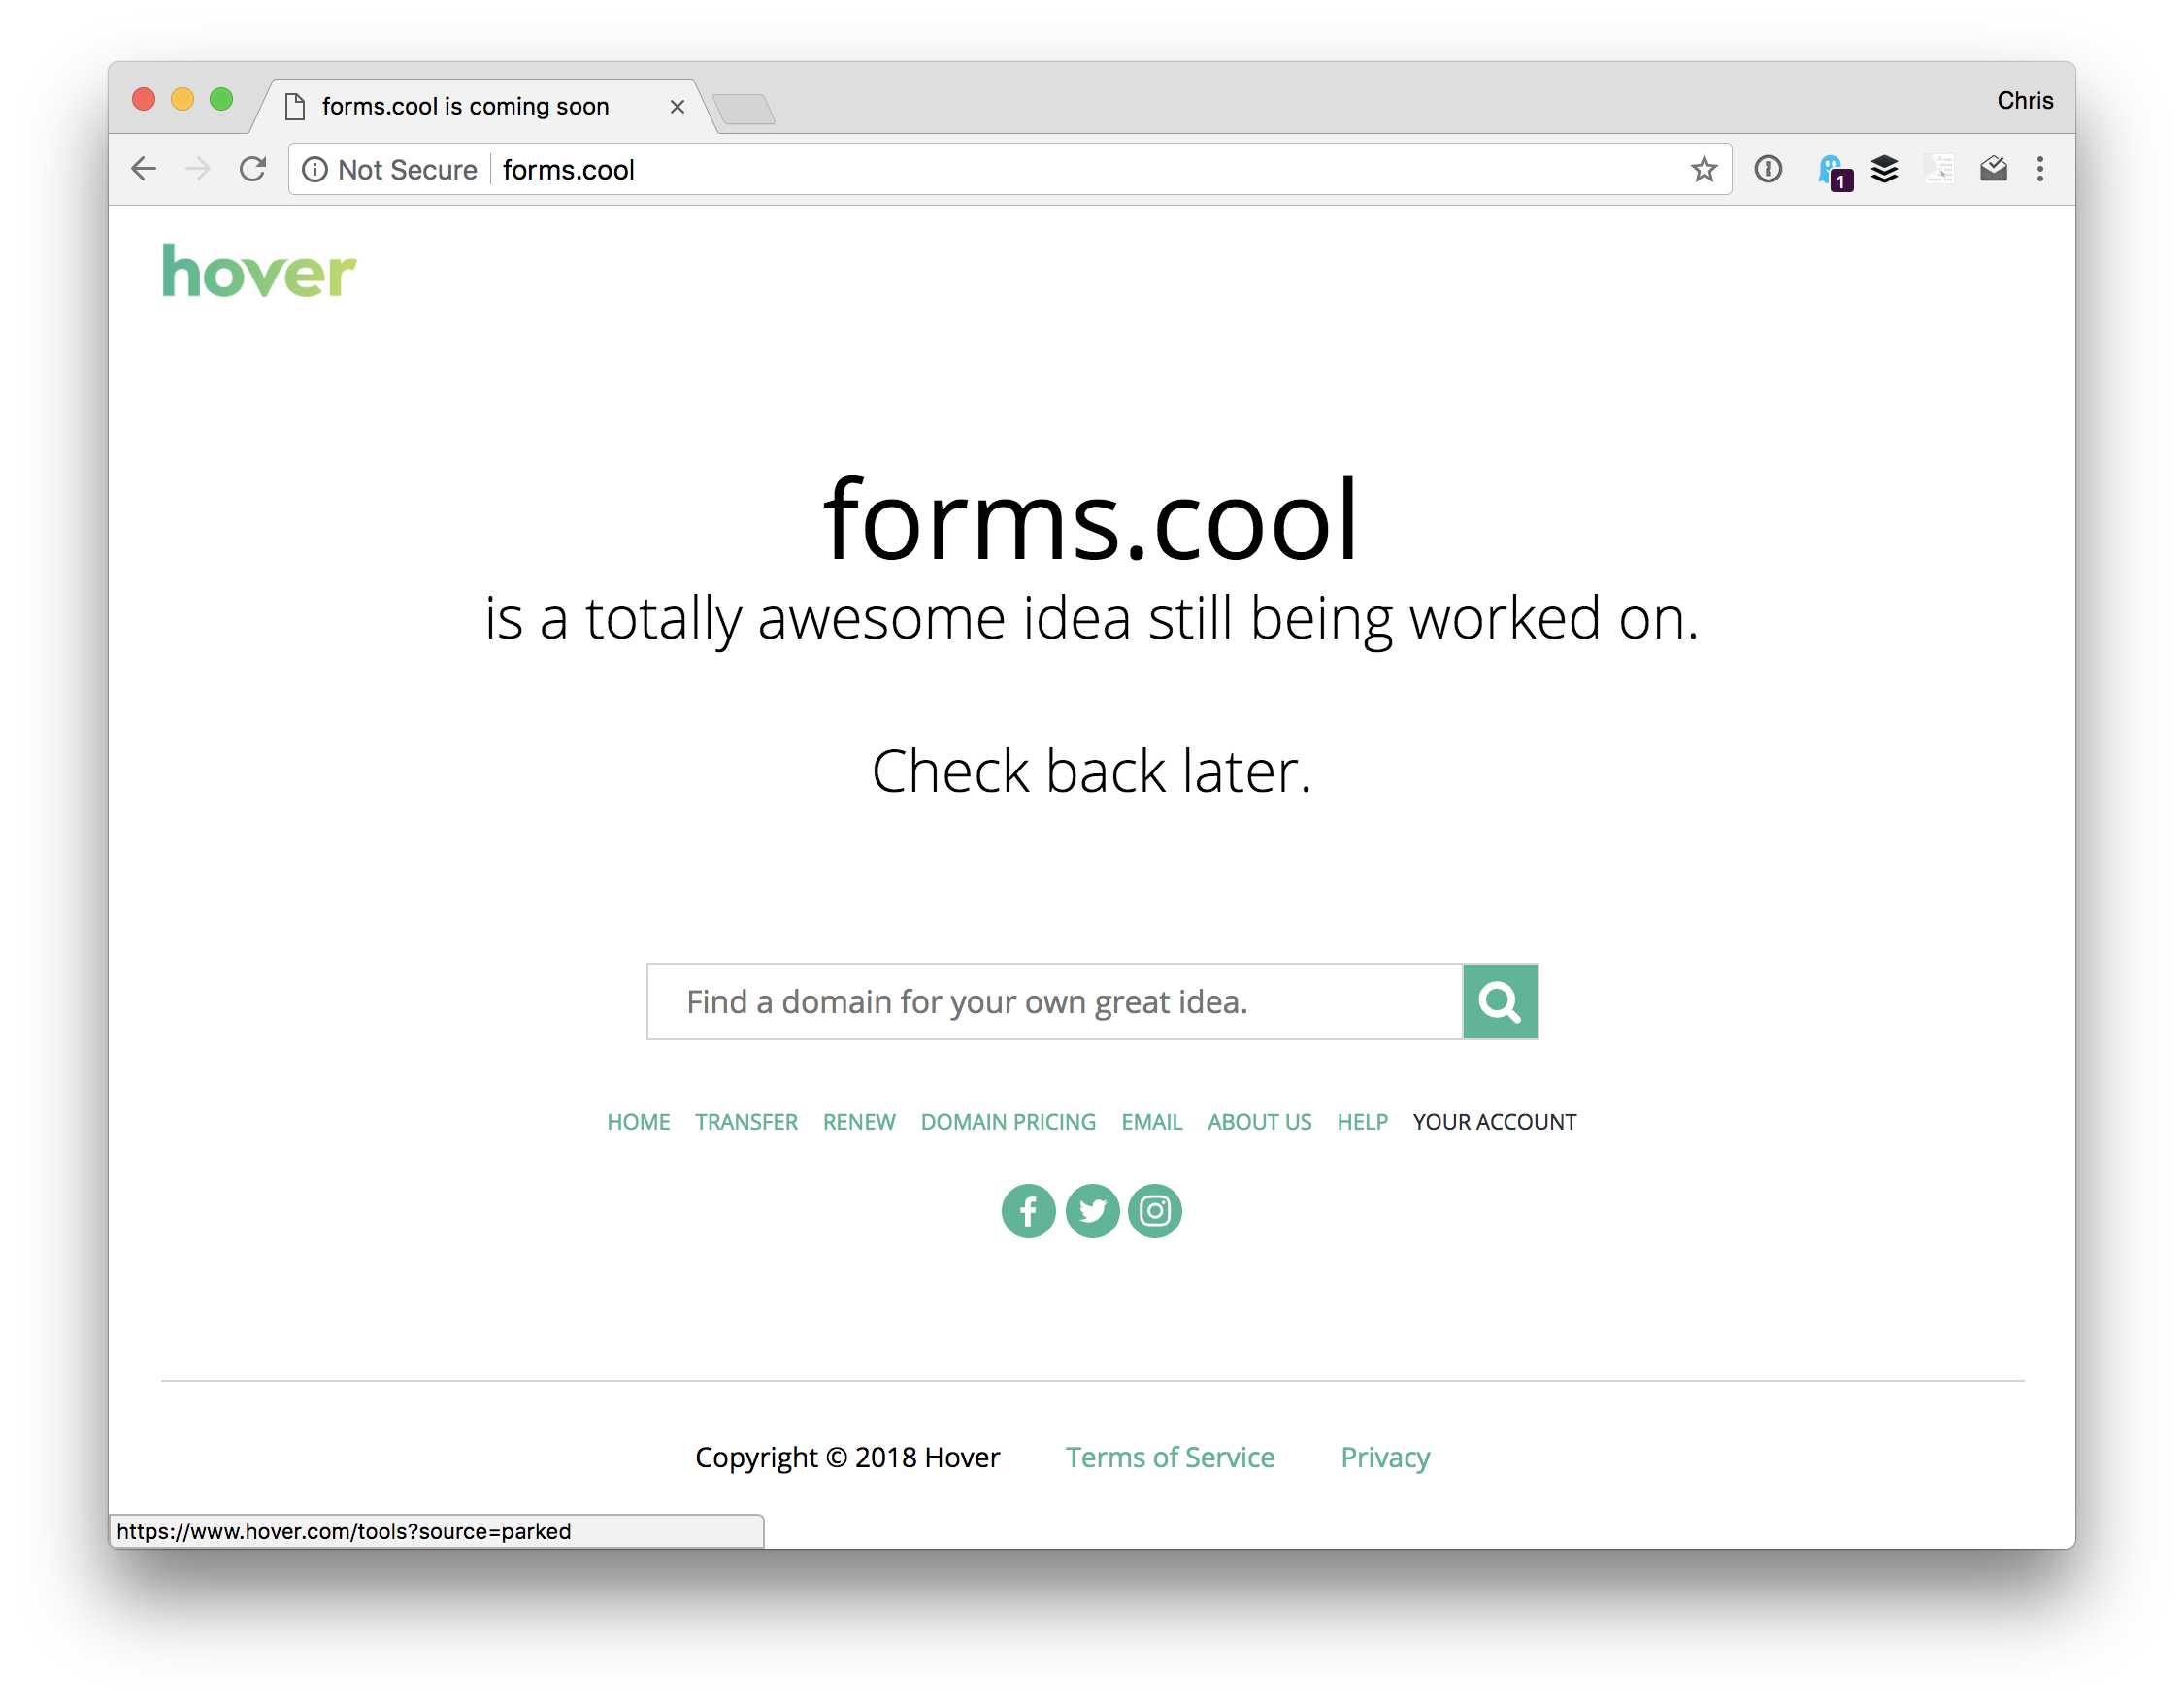
A „coming soon” page you might see immediately after buying a domain name.

To host a website at your new domain, you’ll need to configure the DNS of your new domain to point at a server connected to the internet. Here’s an interesting tidbit… you could do this right from your house if you wanted to. Your Internet Service Provider (ISP) at home probably gives you an IP address. It’s all a bit nerdy, but you could point your domain name at that IP and set up your computer to be a web server that responds to incoming requests and serves up your website. Almost nobody does that though. You don’t want your web server to stop working because you closed your laptop or your ISP changed your IP.

Web hosting services give you that server. Like domain registrants, web hosts are almost a commodity. There are lots of them that provide a similar service, so the price is driven fairly low and they find other things to compete on.

Buying web hosting is a little trickier than buying a domain though. You’ll need to know a little bit about the website you intend to host when making that choice. Will it be a WordPress site? Or another PHP/MySQL-based CMS site (we’ll get to those later)? That means your host will need to support those technologies. Most do, some don’t. You might wanna look in their documentation or literally ask them before pulling the trigger if you are unsure. There are lots of technologies for running websites. Say the site will use Ruby on Rails — that’s a different set of requirements that not all hosts offer. Or Node… Or Python… same story.

If a web host says they specialize in a particular set of technologies, and that’s what you need, that’s probably a decent way to go, particularly in your early days. Let’s take a very limited gander. Again, these are not affiliate or paid-for links and they are somewhat randomly selected web hosts that come to mind for me:

Now here some other web hosts that are a little less traditional. Forgive the techy terms here — if they don’t mean anything to you, just ignore them.

  • Netlify does static site hosting, which is great for things like static site generators and JAMstack sites.
  • Zeit is a host where you interact with it only through the command line.
  • Digital Ocean has their own way of talking about hosting. They call their servers Droplets, which are kind of like virtual machines with extra features.
  • Heroku is great for hosting apps with a ready-to-use backend for things like Node, Ruby, Java, and Python.
  • Amazon Web Services (AWS) is a whole suite of products with specialized hosting focuses, which are for pretty advanced users. Microsoft Azure and Google Cloud are similar.

Again, I’d say it’s OK to, in a sense, make some mistakes here. If you aren’t hosting something particularly mission-critical, like your personal website, pick a host that seems to fit the bill and give it a go. Hopefully, it works out great — if not, you can move. Moving isn’t always super fun, but everybody ends up doing it, and you’ll learn as you go.

When you buy web hosting, that host is going to tell you how to use it. One common way is that the host will give you SFTP credentials. Then you’ll use software that is built for connecting to servers over SFTP, and that will allow you to upload files to the web server.
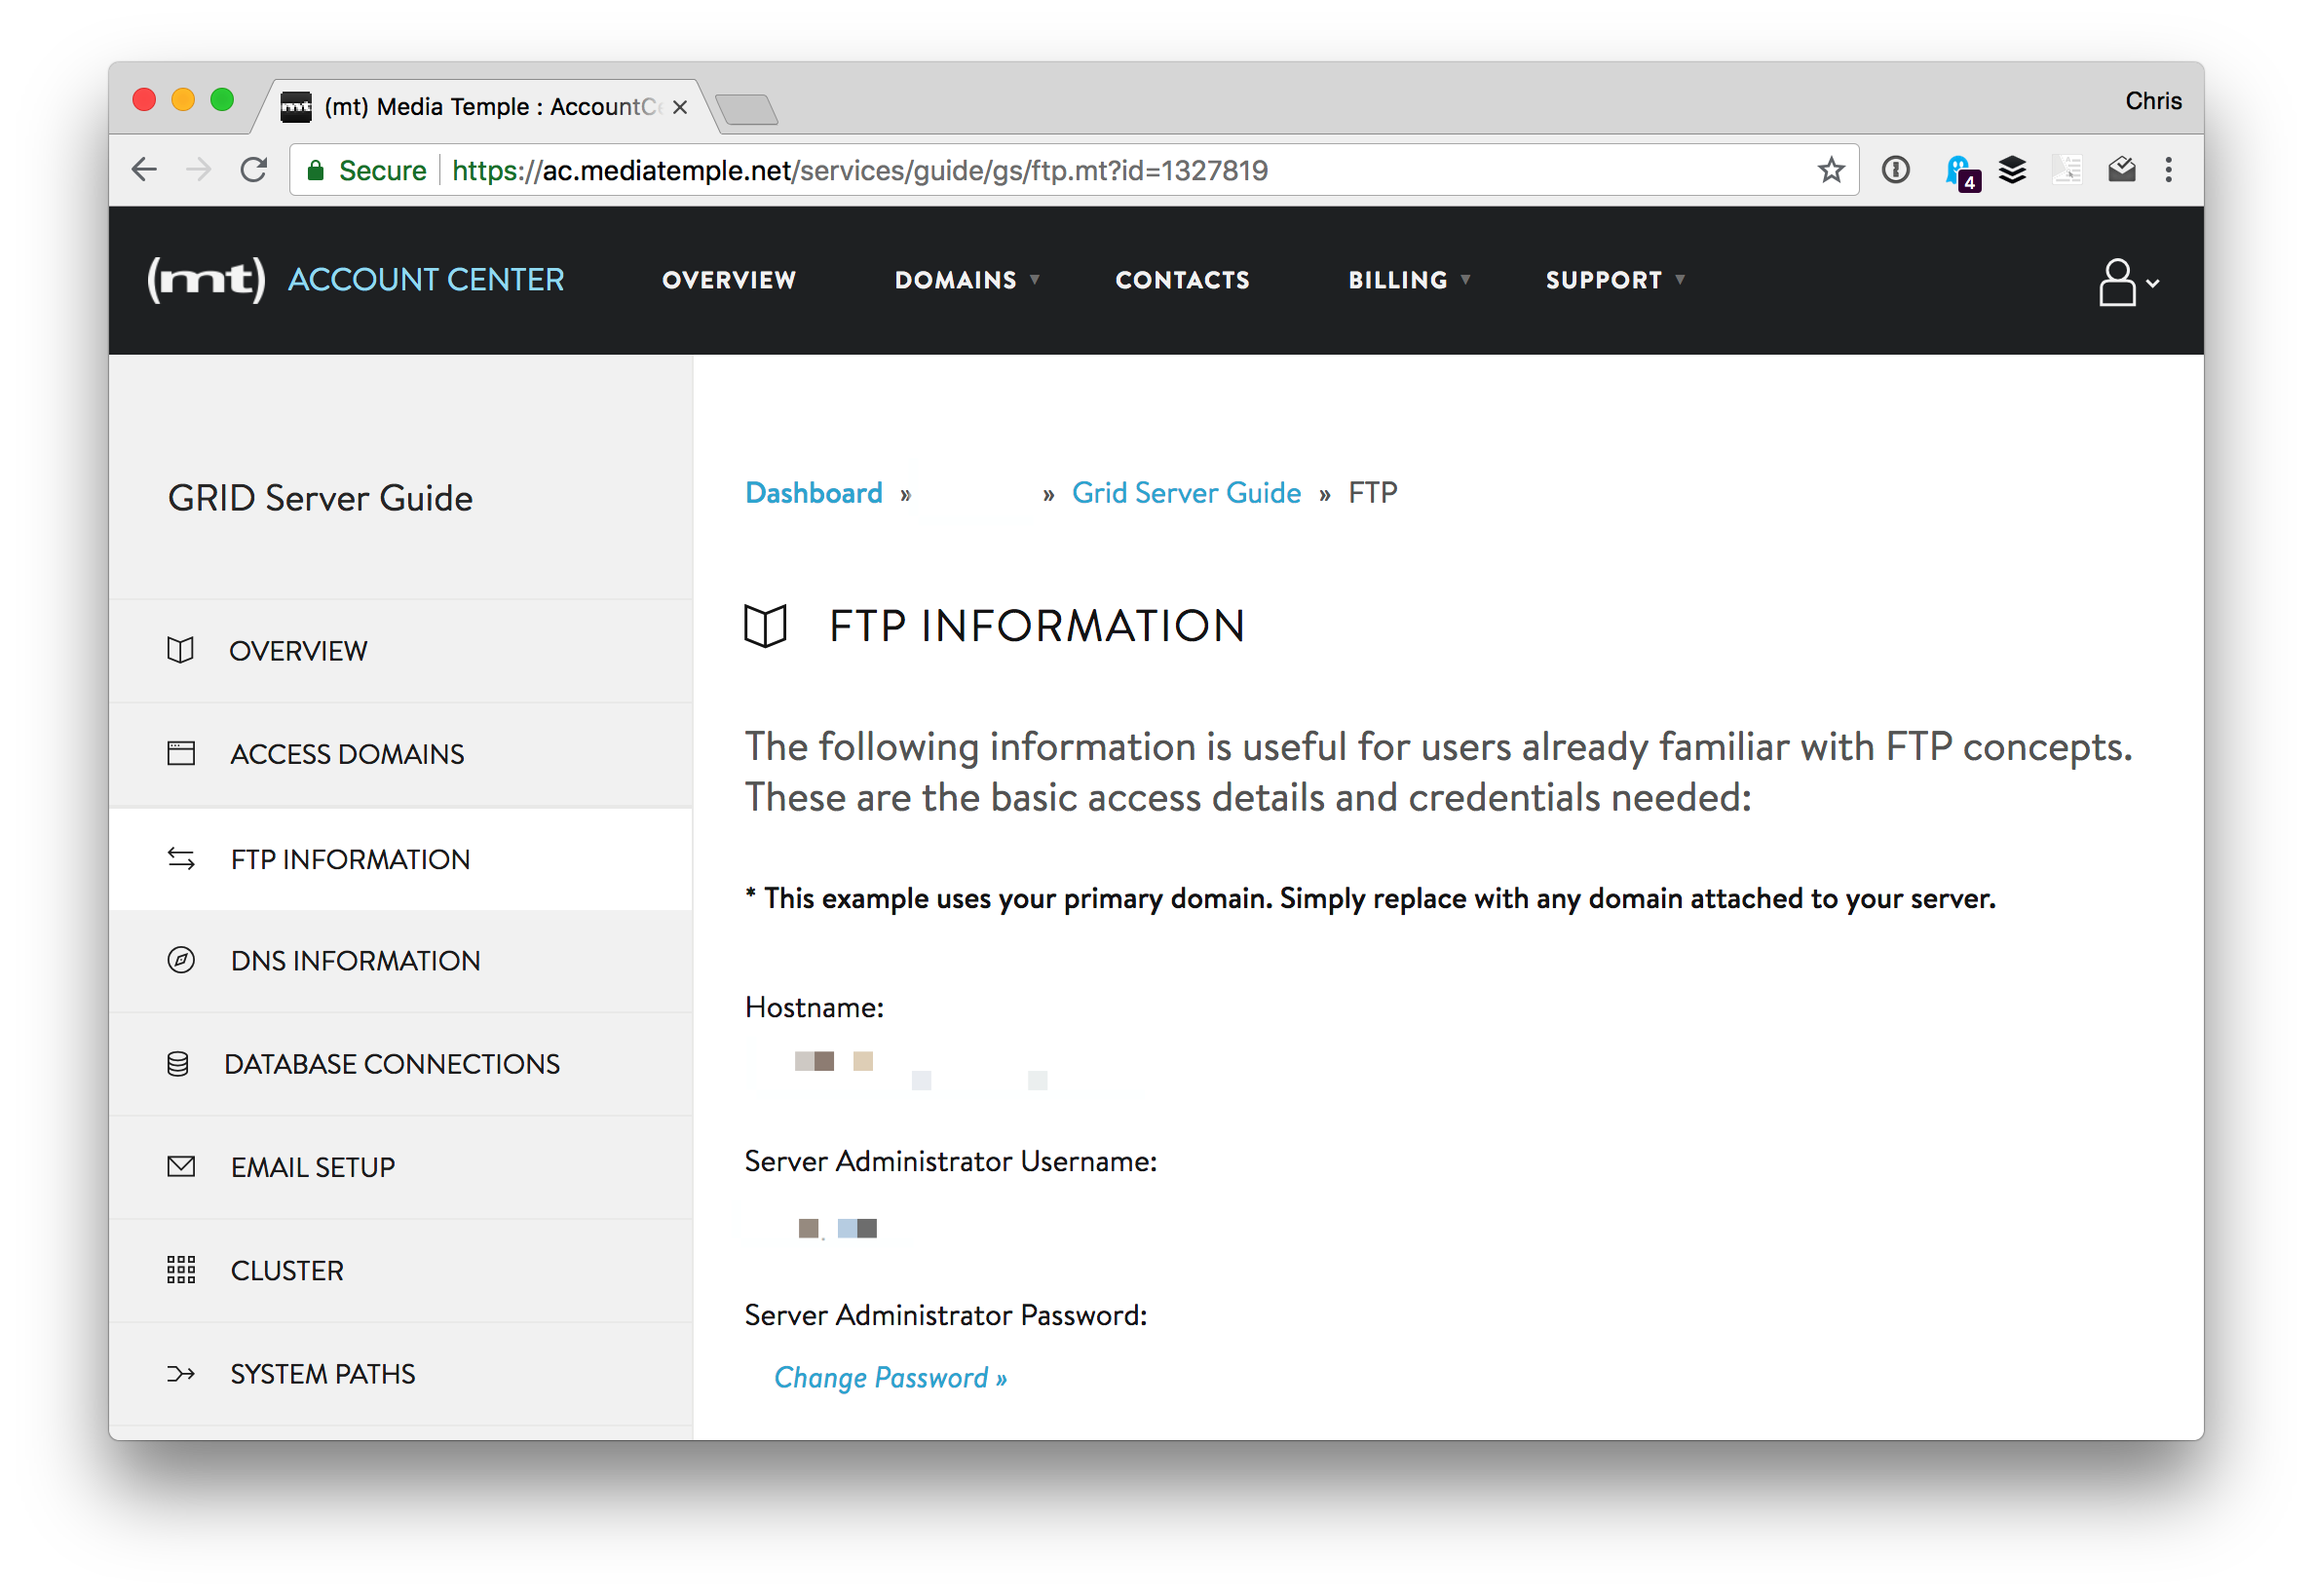
This is a magic moment!

Say you’ve been working on a file that is a single index.html file, that loads a style.css file. Upload those files over SFTP into the folder your host tells you is correct public root directory for that site.

That is the process for taking a site from local to live! There is nothing wrong with it, either. This is referred to as deployment, and this is about as basic and simple as it gets. Even fancier ways of doing deployment sometimes ultimately do just this behind the scenes. We’ll get more into deployment later.


Should you bundle your domain registrar and web host into one if a company offers both?

I mentioned this above a little: I’m a fan of not doing that in general. On one hand, it’s mighty handy. Things like shared billing and a single checkout flow. The host will also do things like configuring the DNS for you to be all set up for their hosting and you probably don’t even have to think about it.

But say the day comes where you just don’t like that host anymore. You’ve found a better deal, outgrown them, were turned off by their support or service, or any other reason. You want to move hosts. The problem is that they aren’t just your host, but your domain registrant, too. Do you leave the domain with them and just move hosts? Probably not, you’re trying to leave them. Now you need to move two things. That makes that move all the more perilous, but worse, this company isn’t exactly incentivized to respond quickly and helpfully to your requests since they know they’re losing you as a customer.

What really is a „CMS”? What’s its purpose? WordPress, Joomla, and Drupal are the most popular names I’ve found for content management systems, and from their descriptions, all sound very similar. What are the kinds of features that set one apart from another? Is a CMS all you need to get your website from your local computer to the public internet?

CMS (Content Management System) is a pretty generic term. It means literally anything that helps you manage content. There are, as you’ve seen, some big players like WordPress and CraftCMS. They don’t really have anything directly to do with that connection between working locally on a site and getting that site live. But they do rather complicate it.

The reason that you’d use a CMS at all is to make working on your site easier. Consider this site you’re looking at right now. There are tens of thousands of pages on this site. It would be untenable for each of them to be a hand-authored file.html file.

Instead, a CMS allows us to craft all those pages by combining data and templates.
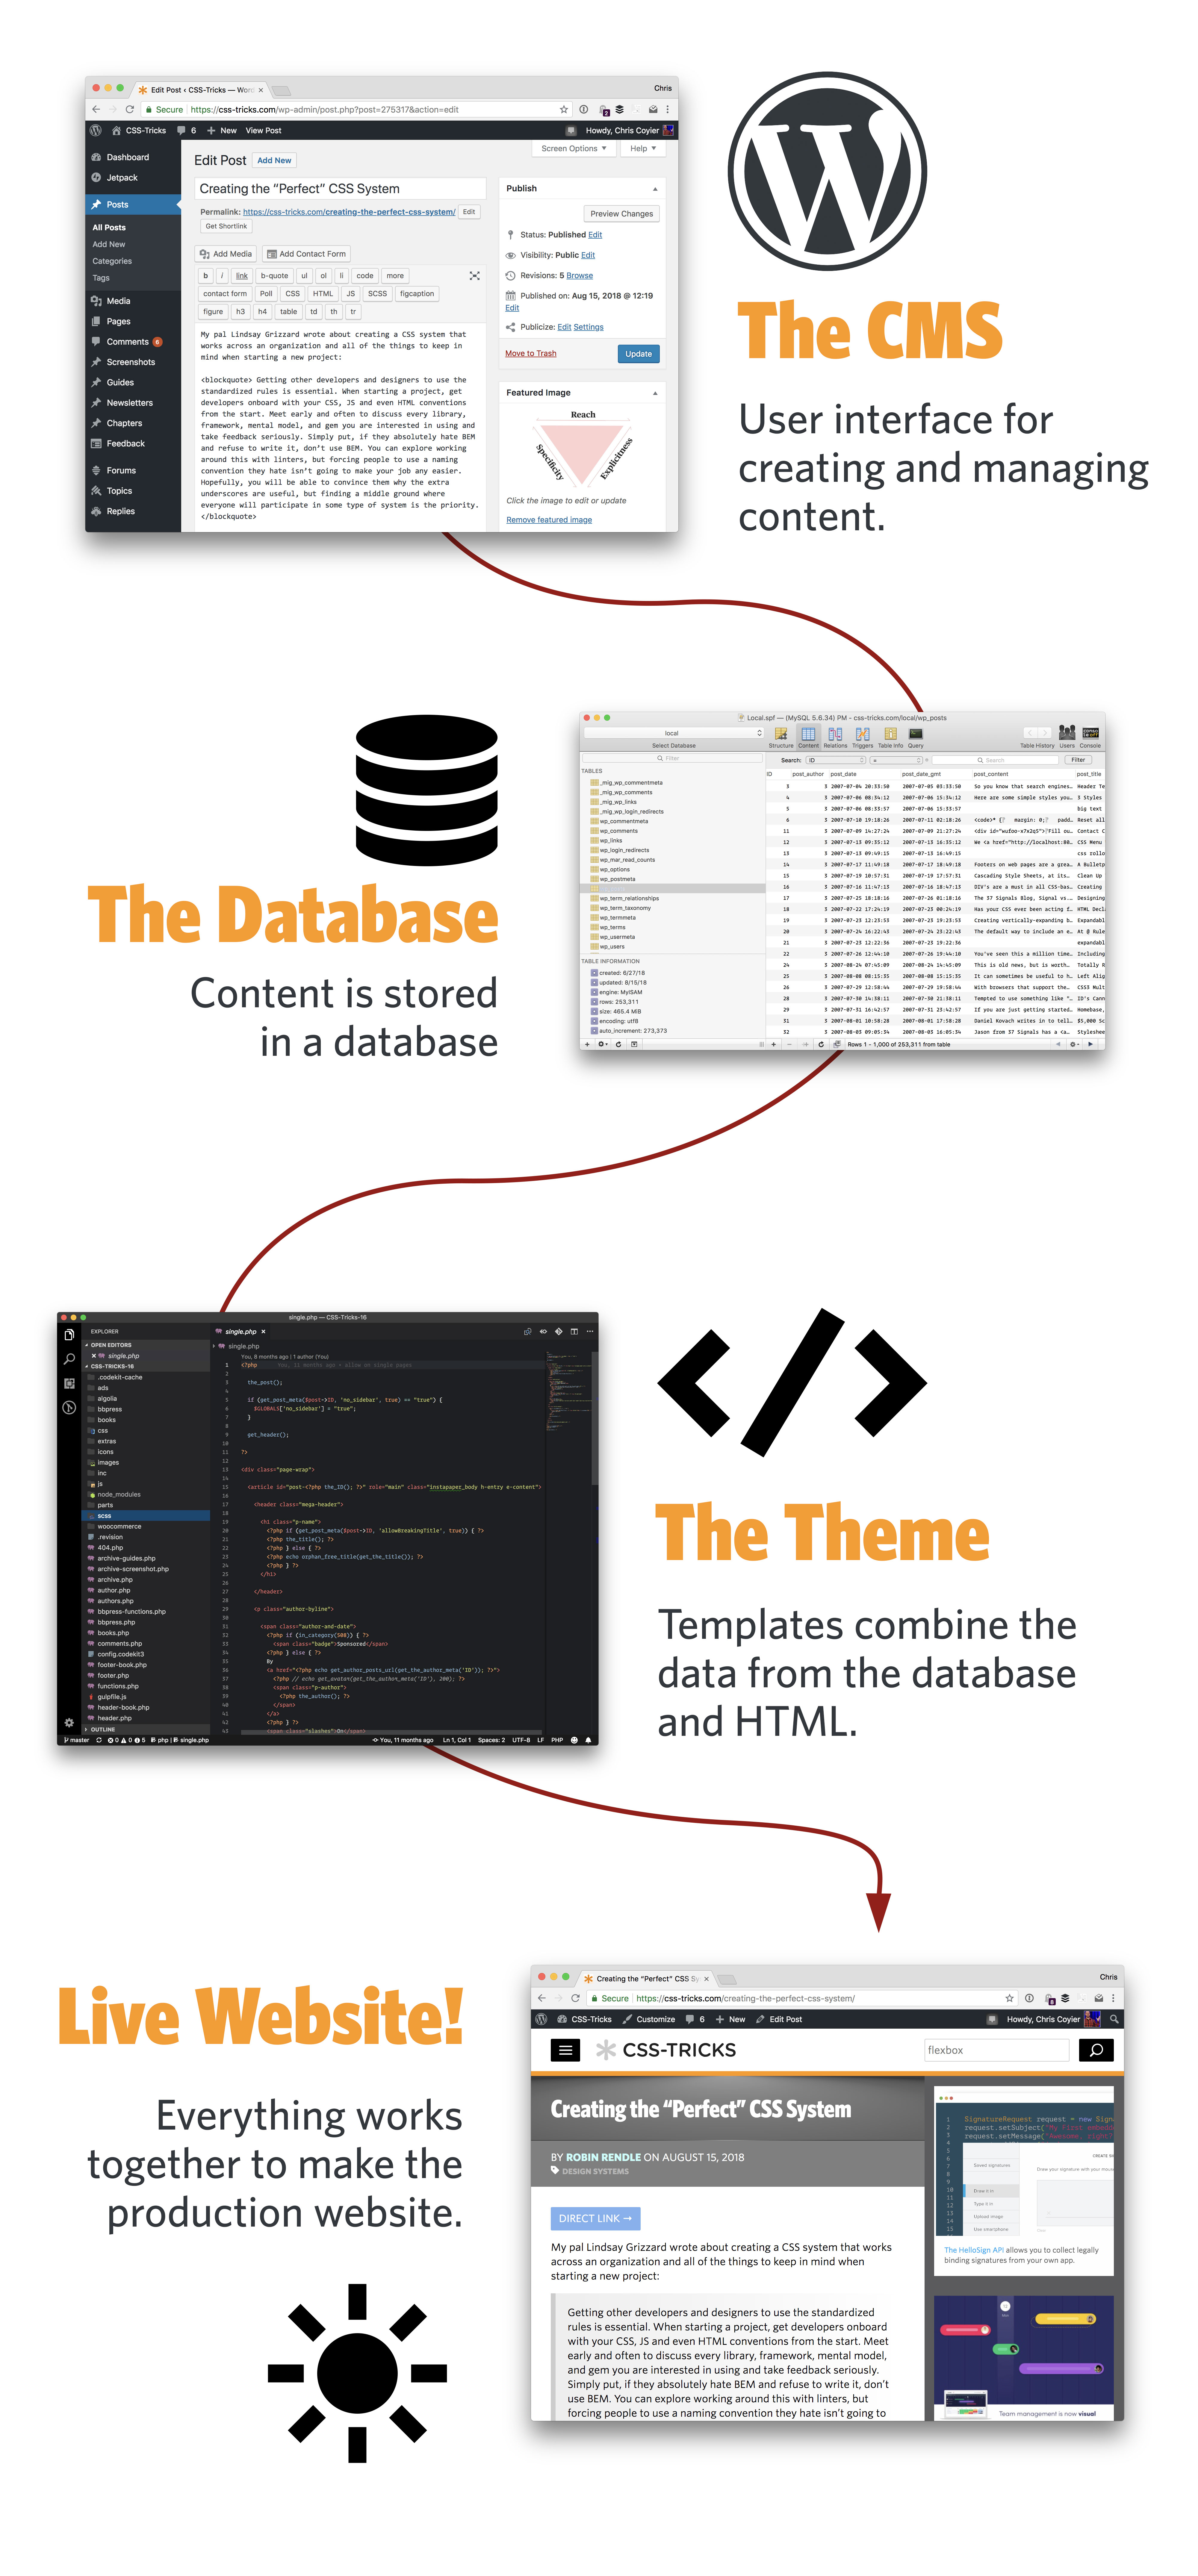
Let’s consider the technology behind WordPress, a CMS that works pretty good for CSS-Tricks. In order for WordPress to run, it needs:

  1. PHP (the back-end language)
  2. MySQL (the database)
  3. Apache (the web server)

You can do all that locally!

I use Local by Flywheel for that (Mac and Windows), but there are a number of ways to get those technologies running: MAMP, Docker, Vagrant, etc.

That’ll get you up and running locally with your CMS. That’s a beautiful thing. Having a good local development environment for your site is crucial. But it doesn’t help you get that site live.

We’ll go over getting all this to a live site a bit later, but you should know this: the web server that you run will need to run these same technologies. Looking at the WordPress example from above, your web server will also need to run PHP, MySQL, and Apache. Then you’ll need to set up a system for getting all your files from your local computer to your web server like you would for any other site, but also probably have a system for dealing with the database. The database is a bit tricky as it’s not a „flat file” like most of the rest of your site.

A CMS could be built from any set of technologies, not just the ones listed above. For example, see KeystoneJS. Instead of PHP, Keystone is Node.js. Instead of MySQL for the database, it uses MongoDB. Instead of Apache, it uses Express. Just a different set of technologies. Both of which you can get running locally and on a live web server.

A CMS could even have no database at all! Static site generators are like this. You get the site running locally, and they produce a set of flat files which you move to your live server. A different way to do things, but absolutely still a CMS. What I always say is that the best CMS is one that is customized to your needs.


What is „Asset Hosting”? Are assets not content? What is the difference between a CMS and an asset hosting service? What does an asset host do?

Let’s define an asset: any „flat” file. As in, not dynamically generated like how a CMS might generate an HTML file. Images are a prime example of an „asset.” But it’s also things like CSS and JavaScript files, as well as videos and PDFs.

And before we get any further: you probably don’t need to worry about this right away. Your web host can host assets and that’s plenty fine for your early days on small sites.

One major reason people go with an asset host (probably more commonly referred to as a CDN or Content Delivery Network) is for a speed boost. Asset hosts are also servers, just like your web host’s web server, but they are designed for hosting those flat file assets super fast. So, not only do those assets get delivered to people looking at your site super fast, but your web server is relieved of that burden.

You could even think of something like YouTube as an asset host. That 100 MB video of a butterfly in your garden is a heavy load for your little web server, and potentially a problem if your outgoing bandwidth is capped like it often is. Uploading that video to YouTube puts your video into that whole social universe, but a big reason to do it other than the social stuff is that it’s hosting that video asset for you.


I’ve heard of „repositories”, but don’t really get what they are. I hear stuff like „just upload it to my Git Repository.” What the heck does that mean? I feel like a moron for asking this. What is Git? What is it for? Do I need to use it? Is it involved in the „local to live” process at all?

Sorry you got hit with a „just” there. There is an epidemic in technology conversations where people slip that in to make it seem like what they are about to say is easy and obvious when it could be neither depending on who is reading.

But let’s get into talking about Git repositories.

Git is a specific form of version control. There are others, but Git is so dominant in the web industry that it’s hardly worth mentioning any others.

Let’s say you and me are working on a website together. We’ve purchased a domain and hosting and gotten the site live. We’ve shared the SFTP credentials so we both have access to change the files on the live site. This could be quite dangerous!
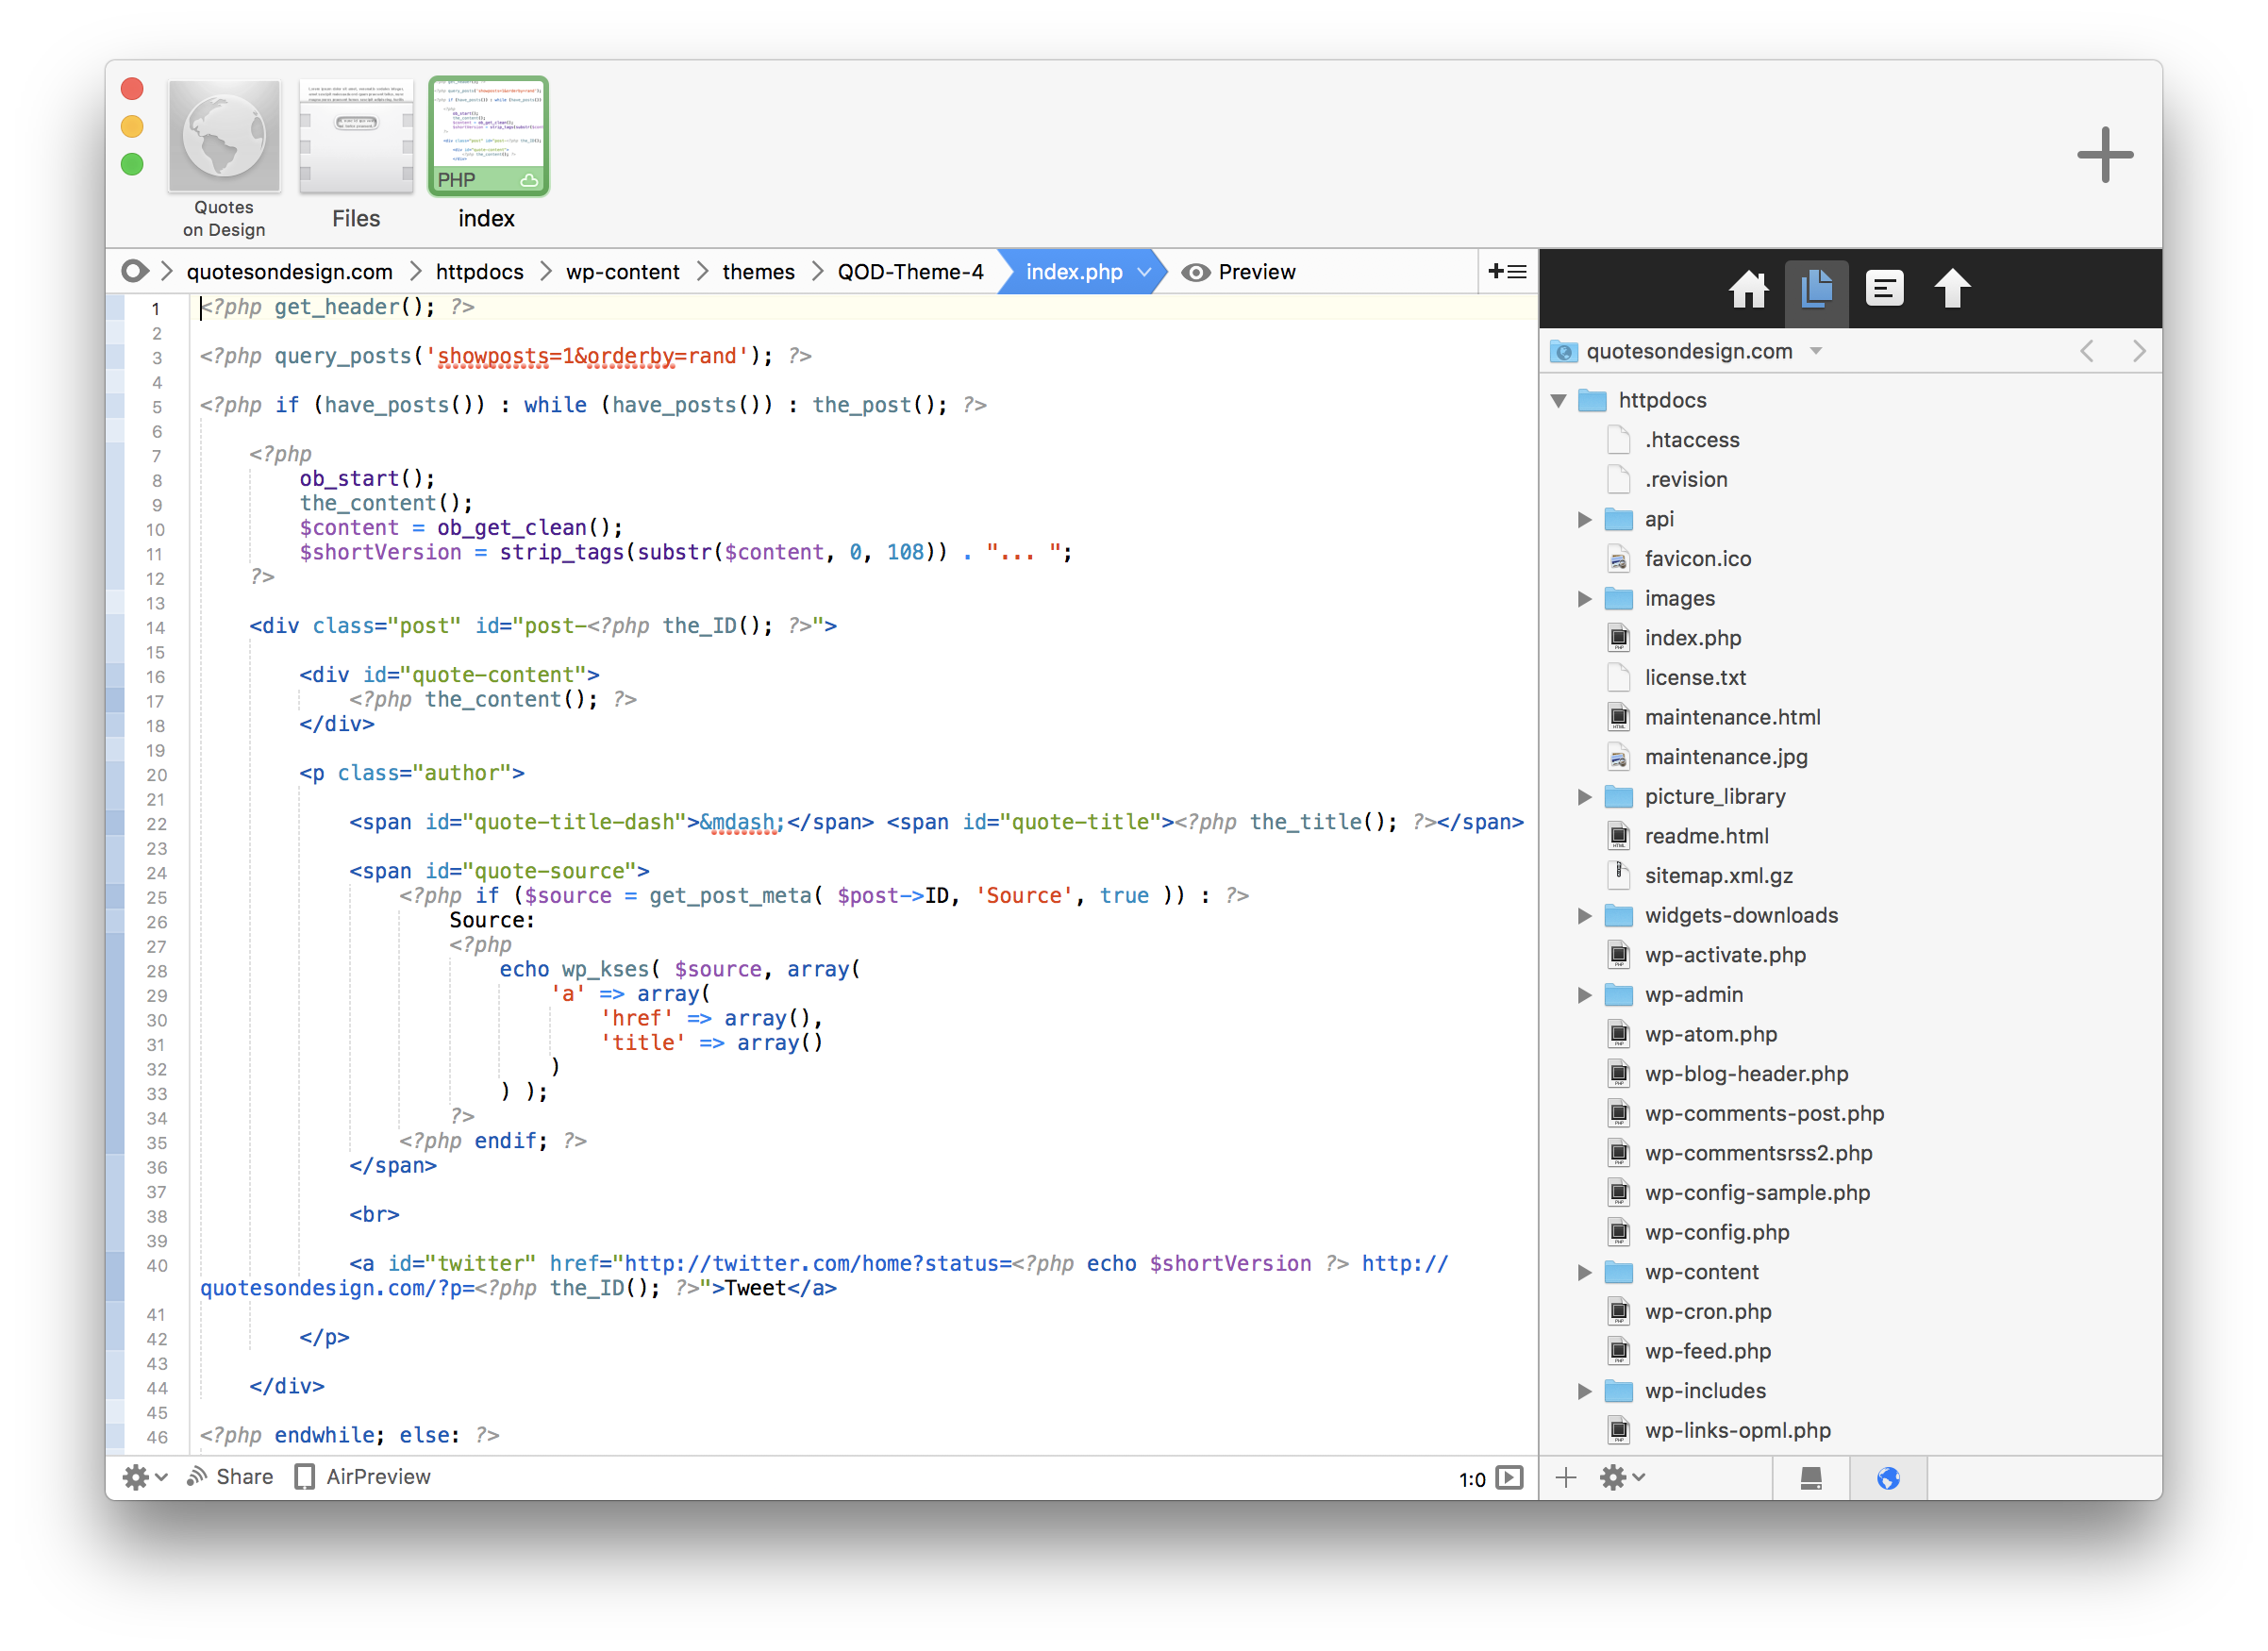
Coda is a code editor that let’s you edit files directly on a sever you’ve connected to over SFTP. Cool, but dangerous!

Say we both edit a file and upload it over SFTP… which change wins? It’s whoever uploaded their file last. We have no idea who has done what. We’re over-writing each other and have no way of staying in sync with each other’s changes, changes immediately affect the live site which could break things and we have no way of undoing changes in case we break things. That’s a situation so unacceptable that it’s really never done.

Instead, we work with version control, like Git. With Git, when we make changes, we commit them to a repository. A repository can be hosted anywhere, even on your local machine. But to make them really useful, they are hosted on the internet somewhere everyone has access to. You’ve surely seen GitHub, which hosts these repositories and adds a bunch of other features like issue tracking. Similar are GitLab and Bitbucket.

Now let’s say you and me are working on that same site, but we’ve set up a Git repository for it. When I make a change, I commit it to the repository. If you want to make a change as well, you have to pull my changes down which merges them into your own copy of the code. Then you can push your changes up to the repository. Like anything, it gets more complicated, but that’s the gist of it.

But a Git repository isn’t the live website. You’re on your own for getting the files from a Git repository to a live site. Fortunately, that’s a situation that everyone faces, so there are lots of options. Good thing your last question is about this!


OK. So now with all that straight… where do you start with going from local to live? Where do you „upload” your HTML, CSS and JavaScript files? How do you link your shiny new domain name to those files and see it out in the wild? Which service is in charge of adding new content to your site, or updating it? Does it get really confusing if you have different companies for each service?

Let’s start with a very simple website on what I’d consider typical web hosting. Say you have just index.html, style.css, and script.js files on your local computer which is your entire website. You’ve purchased a domain name and pointed the DNS settings at a web host. That host has given you SFTP credentials. You’ll use those credentials in an app that allows SFTP connections to log in:
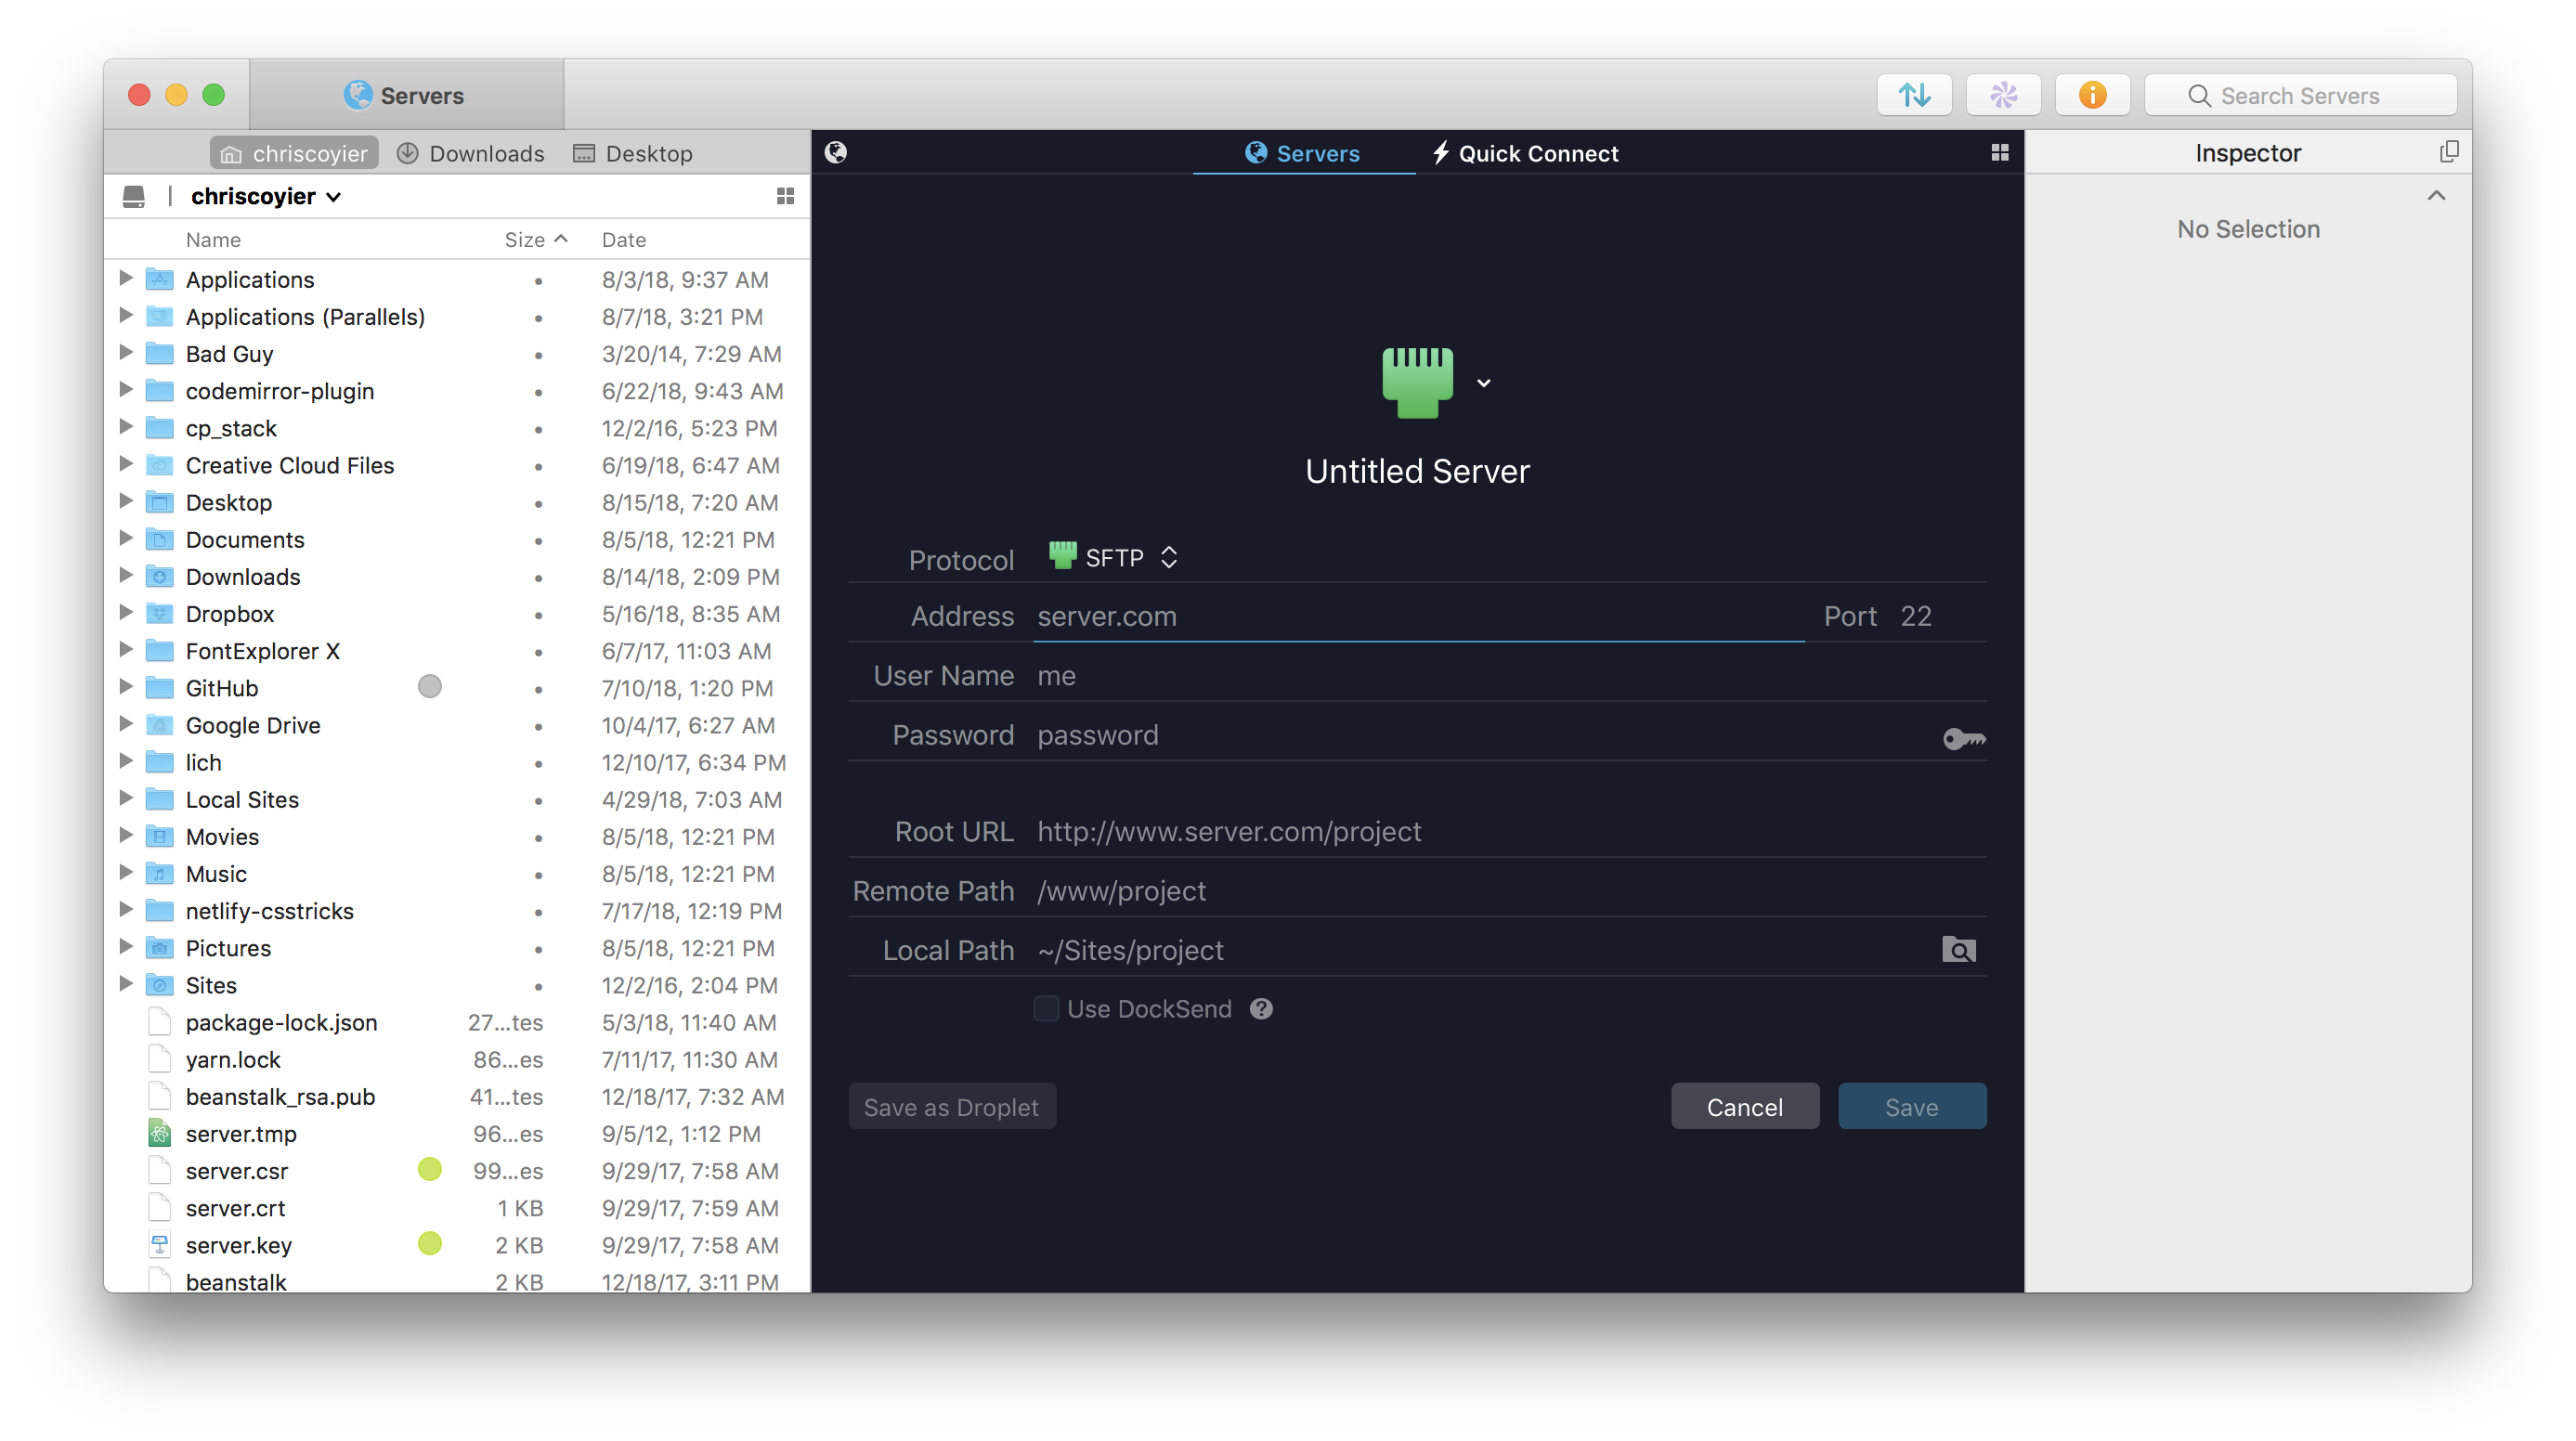
Your host will also tell you which folder is the „public root” of your website. The files there will be out on the public internet for the world to see!
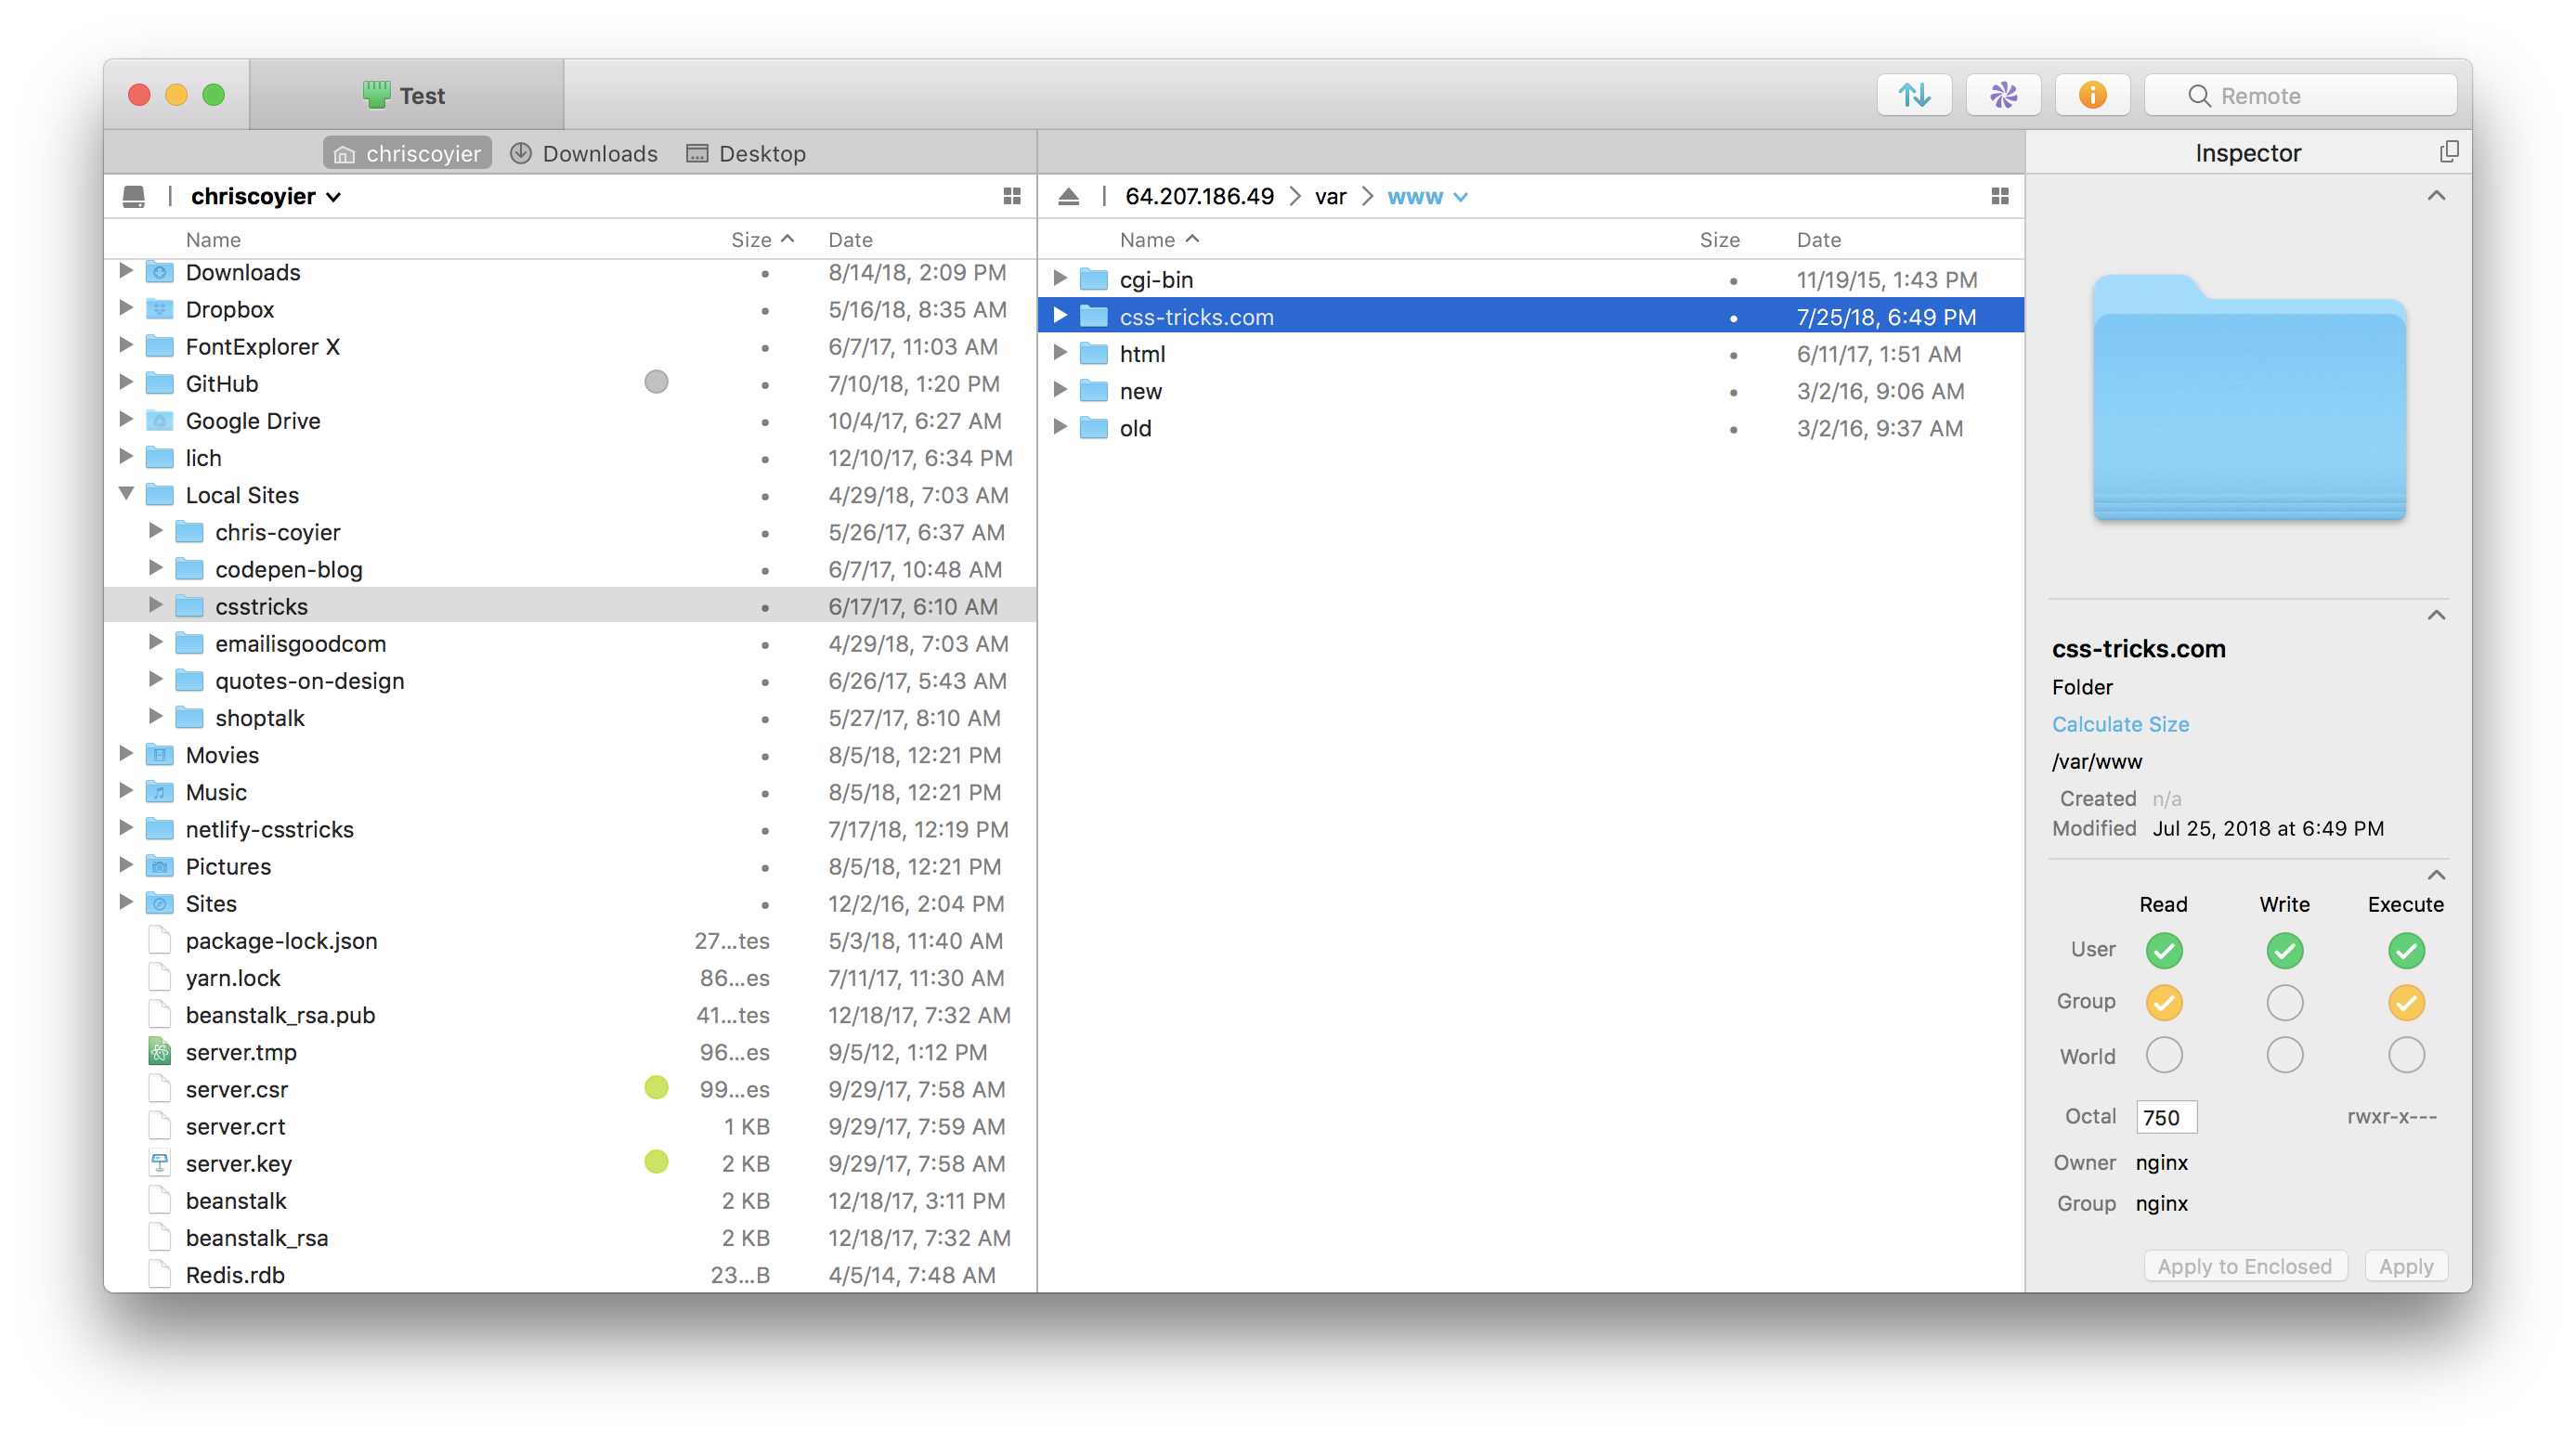
You might hear people refer to the „live” website as a „production” site. When someone asks something like, Did that bug make it to production?” they mean whether the bug is on the live website. „Development” is your local computer. You might also have a „Staging” site, which is a clone of the live website on the same hardware/software of the live site for testing.

Remember earlier when we talked about Git repositories? While the repositories themselves don’t directly help you get the files in them to your web server, most systems that help you with the local-to-live process work with your repositories.

The phrase „local-to-live” refers to deployment. When you have changes that you want to go out to your production website, you deploy them. That’s the process of moving your work from „development” to „production.”

One service that helps with this idea of deployment is Beanstalk. Beanstalk hosts your Git repository, plus you give it the SFTP credentials for your server — that way it can move the files to your web server when you make commits. Cool right? Say you wanted to host that Git repo elsewhere though, like GitHub, Bitbucket, or Gitlab. Check out DeployBoy, which does the same thing, only it can connect to those sites as well. It probably comes as no surprise by now that there are lots of options here, ranging in price and complexity.

Let’s go back to our WordPress example.

  1. You’ve got it running locally (on your computer) just perfectly and now want to go live with it.
  2. You’ve bought a domain name from a registrar.
  3. You’ve purchased hosting that meets WordPress requirements.
  4. You’ve pointed the DNS of the domain name at the web host.
  5. You’ve verified it’s all working (easy way: upload an index.html file in the public root via SFTP and verify that it loads when you type you type the domain name into a browser.)

Now, you’ve still got some work to do:

  1. Set up a Git repository for the site.
  2. Set up a deployment service to move the files from the repository to the live site.
  3. Configure/Set up the live site as needed. For example, you’ll need a database on the live site. You’ll have to create that (your host will have instructions) and do things like run the WordPress installer and update configuration files.
  4. If you have things in your local database that you want to move to the live site, you might be exporting/importing things. That can happen at the raw MySQL level using WordPress’ native import/export features, or a fancy plugin like WP DB Migrate Pro.

It’s a non-trivial amount of work! Sorry. This process is pretty similar for any site though. It’s a matter of configuring and setting up your production web server exactly how it should be, then deploying files to it. Every site is a bit different, but you’ll get the hang of this whole dance.
It really is a big dance. I’ve only painted one picture for you here. I tried to pick one that was generic and broad enough that it shows the landscape of what needs to be done. But, at every step in this dance, there are different ways you can do things, different services you can pick, companies trying to help you at different pain points… it’s an ever-changing world.

Right now, Netlify is enjoying a lot of popularity because they are one of the only web hosts that actually helps you with deployment. They’ll watch your Git repositories and do deployment for you! Netlify is for static sites only, but that can be a whole world onto itself. ZEIT also is massively innovative in how it helps with deploying and hosting web projects, including directly connecting with GitHub.


Good luck!

I hope this was helpful. Remember, you aren’t alone in all this. Zillions of other developers have done this before you and there is help to be found on the internet.

Oh, and remember: the best way to learn anything at all is to…


The post Helping a Beginner Understand Getting a Website Live appeared first on CSS-Tricks.
Helping a Beginner Understand Getting a Website Live

Post pobrano z: Helping a Beginner Understand Getting a Website Live

I got a great email from a fellow named Josh Long the other day. He is, in his words, „relatively new to web design” and was a bit stuck on the concept of getting a site live. I should say that I’m happy to get emails like this an I always read them, but I typically can’t offer tech support over email. If I can respond at all, I normally point people to other community resources.

In this case, it struck me what a perfect moment this is for Josh. He’s a little confused, but he knows enough to be asking a lot of questions and sorting through all this stuff. I figured this was a wonderful opportunity to dig into his questions, hopefully helping him and just maybe helping others in a similar situation.

Here’s one of the original paragraphs Josh sent me, completely unedited:

I’m relatively new to web design, but I’ve taken a few courses on HTML and CSS and I’ve done a Codecademy course on JavaScript. But, (jumping forward probably quite a while here!) after having fully designed and coded a HTML/CSS/JS website or webpage, I don’t fully understand the full process of going from a local site hosted with mamp/wamp to publishing a public site using wordpress(?) or some other host (is WordPress even a host?!) and also finding a server that’s suitable and some way of hosting images/videos or other content. (If that sounded like I didn’t know what half of those meant, it’s because unfortunately I don’t!.. but I’d really like to!)

Can you sense that enthusiasm? I love it.

We worked together a bit to refine many of his questions for this post, but they are still Josh’s words. Here we go!


What is a Domain Registrar? I get they are for registering domain names, but what’s the difference between them? How do you know which one is right for you? A quick search for „best domain hosts” on Google gave me 5 ads for companies who are domain registrars/hosts and 9 „Top 10” style pages that look as though they have some sort of affiliation with at least one company they’re suggesting. Am I just looking for the cheapest one?

You’re exactly right, domain registrants are for registering domain names. If you want joshlongisverycool.com, you’re going to have to buy it, and domain registrants are companies that help you do that.

Searching for a domain name

It’s a bummer that web search results are so saturated by ads and affiliate-link-saturated SEO-jacked pages. You’ll never get total honesty from that because those pages are full of links promoting whoever will pay them the most to send new customers. Heck, even Google themselves will sell you a domain name.

The truth is that you can’t go too wrong here. Domain names are a bit of a commodity and the hundreds of companies that will sell you one largely compete on marketing.

Some things to watch out for:

  • Some companies treat the domain as a loss leader. Like a grocery store selling cheap milk to hope you buy some more stuff while you are there. The check out process at any domain registrant will almost certainly try to sell you a bunch of extra stuff. For example, they might try to sell you additional domain names or email hosting you probably don’t need. Just be careful.
  • Web hosts (which we’re getting to next) will often sell them to you along with hosting. That’s fine I suppose, but I consider it a bit of a conflict of interest. Say you choose to move hosts one day. That hosting company is incentivized in the wrong direction to make that easy for you. If the domain is handled elsewhere, that domain registrant is incentivized the right direction to help you make changes.

I hate to add to the noise for you, but here are some domain registrants that I’ve used personally and aren’t paying for sponsorship here nor are affiliate links:

Our own Sarah Drasner recommends looking at ZEIT domains, which are super interesting in that you buy and manage them entirely over the command line.

I might suggest, if you can see yourself owning several domain names in your life, keeping them consolidated to a single registrant. Managing domains isn’t something you’ll do very often, so it’s easy to lose track of what domains you registered on what registrant, not to mention how/where to change all the settings across different registrants.

I’d also suggest it’s OK to experiment here. That’s how all of us have learned. Pick one with a UI that you don’t hate and a trustable vibe. Maybe your friend also uses that one. Hopefully, it works out fine. If you hate it, it’ll be a little work, but you can always switch.


What is a web host and why do I need one? A Google search throws you a mountain of „best web host” articles and ads. These websites all seem to be full of jargon like „shared hosting” and „managed hosting.” I see things like „suggested hosts” on some sites. How do you find the right web host? I’m not even sure what my needs are. Should I just find the cheapest one?

Just because you own a domain doesn’t mean it will do anything. In fact, right after you buy it, it’s likely that the domain registrant slaps up a „coming soon” page for you:

A „coming soon” page you might see immediately after buying a domain name.

To host a website at your new domain, you’ll need to configure the DNS of your new domain to point at a server connected to the internet. Here’s an interesting tidbit… you could do this right from your house if you wanted to. Your Internet Service Provider (ISP) at home probably gives you an IP address. It’s all a bit nerdy, but you could point your domain name at that IP and set up your computer to be a web server that responds to incoming requests and serves up your website. Almost nobody does that though. You don’t want your web server to stop working because you closed your laptop or your ISP changed your IP.

Web hosting services give you that server. Like domain registrants, web hosts are almost a commodity. There are lots of them that provide a similar service, so the price is driven fairly low and they find other things to compete on.

Buying web hosting is a little trickier than buying a domain though. You’ll need to know a little bit about the website you intend to host when making that choice. Will it be a WordPress site? Or another PHP/MySQL-based CMS site (we’ll get to those later)? That means your host will need to support those technologies. Most do, some don’t. You might wanna look in their documentation or literally ask them before pulling the trigger if you are unsure. There are lots of technologies for running websites. Say the site will use Ruby on Rails — that’s a different set of requirements that not all hosts offer. Or Node… Or Python… same story.

If a web host says they specialize in a particular set of technologies, and that’s what you need, that’s probably a decent way to go, particularly in your early days. Let’s take a very limited gander. Again, these are not affiliate or paid-for links and they are somewhat randomly selected web hosts that come to mind for me:

Now here some other web hosts that are a little less traditional. Forgive the techy terms here — if they don’t mean anything to you, just ignore them.

  • Netlify does static site hosting, which is great for things like static site generators and JAMstack sites.
  • Zeit is a host where you interact with it only through the command line.
  • Digital Ocean has their own way of talking about hosting. They call their servers Droplets, which are kind of like virtual machines with extra features.
  • Heroku is great for hosting apps with a ready-to-use backend for things like Node, Ruby, Java, and Python.
  • Amazon Web Services (AWS) is a whole suite of products with specialized hosting focuses, which are for pretty advanced users. Microsoft Azure and Google Cloud are similar.

Again, I’d say it’s OK to, in a sense, make some mistakes here. If you aren’t hosting something particularly mission-critical, like your personal website, pick a host that seems to fit the bill and give it a go. Hopefully, it works out great — if not, you can move. Moving isn’t always super fun, but everybody ends up doing it, and you’ll learn as you go.

When you buy web hosting, that host is going to tell you how to use it. One common way is that the host will give you SFTP credentials. Then you’ll use software that is built for connecting to servers over SFTP, and that will allow you to upload files to the web server.

This is a magic moment!

Say you’ve been working on a file that is a single index.html file, that loads a style.css file. Upload those files over SFTP into the folder your host tells you is correct public root directory for that site.

That is the process for taking a site from local to live! There is nothing wrong with it, either. This is referred to as deployment, and this is about as basic and simple as it gets. Even fancier ways of doing deployment sometimes ultimately do just this behind the scenes. We’ll get more into deployment later.


Should you bundle your domain registrar and web host into one if a company offers both?

I mentioned this above a little: I’m a fan of not doing that in general. On one hand, it’s mighty handy. Things like shared billing and a single checkout flow. The host will also do things like configuring the DNS for you to be all set up for their hosting and you probably don’t even have to think about it.

But say the day comes where you just don’t like that host anymore. You’ve found a better deal, outgrown them, were turned off by their support or service, or any other reason. You want to move hosts. The problem is that they aren’t just your host, but your domain registrant, too. Do you leave the domain with them and just move hosts? Probably not, you’re trying to leave them. Now you need to move two things. That makes that move all the more perilous, but worse, this company isn’t exactly incentivized to respond quickly and helpfully to your requests since they know they’re losing you as a customer.


What really is a „CMS”? What’s its purpose? WordPress, Joomla, and Drupal are the most popular names I’ve found for content management systems, and from their descriptions, all sound very similar. What are the kinds of features that set one apart from another? Is a CMS all you need to get your website from your local computer to the public internet?

CMS (Content Management System) is a pretty generic term. It means literally anything that helps you manage content. There are, as you’ve seen, some big players like WordPress and CraftCMS. They don’t really have anything directly to do with that connection between working locally on a site and getting that site live. But they do rather complicate it.

The reason that you’d use a CMS at all is to make working on your site easier. Consider this site you’re looking at right now. There are tens of thousands of pages on this site. It would be untenable for each of them to be a hand-authored file.html file.

Instead, a CMS allows us to craft all those pages by combining data and templates.

Let’s consider the technology behind WordPress, a CMS that works pretty good for CSS-Tricks. In order for WordPress to run, it needs:

  1. PHP (the back-end language)
  2. MySQL (the database)
  3. Apache (the web server)

You can do all that locally!

I use Local by Flywheel for that (Mac and Windows), but there are a number of ways to get those technologies running: MAMP, Docker, Vagrant, etc.

That’ll get you up and running locally with your CMS. That’s a beautiful thing. Having a good local development environment for your site is crucial. But it doesn’t help you get that site live.

We’ll go over getting all this to a live site a bit later, but you should know this: the web server that you run will need to run these same technologies. Looking at the WordPress example from above, your web server will also need to run PHP, MySQL, and Apache. Then you’ll need to set up a system for getting all your files from your local computer to your web server like you would for any other site, but also probably have a system for dealing with the database. The database is a bit tricky as it’s not a „flat file” like most of the rest of your site.

A CMS could be built from any set of technologies, not just the ones listed above. For example, see KeystoneJS. Instead of PHP, Keystone is Node.js. Instead of MySQL for the database, it uses MongoDB. Instead of Apache, it uses Express. Just a different set of technologies. Both of which you can get running locally and on a live web server.

A CMS could even have no database at all! Static site generators are like this. You get the site running locally, and they produce a set of flat files which you move to your live server. A different way to do things, but absolutely still a CMS. What I always say is that the best CMS is one that is customized to your needs.


What is „Asset Hosting”? Are assets not content? What is the difference between a CMS and an asset hosting service? What does an asset host do?

Let’s define an asset: any „flat” file. As in, not dynamically generated like how a CMS might generate an HTML file. Images are a prime example of an „asset.” But it’s also things like CSS and JavaScript files, as well as videos and PDFs.

And before we get any further: you probably don’t need to worry about this right away. Your web host can host assets and that’s plenty fine for your early days on small sites.

One major reason people go with an asset host (probably more commonly referred to as a CDN or Content Delivery Network) is for a speed boost. Asset hosts are also servers, just like your web host’s web server, but they are designed for hosting those flat file assets super fast. So, not only do those assets get delivered to people looking at your site super fast, but your web server is relieved of that burden.

You could even think of something like YouTube as an asset host. That 100 MB video of a butterfly in your garden is a heavy load for your little web server, and potentially a problem if your outgoing bandwidth is capped like it often is. Uploading that video to YouTube puts your video into that whole social universe, but a big reason to do it other than the social stuff is that it’s hosting that video asset for you.


I’ve heard of „repositories”, but don’t really get what they are. I hear stuff like „just upload it to my Git Repository.” What the heck does that mean? I feel like a moron for asking this. What is Git? What is it for? Do I need to use it? Is it involved in the „local to live” process at all?

Sorry you got hit with a „just” there. There is an epidemic in technology conversations where people slip that in to make it seem like what they are about to say is easy and obvious when it could be neither depending on who is reading.

But let’s get into talking about Git repositories.

Git is a specific form of version control. There are others, but Git is so dominant in the web industry that it’s hardly worth mentioning any others.

Let’s say you and me are working on a website together. We’ve purchased a domain and hosting and gotten the site live. We’ve shared the SFTP credentials so we both have access to change the files on the live site. This could be quite dangerous!

Coda is a code editor that let’s you edit files directly on a sever you’ve connected to over SFTP. Cool, but dangerous!

Say we both edit a file and upload it over SFTP… which change wins? It’s whoever uploaded their file last. We have no idea who has done what. We’re over-writing each other and have no way of staying in sync with each other’s changes, changes immediately affect the live site which could break things and we have no way of undoing changes in case we break things. That’s a situation so unacceptable that it’s really never done.

Instead, we work with version control, like Git. With Git, when we make changes, we commit them to a repository. A repository can be hosted anywhere, even on your local machine. But to make them really useful, they are hosted on the internet somewhere everyone has access to. You’ve surely seen GitHub, which hosts these repositories and adds a bunch of other features like issue tracking. Similar are GitLab and Bitbucket.

Now let’s say you and me are working on that same site, but we’ve set up a Git repository for it. When I make a change, I commit it to the repository. If you want to make a change as well, you have to pull my changes down which merges them into your own copy of the code. Then you can push your changes up to the repository. Like anything, it gets more complicated, but that’s the gist of it.

But a Git repository isn’t the live website. You’re on your own for getting the files from a Git repository to a live site. Fortunately, that’s a situation that everyone faces, so there are lots of options. Good thing your last question is about this!


OK. So now with all that straight… where do you start with going from local to live? Where do you „upload” your HTML, CSS and JavaScript files? How do you link your shiny new domain name to those files and see it out in the wild? Which service is in charge of adding new content to your site, or updating it? Does it get really confusing if you have different companies for each service?

Let’s start with a very simple website on what I’d consider typical web hosting. Say you have just index.html, style.css, and script.js files on your local computer which is your entire website. You’ve purchased a domain name and pointed the DNS settings at a web host. That host has given you SFTP credentials. You’ll use those credentials in an app that allows SFTP connections to log in:

Your host will also tell you which folder is the „public root” of your website. The files there will be out on the public internet for the world to see!

You might hear people refer to the „live” website as a „production” site. When someone asks something like, Did that bug make it to production?” they mean whether the bug is on the live website. „Development” is your local computer. You might also have a „Staging” site, which is a clone of the live website on the same hardware/software of the live site for testing.

Remember earlier when we talked about Git repositories? While the repositories themselves don’t directly help you get the files in them to your web server, most systems that help you with the local-to-live process work with your repositories.

The phrase „local-to-live” refers to deployment. When you have changes that you want to go out to your production website, you deploy them. That’s the process of moving your work from „development” to „production.”

One service that helps with this idea of deployment is Beanstalk. Beanstalk hosts your Git repository, plus you give it the SFTP credentials for your server — that way it can move the files to your web server when you make commits. Cool right? Say you wanted to host that Git repo elsewhere though, like GitHub, Bitbucket, or Gitlab. Check out DeployBoy, which does the same thing, only it can connect to those sites as well. It probably comes as no surprise by now that there are lots of options here, ranging in price and complexity.

Let’s go back to our WordPress example.

  1. You’ve got it running locally (on your computer) just perfectly and now want to go live with it.
  2. You’ve bought a domain name from a registrar.
  3. You’ve purchased hosting that meets WordPress requirements.
  4. You’ve pointed the DNS of the domain name at the web host.
  5. You’ve verified it’s all working (easy way: upload an index.html file in the public root via SFTP and verify that it loads when you type you type the domain name into a browser.)

Now, you’ve still got some work to do:

  1. Set up a Git repository for the site.
  2. Set up a deployment service to move the files from the repository to the live site.
  3. Configure/Set up the live site as needed. For example, you’ll need a database on the live site. You’ll have to create that (your host will have instructions) and do things like run the WordPress installer and update configuration files.
  4. If you have things in your local database that you want to move to the live site, you might be exporting/importing things. That can happen at the raw MySQL level using WordPress’ native import/export features, or a fancy plugin like WP DB Migrate Pro.

It’s a non-trivial amount of work! Sorry. This process is pretty similar for any site though. It’s a matter of configuring and setting up your production web server exactly how it should be, then deploying files to it. Every site is a bit different, but you’ll get the hang of this whole dance.

It really is a big dance. I’ve only painted one picture for you here. I tried to pick one that was generic and broad enough that it shows the landscape of what needs to be done. But, at every step in this dance, there are different ways you can do things, different services you can pick, companies trying to help you at different pain points… it’s an ever-changing world.

Right now, Netlify is enjoying a lot of popularity because they are one of the only web hosts that actually helps you with deployment. They’ll watch your Git repositories and do deployment for you! Netlify is for static sites only, but that can be a whole world onto itself. ZEIT also is massively innovative in how it helps with deploying and hosting web projects, including directly connecting with GitHub.


Good luck!

I hope this was helpful. Remember, you aren’t alone in all this. Zillions of other developers have done this before you and there is help to be found on the internet.

Oh, and remember: the best way to learn anything at all is to…


The post Helping a Beginner Understand Getting a Website Live appeared first on CSS-Tricks.
Level up your hosting. Get started on DigitalOcean with $100.

Post pobrano z: Level up your hosting. Get started on DigitalOcean with $100.

(This is a sponsored post.)

Tired of slow, unreliable web hosting? See how easy it is to self-host your next project on DigitalOcean’s cloud platform. Build and manage ultra-fast websites, blogs, and other static web pages using our user-friendly control panel or simple API, all with a 99.99% uptime SLA. Save time using our One-Click install apps for WordPress, Ghost and Discourse. Never worry about running out of storage space again with Spaces — highly scalable, affordable object storage.

Sign up today with a free $100 credit for CSS-Tricks readers.

Direct Link to Article — Permalink

The post Level up your hosting. Get started on DigitalOcean with $100. appeared first on CSS-Tricks.

Working With Events in React

Post pobrano z: Working With Events in React

Most of the behavior in an application revolves around events. User enters a value in the registration form? Event. User hits the submit button? Another event. Events are triggered a number of ways and we build applications to listen for them in order to do something else in response.

You may already be super comfortable working with events based on your existing JavaScript experience. However, React has a distinct way of handling them. Rather than directly targeting DOM events, React wraps them in their own event wrapper. But we’ll get into that.

Let’s go over how to create, add and listen for events in React.

Creating Events

We’ll start by creating a form that has an input and a button. An event will be triggered when a value is entered. The button is used to call a function which will reverse that value.

Here’s how it’ll work:

  • An empty input field allows the user to enter text.
  • An onChange event is triggered when values are entered in the input. This calls a function — handleChange() — that is used to set a new state for the input.
  • When the „Reverse Text” button is clicked, another event is triggered. This calls a function — handleReverse() — to set a new state for reversedText.

Here’s that translated into code:

class App extends React.Component {
  state = {
    /*  Initial State */
    input: "",
    reversedText: ""
  };

  /* handleChange() function to set a new state for input */
  handleChange = event => {
    const value = event.target.value;
    this.setState({
      input: value
    });
  };

  /* handleReverse() function to reverse the input and set that as new state for reversedText */
  handleReverse = event => {
    event.preventDefault();
    const text = this.state.input;
    this.setState({
      reversedText: text
        .split("")
        .reverse()
        .join("")
    });
  };

  render() {
    return (
      <React.Fragment>
        { /* handleReverse() is called when the form is submitted */ }
        <form onSubmit={this.handleReverse}>
          <div>
            { /* Render input entered */}
            <label>Text: {this.state.input}</label>
          </div>
          <div>
           { /* handleChange() is triggered when text is entered */ }
            <input
              type="text"
              value={this.state.input}
              onChange={this.handleChange}
              placeholder="Enter a text"
            />
          </div>
          <div>
            <button>Reverse Text</button>
          </div>
        </form>
        { /* Render reversed text */}
        <p>Reversed Text: {this.state.reversedText}</p>
      </React.Fragment>
    );
  }
}}

See the Pen React Event Pen – form by Kingsley Silas Chijioke (@kinsomicrote) on CodePen.

Listening to component events

Let’s say you have a component like this;

class IncrementButton extends React.Component{
  render() {
    return (
      <React.Fragment>
        <button>+</button>
      </React.Fragment>
    )
  }
}

Will including it in your App component like this work?

class App extends React.Component{
  state = {
    count: 0
  }

  handleIncrement = (event) => {
    this.setState({ count: this.state.count + 1})
  }

  render() {
    return(
      <React.Fragment>
        <h1>{this.state.count}</h1>
        <IncrementButton onClick={this.handleIncrement} />
      </React.Fragment>
    )
  }
}

No, it won’t because you can only listen to events on DOM elements. We touched on this at the beginning of the post, but React components are wrappers for DOM elements. That means we essentially have a layer that we need to pass through to listen for the event.

The way around this is to pass the event handler as a prop to the child component. Then the prop is passed down to the click event as an attribute like so:

class IncrementButton extends React.Component{
  render() {
    return (
      <React.Fragment>
        <button onClick={this.props.increaseButton}>+</button>
      </React.Fragment>
    )
  }
}

class App extends React.Component{
  state = {
    count: 0
  }

  handleIncrement = (event) => {
    this.setState({ count: this.state.count + 1})
  }

  render() {
    return(
      <React.Fragment>
        <h1>{this.state.count}</h1>
        <IncrementButton increaseButton={this.handleIncrement} />
      </React.Fragment>
    )
  }
}

See the Pen React Event Pen – Component Events by Kingsley Silas Chijioke (@kinsomicrote) on CodePen.

You could make use of a stateless functional component instead:

const IncrementButton = (props) => {
  return (
    <React.Fragment>
      <button onClick={props.increaseButton}>+</button>
    </React.Fragment>
  )
}

Adding event listeners

There may be times when you want to make use of certain DOM events that are triggered when the component is mounted. Let’s see this using the resize event — we want to see the width of the window whenever it is resized.

class App extends React.Component{
  state = {
    windowWith: window.innerWidth
  }

  handleResize = (event) => {
    this.setState({ windowWith: window.innerWidth })
  }

  render() {
    return(
      <React.Fragment>
        <h1>Window Width</h1>
        <h1>{this.state.windowWith}</h1>
      </React.Fragment>
    )
  }
}

If we create a component and try it out like we have below, then the event will not be triggered. We’ll need to add the event listener (handleResize() in this case) and the event type like we have here:

class App extends React.Component{
  state = {
    windowWith: window.innerWidth
  }

  handleResize = (event) => {
    this.setState({ windowWith: window.innerWidth })
  }
  
  componentDidMount() {
    window.addEventListener('resize', this.handleResize)
  }

  componentDidUnmount() {
    window.removeEventListener('resize', this.handleResize)
  }

  render() {
    return(
      <React.Fragment>
        <h1>Window Width</h1>
        <h1>{this.state.windowWith}</h1>
      </React.Fragment>
    )
  }
}

See the Pen React Event Pen – addEventListener by Kingsley Silas Chijioke (@kinsomicrote) on CodePen.

Now, the event listener will be added when the component mounts. That means our component is actively listening to the browser window and will display its width when it updates.

In summary

OK, so we covered quite a bit of ground in a very small amount of space. We learned that React does not connect directly to a DOM event, but rather Synthetic Events that are wrappers for DOM events. We dug into the process for creating event listeners so that they attach to Synthetic Events and, from there, made sure that a component will update when those events are triggered.

Additional resources

The post Working With Events in React appeared first on CSS-Tricks.

The Complete CSS Demo for OpenType Features

Post pobrano z: The Complete CSS Demo for OpenType Features

I’m very glad a guide for these features exists because we already know there are so many weird things that variable fonts can do — well done, Tunghsiao Liu!

There are quite a few possible values for font-feature-settings, like, ya know:

aalt, swsh, cswh, calt, hist, hlig, locl, rand, nalt, cv01-cv99, salt, subs, sups, titl, rvrn, liga, dlig, size, ornm, ccmp, kern, mark, mkmk, smcp, c2sc, pcap, c2pc, unic, cpsp, case, ital, ordn, lnum, onum, pnum, tnum, frac, afrc, dnom, numr, sinf, zero, mgrk, flac, dtls, ssty, ss01-ss20, smpl, trad, tnam, expt, hojo, nlck, jp78, jp83, jp90, jp04, hngl, ljmo, tjmo, vjmo, fwid, hwid, halt, twid, qwid, pwid, palt, pkna, ruby, hkna, vkna, rlig, init, medi, and fina

…to name a few.

Direct Link to Article — Permalink

The post The Complete CSS Demo for OpenType Features appeared first on CSS-Tricks.

The Ecological Impact of Browser Diversity

Post pobrano z: The Ecological Impact of Browser Diversity

Early in my career when I worked at agencies and later at Microsoft on Edge, I heard the same lament over and over: „Argh, why doesn’t Edge just run on Blink? Then I would have access to ALL THE APIs I want to use and would only have to test in one browser!”

Let me be clear: an Internet that runs only on Chrome’s engine, Blink, and its offspring, is not the paradise we like to imagine it to be.

As a Google Developer Expert who has worked on Microsoft Edge, with Firefox, and with the W3C as an Invited Expert, I have some opinions (and a number of facts) to drop on this topic. Let’s get to it.

What is a browser, even?

Let’s clear up some terminology.

Popular browsers you know today include Google Chrome, Apple Safari, Mozilla Firefox, and Microsoft Edge, but in the past we’ve also had such greats as NCSA Mosaic and Netscape Navigator. Whichever browser you use daily (I use Firefox, thanks for asking) is only an interface layer wrapped around a browser engine. All your bookmarks, the forward and backward arrows, that URL bar thingy—those aren’t the browser. Those are the browser’s interface. Often the people who build the browser’s engine never even touch the interface!

Browser engines are the things that actually read all the HTML and CSS and JavaScript that come down across the Internet, interpret them, and display a pretty picture of a web page for you. They have their own names. Chrome’s engine is Blink. Safari runs on WebKit. Firefox uses Gecko. Edge sits on top of EdgeHTML. (I like this naming convention. Good job, Edge.)

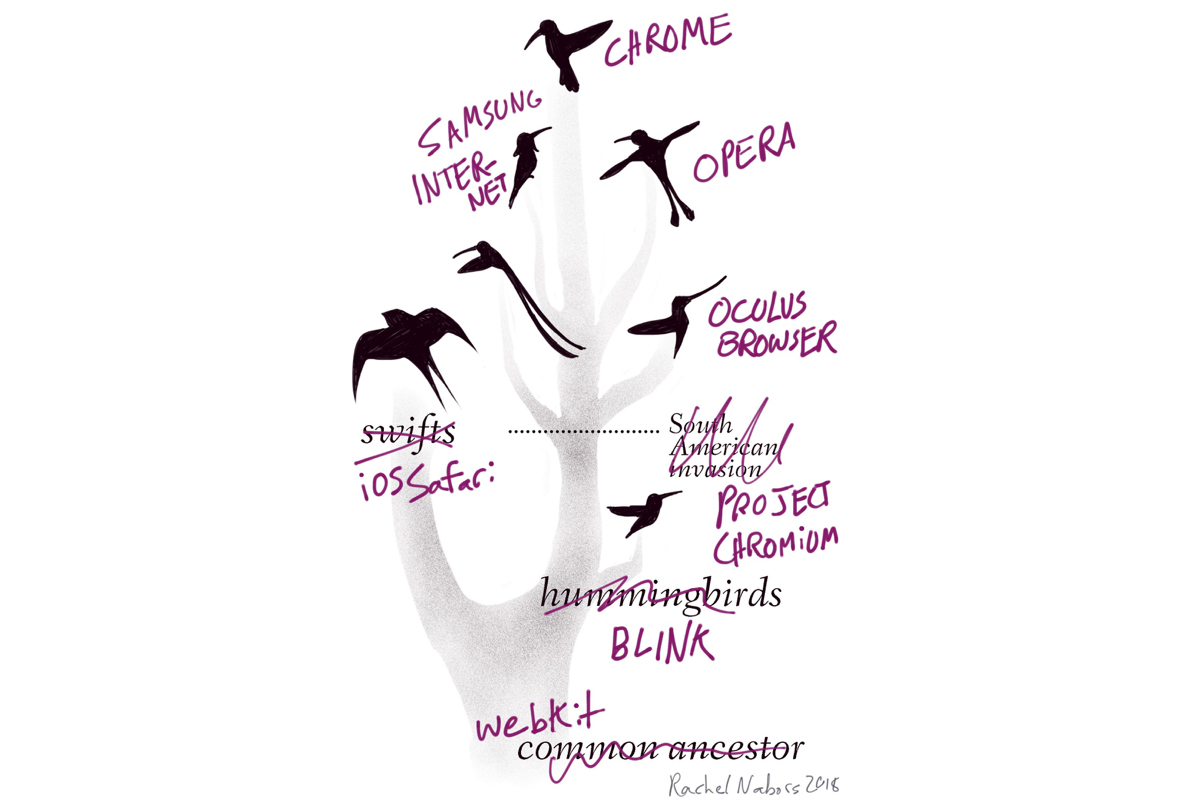
Except for Edge, all of these engines are open source, meaning anybody could grab one, wrap it in a new interface, and boom, release their own browser—maybe with a different (perhaps better) user experience—and that’s just what some browsers are! Oculus Browser, Brave, Vivaldi, Samsung Internet, Amazon’s Silk, and Opera all run on Blink. We call them “Chromium-based browsers”—Chromium is Google’s open source project from which Chrome and its engine emerged.

But what’s inside a browser engine? MOAR ENGINES! Every browser engine is comprised of several other engines:

  • A layout and rendering engine (often so tightly coupled that there’s no distinction) that calculates how the page should look and handles any paints, renders, and even animations.
  • A JavaScript engine, which is its own thing and can even run independently of the browser altogether. For instance, you can use Chrome’s V8 engine or Microsoft Edge’s Chakra to run Node on a server.

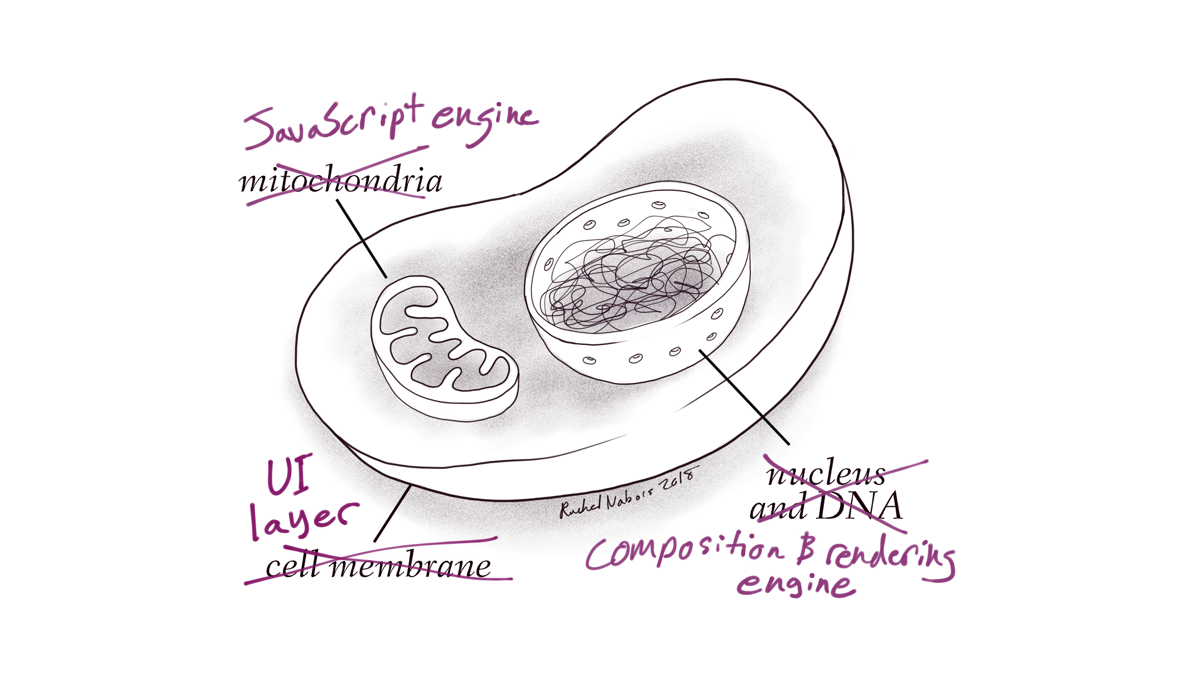
I like to compare browser engines to biological cells. Where a cell contains many organelles to perform different functions, so too do browsers. One can think of the nucleus as the rendering engine, containing the blueprints for how the page should display, and the mitochondria as the JavaScript engine, powering our everyday interactions. (Fun fact: mitochondria used to be standalone cells at one point, too, and they even carry their own DNA!)

And you know what? Another way browsers are like living things is that they evolve.

Browser evolution

Back when the first browsers came out, it was a simpler time. CSS was considered the hot new thing when it first appeared in Microsoft Internet Explorer 3 in 1996! There were far fewer JavaScript APIs and CSS specifications to implement than there are today. Over the years, browser codebases have grown to support the number of new features users and developers require to build modern web experiences. It is a delicate evolution between user needs, browser engineering effort, and specification standardization processes.

We have three major lineages of engines right now:

  • WebKit and Blink (Blink originally being a fork of WebKit) running Safari, Chrome, and Opera
  • Gecko running Firefox
  • EdgeHTML (a fork of Trident, aka MSHTML) running Microsoft Edge

Each is very different and has different strengths and weaknesses. Each could pull the Web in a different direction alone: Firefox’s engine has multithreaded processing for rendering blazing fast graphics. Edge’s engine has the least abstraction from the operating system, giving it more direct access to system resources—but making it a Windows-only browser engine as a result. And Chrome’s Blink has the most web developers testing for it. (I’ll get back to why this is a „feature” in a little bit.)

Remember all those Chromium-based browsers we talked about? Well, none of these browsers have to build their rendering engine or JavaScript engines from scratch: they just piggy-back off of Blink. And if there are new features they need? They can develop those features and keep them to themselves, or they can share those features back “upstream” to become a part of the core engine for other browsers to use. (This process is often fraught with politics and logistics—”contributing back” is easier said than done!)

It is hard to imagine any one entity justifying the hours and expense it would take to spin up a browser engine from scratch today. Even the current three engine families are evolutions of engines that were there from the very start of the Internet. They’ve evolved piecemeal alongside us, growing to meet our needs.

Right now, the vast majority of traffic on the Web is happening on Chrome, iOS Safari, or some other permutation of Blink or WebKit.

Branches, renovations, and gut jobs

Some developers would say that WebKit and Blink were forked so long ago that the two are practically completely different browser engines now, no longer able to share contributions. That may be true to a point. But while a common chimney swift and a ruby-throated hummingbird are completely different animals in comparison to each other, when compared to the other animal families, they are still very much birds. Neither’s immediate offspring are likely to manifest teeth, hands, or tails in the near future. Neither WebKit nor Blink have the processing features that Gecko and EdgeHTML have been building up to for years.

Other developers might point out that Microsoft Edge is supposedly a „complete rewrite” of Internet Explorer. But the difference between a „complete gut job” and a mere „renovation” can be a matter of perspective. EdgeHTML is a fork of Internet Explorer’s Trident engine, and it still carries much of Trident’s backlog with it.

Browser extinction

So these are the three browser engines we have: WebKit/Blink, Gecko, and EdgeHTML. We are unlikely to get any brand new bloodlines in the foreseeable future. This is it.

If we lose one of those browser engines, we lose its lineage, every permutation of that engine that would follow, and the unique takes on the Web it could allow for.

And it’s not likely to be replaced.

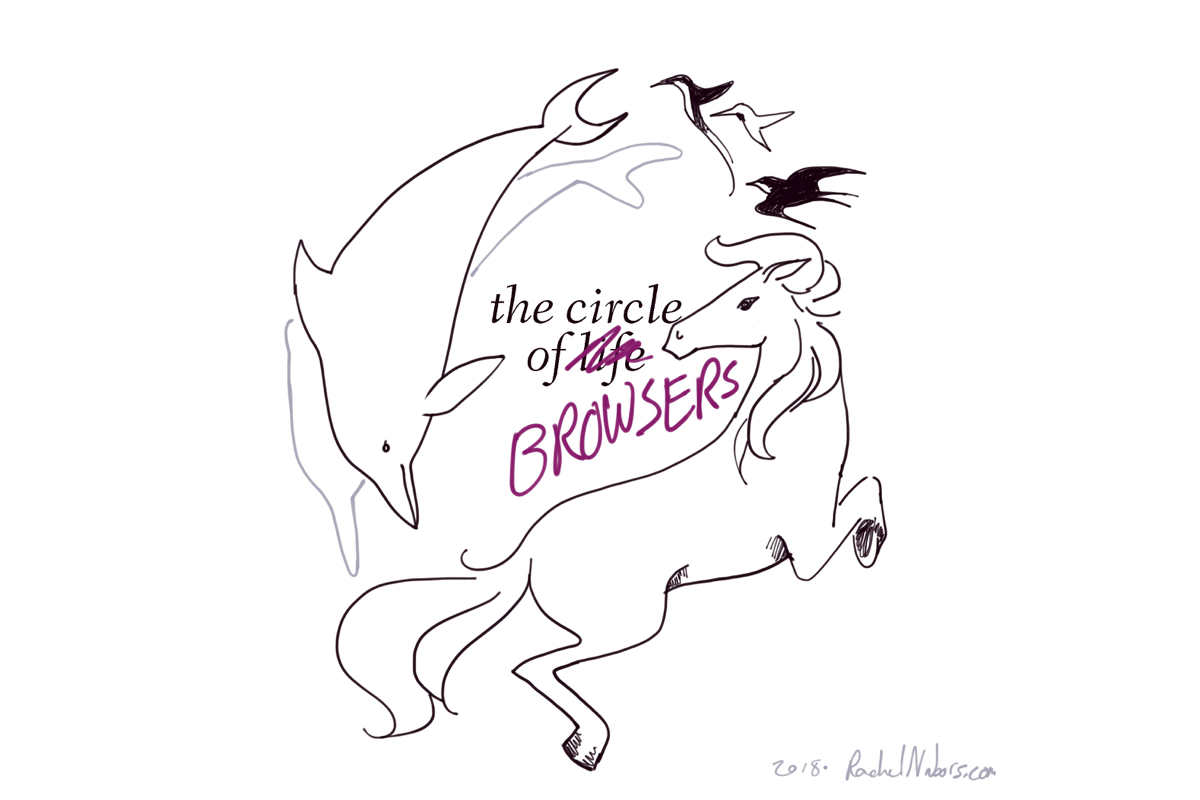
Imagine a planet populated only by hummingbirds, dolphins, and horses. Say all the dolphins died out. In the far, far future, hummingbirds or horses could evolve into something that could swim in the ocean like a dolphin. Indeed, ichthyosaurs in the era of dinosaurs looked much like dolphins. But that creature would be very different from a true dolphin: even ichthyosaurs never developed echolocation. We would wait a very long time (possibly forever) for a bloodline to evolve the traits we already have present in other bloodlines today. So, why is it ok to stand by or even encourage the extinction of one of these valuable, unique lineages?

We have already lost one.

We used to have four major rendering engines, but Opera halted development of its own rendering engine Presto before adopting Blink.

Three left. Spend them wisely.

By our powers combined…

Some folks feel that if a browser like Microsoft Edge ran on Blink, then Microsoft’s engineers could help build a better Blink, contributing new features upstream for all other Chromium browsers to benefit from. This sounds sensible, right?

But remember Blink was forked from WebKit. Now there are WebKit contributors and Blink contributors, and their contributions don’t port one to one. It’s not unlikely that a company like Microsoft would, much like Samsung and Occulus, want to do things with the engine differently from Google. And if those differences are not aligned, the company will work on a parallel codebase and not contribute that work upstream. We end up with a WebKit and a Blink—but without the deep differentiation that comes from having a codebase that has been growing with the Internet for decades.

It’s is a nice idea in theory. But in practice, we end up in a similar pickle—and with less „genetic variety” in our ecosystem of browser engines.

Competition is about growing, not „winning”

I’m a fan of competition. Competing with other cartoonists to make better comics and reach a larger audience got me to where I am today. (True story: got my start building websites as a cartoonist building her own community site, newsletter, and shopping cart.) I like to remind people that competition isn’t about annihilating your competitors. If you did, you’d stagnate and lose your audience: see also Internet Explorer 6.

Internet Explorer 6 was an amazing browser when it came out: performant enough to really deliver on features previous versions of Internet Explorer introduced like the DOM, data-binding, and asynchronous JavaScript. It’s rival, Netscape Navigator, couldn’t compete and crumbled into dust (only to have its engine, Gecko, rewritten from scratch—it was that small!—by the Mozilla Foundation to be reborn as Firefox later).

Thinking it had Won the Internet, Microsoft turned its attention to other fronts, and Internet Explorer didn’t advance much. When the iPhone came, Apple focused on its profitable apps marketplace and cut efforts to support Flash—the Web’s most app-like interaction platform. Apps gave content creators a way to monetize their efforts with something other than an advertising model. Advertising being Google’s bread and butter, the Big G grew concerned as the threat of a walled garden of apps only using the Internet for data plumbing loomed. Microsoft, meanwhile, was preoccupied with building its own mobile OS. So Google did two things: Android and Chrome.

Chrome promised a better, faster browsing experience. It was barebones, but Google even went all out and got famous (in my circles at least) cartoonist Scott McCloud to make a comic explaining the browser’s mission to users. With Chrome’s omnipresence on every operating system and Android phone, its dev tools modeled off Firefox’s beloved Firebug extension, and increasing involvement in specs, Chrome not only shook Internet Explorer out of its slumber, it was damn near threatening to kill off every other browser engine on the planet!

Pruning the great family tree of browsers (or collection of bushes as it were) down to a single branch smacks of fragile monoculture. Monocultures are easily disrupted by environmental and ecological challenges—by market and demographic changes. What happens when the next threat to the Web rears its head, but we don’t have Firefox’s multithreading? Or Microsoft Edge’s system integration? Will we be able to iterate fast enough without them? Or will we look to the Chrome developers to do something and pray that they have not grown stagnant as Google turned, like Microsoft did, to attend to other matters after „winning the Web.”

It is ironic that the browser Google built to keep the Web from losing to the apps model is itself monopolizing web development much the same way Internet Explorer 6 did.

It’s good to be king (of the jungle)

I promised I’d get back to „user base size as a feature.” Having the vast majority of the web development community building and testing for your platform is a major competitive advantage. First off, you’re guaranteed that most sites are going to work perfectly in your browser—you won’t have to spend so much time and effort tapping Fortune 500 sites on the shoulder about this One Weird Bug that is causing all their internal users to switch to your competitor browser and never come back. A downward spiral of fewer users leading to less developer testing leading to fewer users begins that is hard to shake.

It also makes it much easier to propose new specifications that serve your parent company’s goals (which may or may not serve the web community’s goals) and have that large community of developers build to your implementation first without having to wait for other browsers to catch up. If a smaller browser proposes a spec that no one notices and you pick it up when you need it, people will remember it as being your effort, continuing to build your mindshare whether intentionally or not.

This creates downward pressure on the competition, which simply doesn’t have or cannot use the same resources the biggest browser team has at its disposal. It’s a brutally efficient method, whether by design or accident.

Is it virtuous? At the individual contributor level, yes. Is it a vicious cycle by which companies have driven their competition to extinction by forcing them to spend limited resources to catch up? Also yes. And having legions of people building for just your platform helps.

All the awesome, well-meaning, genuinely good-hearted people involved—from the Chrome team to web developers—can throw their hands up and legitimately say, “I was just trying to build the Web forward!” while contributing to further a corporate monopoly.

Chrome has the most resources and leads the pack in building the Web forward to the point that we can’t be sure if we’re building the Web we want… or the Web Google wants.

Speculative biology

There was a time when Microsoft bailed out Apple as it was about to sink. This was not because Bill Gates and Steve Jobs were friends—no, Microsoft needed Apple to succeed so there would still be operating system competition. (No business wants to be seen as a monopoly!)

But consider, for a moment, that Apple had died. What would personal computers be like today if we’d only had Linux and Windows left standing? What would mobile computing look like if Apple hadn’t been around to work on the iPhone?

Yes, it’s easier to develop and test in only one browser. I’m sure IT professionals would have loved to only support one kind of machine. But variety creates opportunity for us as developers in the long run. Microsoft saving Apple lead to apps which challenged the Web which gave us Chrome and the myriad of APIs Google is charging ahead with. If at any point in this chain of events someone had said, „Meh, it’s so much easier if we all use the same thing,” we wouldn’t have the careers—or the world—that we have now.

Develop in more than one browser. Test in more than one browser. Use more than one browser.

You are both consumer and producer. You have a say in how the future plays out.

The post The Ecological Impact of Browser Diversity appeared first on CSS-Tricks.

JAMstack_conf

Post pobrano z: JAMstack_conf

I love a good conference that exists because there is a rising tide in technology. JAMstack_conf:

Static site generators, serverless architectures, and powerful APIs are giving front-end teams fullstack capabilities — without the pain of owning infrastructure. It’s a new approach called the JAMstack.

I’ll be speaking at it! I’ve been pretty interested in all this and trying to learn and document as much as I can.

Save $100 with csstricks100.

Direct Link to Article — Permalink

The post JAMstack_conf appeared first on CSS-Tricks.

Props and PropTypes in React

Post pobrano z: Props and PropTypes in React

React encourages developers to build by breaking a UI up into components. This means there will always be a need to pass data from one component to another — more specifically, from parent to child component — since we’re stitching them together and they rely on one another.

React calls the data passed between components props and we’re going to look into those in great detail. And, since we’re talking about props, any post on the topic would be incomplete without looking at PropTypes because they ensure that components are passing the right data needed for the job.

With that, let’s unpack these essential but loaded terms together.

Props: The data being passed around

Basically, props are what make React the tool that it is. React was designed to break things down into pieces that are served when they are needed. Props are defining characteristics stored by those pieces and they are accessed and sent when they’re requested. The result is a screen that renders only what it needs and nothing more, speeding up page loads and boosting overall performance.

These data can come in different forms: namely, strings, array and functions. The ability to pass data between components, so let’s break down specifically how to access and pass data.

Passing and accessing props

Let’s say we are working on an application that shows a list of interesting demos pulled from CodePen:

See the Pen Props Pen by Kingsley Silas Chijioke (@kinsomicrote) on CodePen.

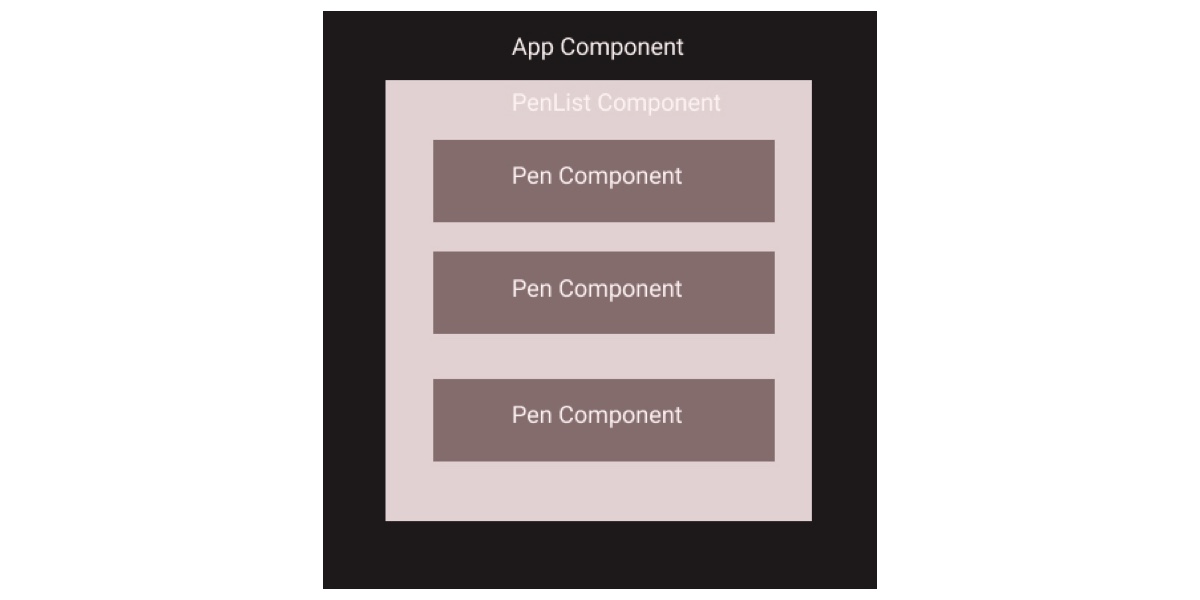
We can illustrate the app as a collection of components:

The list of pens is going to require data, notably the title, URL and author for each demo that the app displays. We can construct that data like so:

const pensList = [
  {
    title: "Elastic Input[Google Chrome]",
    url: "https://codepen.io/andreasstorm/pen/JBGWBa",
    author: "Andreas Storm"
  },
  {
    title: "Phenomenon instances!",
    url: "https://codepen.io/cvaneenige/pen/ajNjaN",
    author: "Colin van Eenige"
  },
  {
    title: "cpc-forms experiment with css variables",
    url: "https://codepen.io/terabaud/pen/YjwYKv",
    author: "Lea Rosema"
  },
  {
    title: "Nuotron Logo Animation with Hover Effect",
    url: "https://codepen.io/YahiaRefaiea/pen/YjyZLm",
    author: "Yahia Refaiea"
  }
];

The App component will pull the data. Here’s the basic structure for that component:

const App = () => {
  return (
    <div>
      <PenList pens={pensList} />
    </div>
  );
}

We are passing an array of pens as a prop to the PenList (which we’ll create in just a bit). The parent component (PenList) accesses the data (penList), which gets passed as pens props to the child component (Pen).

const PenList = props => {
  return (
    <React.Fragment>
      <h2>Interesting Pens on CodePen</h2>
      <ul>
        {props.pens.map(pen => {
          return (
            <li key={pen.url}>
              <Pen {...pen} />
            </li>
          );
        })}
      </ul>
    </React.Fragment>
  );
};

The PenList component loops through the pens props (props.pens) to return each item as a Pen component. If this was a class component, we would prefix the pens props with this, like this:

class PenList extends React.Component {
  render() {
    return (
      <React.Fragment>
        <h2>Interesting Pens on CodePen</h2>
        <ul>
          {
            this.props.pens.map(pen => {
              return (
                <li key={pen.url}>
                  <Pen {...pen} />
                </li>
              )
            })
          }
        </ul>
      </React.Fragment>
    )
  }
}

The next thing to note is the use of key in the example. A key is a unique identifier we can assign to each item in our list to make sure we can distinguish between items. In this case, we’re mapping the key to the URL of each pen. There’s no chance of two items being the same, so it’s a good piece of data to use for this purpose.

The remaining properties are passed as props to the Pen component. Here’s the Pen component making use of those props:

const Pen = props => {
  return (
    <div>
      <p>
        [{props.title}]
      </p>
      <p>Made by: {props.author}</p>
    </div>
  );
};

Note that we are constructing the Pen component (const Pen) rather than defining it as a class (class PenList) like we did for the PenList component. As such, we can access the values using props. That’s a handy little shorthand we can use instead of re-mapping Pen to the data. The parent already has it, so let’s just pass it along!

Passing functions using props

We just looked at passing an array of data as props from one component to another, but what if we’re working with functions instead? React allows us to pass functions between components, but it’s quite technical. Still, it’s something you’d want to do for specific use cases and worth us looking into.

Let’s use a simple example, say an app that allows you to create a list of tasks. You know, a to-do list, like for chores, projects or what have you. In this app, the list of tasks is contained in the App component, which is the parent component. The Todo component will be the child in this scenario, and its sole job will be to list each task that gets created.

In true to-do list form, we don’t just want to create tasks, but be able to remove them once a task has been created. Since the to-do list is contained in the App component, we have to be able to identify the specific item the user wants to remove from the list by obtaining the id and then remove the item in the App component.

Sound complex? Here’s what we’re going for:

See the Pen Props Pen 2 by Kingsley Silas Chijioke (@kinsomicrote) on CodePen.

Broken down into code:

let todoCounter = 1;

class App extends React.Component {
  state = {
    list: [],
    item: ""
  };

  handleInputChange = event => {
    this.setState({ item: event.target.value });
  };

  handleSubmit = event => {
    event.preventDefault();
    const item = {
      id: todoCounter++,
      value: this.state.item.slice()
    };
    this.setState({
      list: this.state.list.concat(item),
      item: ""
    });
  };

  handleRemove = id => {
    this.setState({
      list: this.state.list.filter(c => c.id !== id)
    });
  };

  render() {
    return (
      <React.Fragment>
        <h2>Add Todo</h2>
        <div>
          <input
            type="text"
            value={this.state.item}
            onChange={this.handleInputChange}
          />
        </div>
        <div>
          <button type="submit" onClick={this.handleSubmit}>
            Add
          </button>
        </div>
        <div>
          <h3>Lists</h3>
          <ul>
            {this.state.list.map(item => {
              return (
                <li key={item.id}>
                  <Todo {...item} removeTodo={this.handleRemove} />
                </li>
              );
            })}
          </ul>
        </div>
      </React.Fragment>
    );
  }
}

Notice that we defined todoCounter at the top and set it to 1. We created this so we can have unique keys for the to-do items just like we did when we used URLs for the list of pens in our previous example.

The method for deleting tasks is created in the App component. In the render() function, we pass the to-do properties as props to the Todo component. We also pass the handleRemove() function as a prop named removeTodo(). We will use this in the Todo component which looks like this.

class Todo extends React.Component {
  deleteTodo = id => {
    this.props.removeTodo(id);
  };
  render() {
    return (
      <div>
        {this.props.value}
        <button onClick={() => this.deleteTodo(this.props.id)}>X</button>
      </div>
    );
  }
}

We have to pass the id of the to-do item to removeTodo() in the Todo component because we cannot update the state of the App component without it. This is essentially how we are able to pass a function between components using props — pretty similar to how we did it with an array, the difference being we’re passing functionality around instead of raw data.

PropTypes

PropTypes ensure that the right type of props is passed to a component — and, conversely, that the receiving component is receiving the right type of props.

We can think about them like a football quarterback passing the ball to a receiver. The quarterback only wants his players to receive the ball. And, for that matter, the quarterback wants the receiver to catch a ball — not a cat, pickle or taxi. PropTypes would ensure that the correct object (a ball) is being passed and that it is passed to the correct receiver (player on the team).

(If only football had PropTypes in real life!)

To make use of PropTypes, you have to add the package as a dependency to your application by running yarn add prop-types in the command line.

We can use PropTypes in our app that displays interesting pens. Here is how we will use it for the Pen component:

Pen.propTypes = {
  title: PropTypes.string,
  url: PropTypes.string,
  author: PropTypes.string
};

We’re declaring that the props for title, url and author should be strings. Not numbers. Not functions. Strings and strings alone.

If we happened to the props of author to a number instead of a string like this:

author: PropTypes.number

…we will get an error:

Warning: Failed prop type: Invalid prop `author` of type `string` supplied to `Pen`, expected `number`.

So, PropTypes are useful in catching bugs. We can also enforce passing props by using isRequired:

Pen.propTypes = {
  title: PropTypes.string.isRequired,
  url: PropTypes.string.isRequired,
  author: PropTypes.string.isRequired
};

The basic data types you will need include string, number, boolean, function, etc.

Person.propTypes = {
  email: PropTypes.string,
  age: PropTypes.number,
  availability: PropTypes.bool,
  handleSubmit: PropTypes.func
}

There are more types available and tons of documentation on them.

In cases where a prop is optional (i.e. not using isRequired), you can set a default value to make sure something gets passed:

Developer.defaultProps = {
  language: 'JavaScript' 
}

With this, the language prop will always have a value when it used — even if one isn’t provided.

Wrap Up

Well, that’s a broad look at props in React. It’s pretty much a guarantee that you will use both props and propTypes in a React application. Hopefully this post shows just how important they are to React as a whole because, without them, we have nothing to pass between components when interactions happen. They’re very much a core part of the component-driven and state management architecture that React is designed around.

And propTypes are an added bonus — like a built-in quality assurance checker for catching bugs and letting us know about them. Nice to know that they’ve got our back as we work.

The post Props and PropTypes in React appeared first on CSS-Tricks.